

Fix Adobe Acrobat OCR Not Recognizing Every Page in a Large PDF

Question details
The user needs to successfully perform Optical Character Recognition (OCR) on every page of a large PDF document (over 200 pages) so that all text becomes searchable.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to search for or extract text from a large PDF that contains a mixture of digital text and scanned image pages.
- Observed behavior
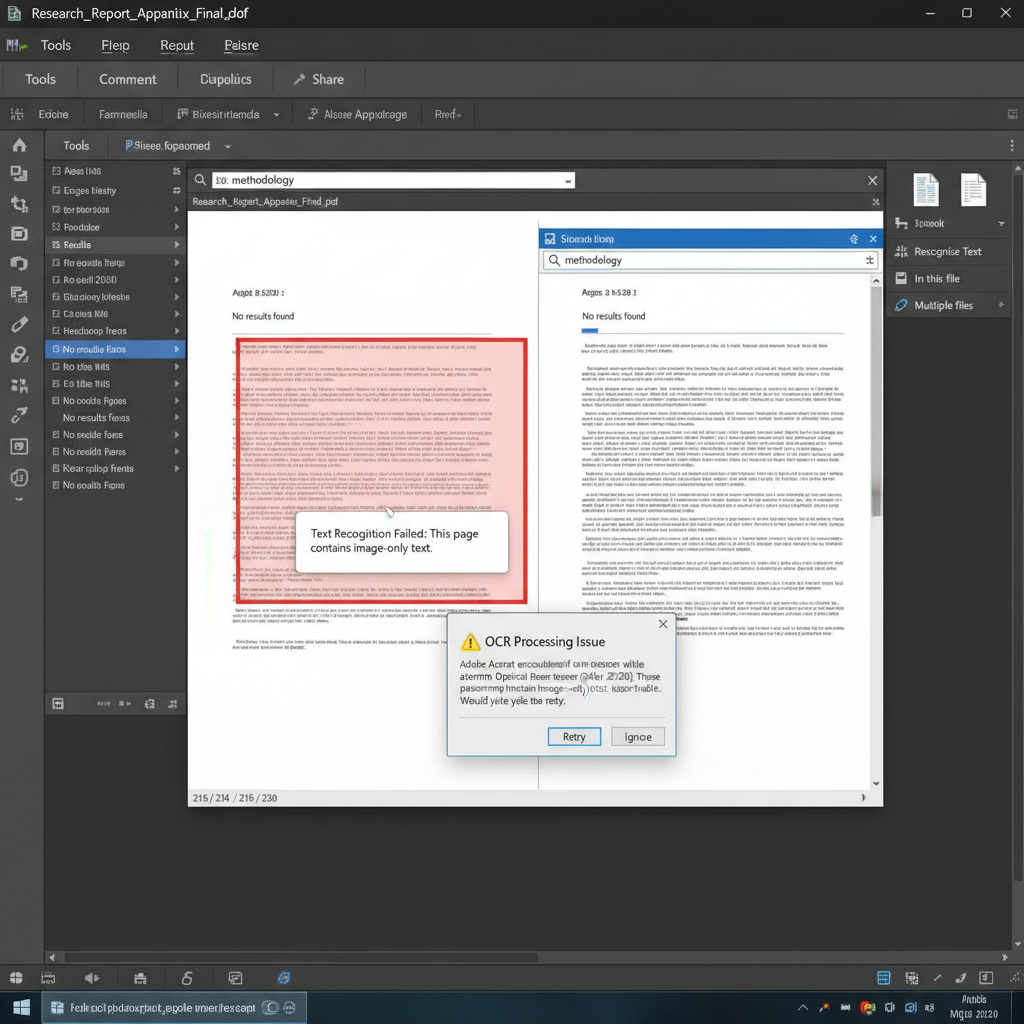
- Adobe Acrobat fails to recognize text on certain pages, particularly appendix pages, leaving them as unsearchable, image-only pages.
Ensure you have the full version of Adobe Acrobat Pro installed, as the free Adobe Acrobat Reader does not include the OCR tools required to make scanned documents searchable.
Manually Run Text Recognition via Enhance Scans
Forcing Acrobat to manually run the Enhance Scans tool on the entire document can process pages that were skipped during automatic background OCR.
Acrobat can sometimes skip heavily compressed scanned images or mixed-content pages when processing large documents. Forcing a manual text recognition pass often forces the OCR engine to evaluate these stubborn pages properly.
Open your large PDF in Adobe Acrobat, navigate to the 'Tools' tab at the top left, and select 'Enhance Scans'.
In the Enhance Scans toolbar, click on 'Recognize Text' and choose 'In This File' from the dropdown menu.
Click 'Settings' to ensure the correct document language is selected and set the output style to 'Searchable Image'.
Click the 'Recognize Text' button to start processing the entire document. Verify the result page by page once completed.
Optimize Source Images Using TIFF Format
Improving the quality of the source images before combining them into a PDF significantly improves OCR consistency.
Easily Extract and Search Text in Large PDFs with WPS Office
WPS Office provides a powerful, built-in OCR feature for PDF documents that can accurately recognize text across multiple pages, including complex scanned images, allowing you to easily extract or search the content.
- 1. Open PDF in WPS Office: Launch WPS Office and open your large PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on 'OCR' or 'Picture to Text'.
- 3. Select Page Range: In the OCR dialog box, specify the page range you want to process, such as selecting the entire document.
- 4. Convert and Extract: Choose whether you want to extract the text to a new Word document or make the current PDF searchable, then click 'Confirm' to begin processing.

Frequently Asked Questions
Why does Acrobat skip pages during OCR?
Acrobat may skip pages if it detects a mix of digital text and heavily compressed scanned images within the same document. JPEG compression artifacts, complex layouts, or low-resolution scans can also cause the OCR engine to bypass certain pages.
How can I convert a PDF to separate TIFF files for better OCR?
You can export a PDF to individual image files directly in Adobe Acrobat by going to File > Export To > Image > TIFF. This will save each page of the PDF as an individual high-quality TIFF file.
Does the image format affect text recognition accuracy?
Yes, highly compressed formats like JPEG introduce visual artifacts that make it difficult for OCR engines to distinguish text characters from background noise. Lossless formats like TIFF retain sharp edges and clear text, significantly improving OCR results.


