

Fix Adobe PDF to CSV Conversion Omitting Pages
Question details
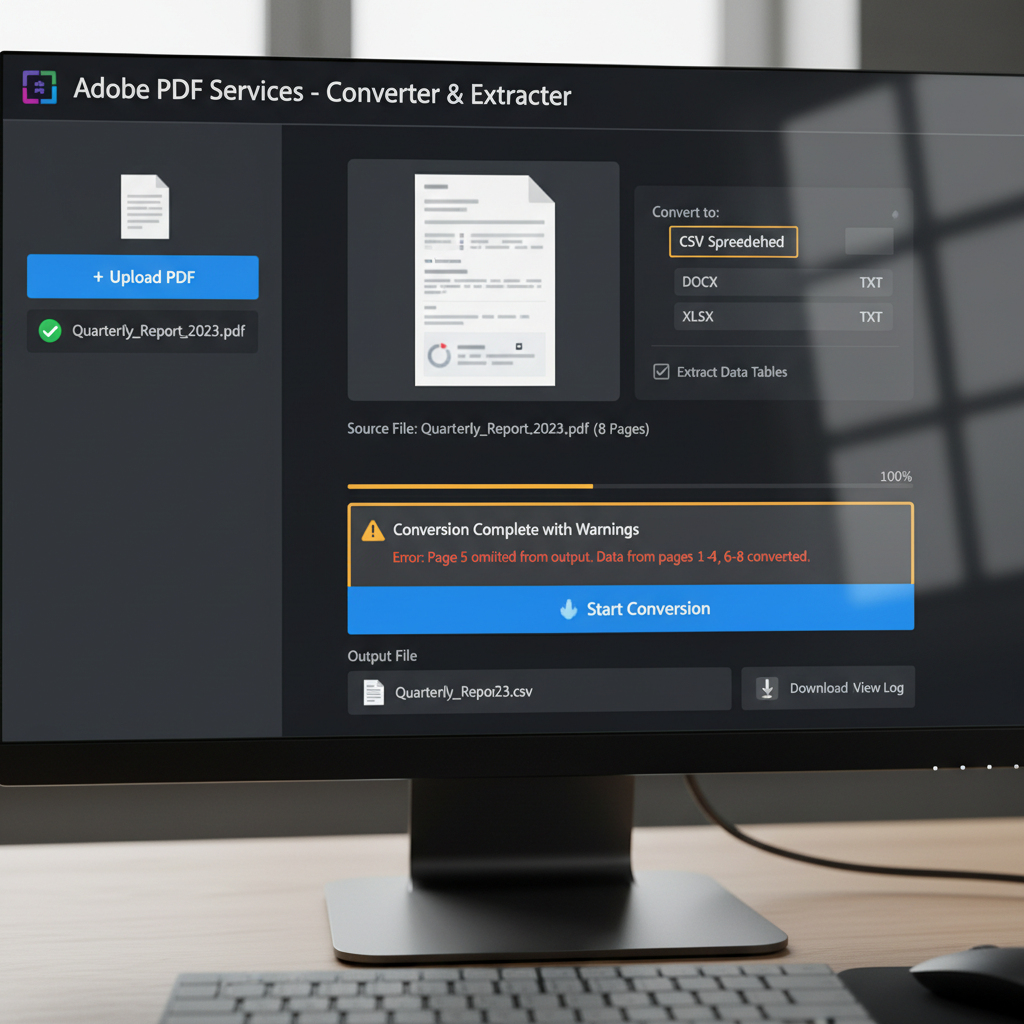
The user is experiencing an issue where Adobe PDF Services intermittently omits an entire page when converting a multi-page PDF into a CSV file.
- Product
- Adobe PDF Services
- Device & OS
- not provided
- Scenario
- Converting multi-page PDF documents into CSV spreadsheet files for data extraction using Adobe Services.
- Observed behavior
- The conversion completes, but specific pages are entirely omitted from the final CSV file while the remaining pages are converted correctly.
Verify that the omitted PDF pages contain actual text rather than scanned images, and check if the document has any specific permission restrictions or encrypted sections.
Inspect PDF Content and Rerun the Conversion Workflow
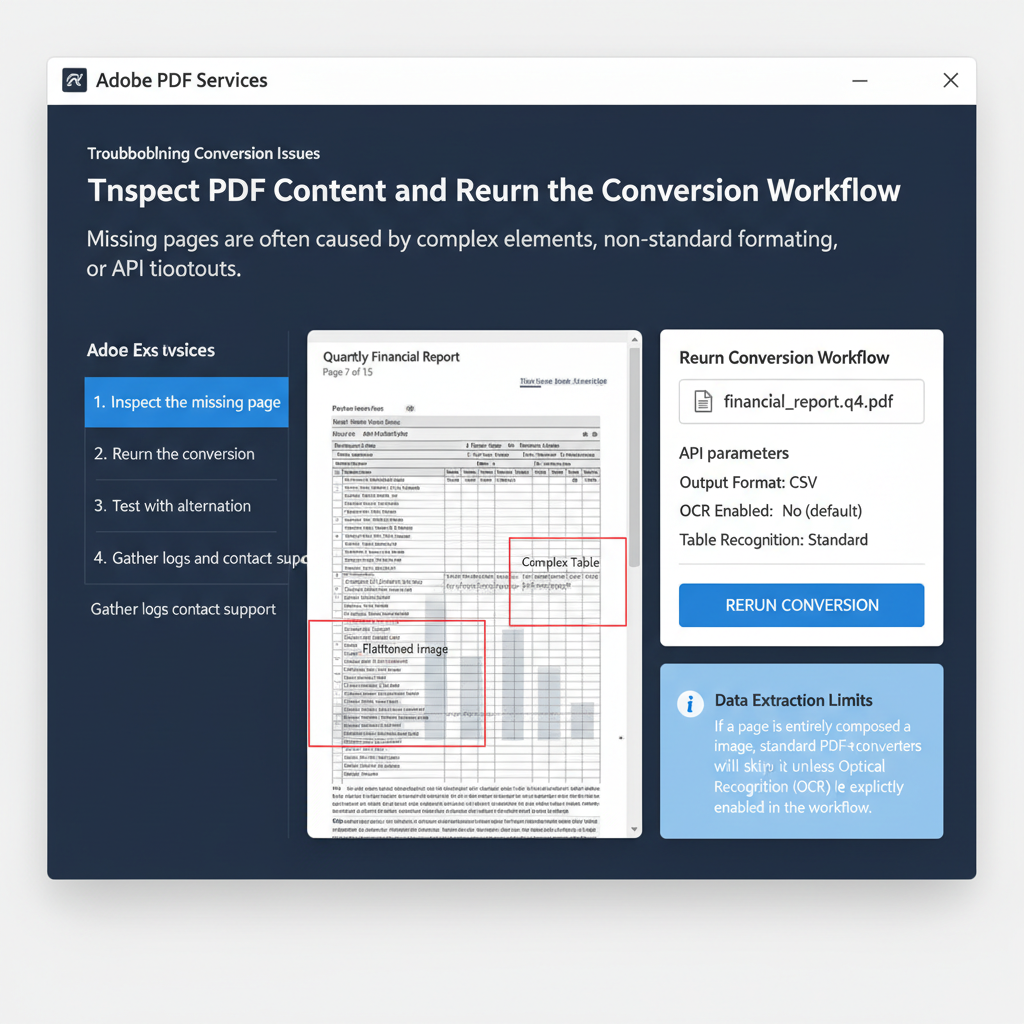
Missing pages are often caused by complex elements, non-standard formatting, or API timeouts. Inspecting the source file and rerunning the process helps isolate the issue.
PDF conversion APIs rely on parsing text structures and tables. If a page contains a flattened image, complex nested tables, or irregular fonts, the engine might skip it.
Systematically troubleshooting the source document and your API request parameters can help identify whether the problem lies with the PDF itself or the conversion service.
Open the original PDF document in a PDF viewer and navigate to the exact page that was omitted. Look for scanned images, highly complex tables, or unusual formatting that might fail table recognition.
Execute the Adobe PDF Services conversion again using the exact same file to determine if the page omission is an intermittent API timeout or a consistent parsing error.
Run the same workflow with a different multi-page PDF. If the other PDF converts perfectly, the issue is specific to the original document's formatting.
If the issue persists consistently, collect the original PDF, the converted CSV, your SDK/API version details, and request logs. Submit these to Adobe Support so the specific omitted page can be investigated.
Seamlessly Convert PDF to CSV with WPS Office
Avoid API timeouts and missing data by using the robust PDF conversion tools built directly into WPS Office. You can accurately extract tables from multi-page PDFs to Excel spreadsheets and easily save them as CSV files without losing entire pages.
- 1. Open the PDF document: Launch WPS Office and click on 'PDF' in the home screen to open your multi-page document.
- 2. Use the PDF to Excel tool: Navigate to the 'Tools' tab on the top ribbon and select the 'PDF to Excel' option.
- 3. Convert the document: Choose the pages you want to extract, set your desired language for better accuracy, and click 'Convert'.
- 4. Save as CSV: Once the extracted data opens in WPS Spreadsheet, click 'Menu' > 'Save As', and select 'CSV (Comma delimited)' from the file format dropdown.
Frequently Asked Questions
Why do some pages fail to convert from PDF to CSV?
Pages often fail to convert if they contain scanned images rather than selectable text, complex nested tables, or unusual formatting that the conversion engine struggles to parse.
Can I convert a scanned PDF page to a CSV file?
Yes, but you must use a PDF conversion tool equipped with Optical Character Recognition (OCR). Without OCR, standard converters will treat the scanned page as a flat image and output a blank or missing section in the CSV.
How do I fix API timeouts during large PDF conversions?
To prevent timeouts that result in dropped pages, try splitting the large PDF into smaller batches before sending them to the API, or increase the timeout limit settings in your SDK request parameters.
Does WPS Office support extracting PDF tables to CSV?
Yes, WPS Office allows you to convert PDF documents directly into spreadsheets. You can use the 'PDF to Excel' tool under the 'Tools' tab to extract the data, and then use 'Save As' to export the file in CSV format.


