

Fix Cannot Highlight Scanned PDFs in Acrobat on iPad

Question details
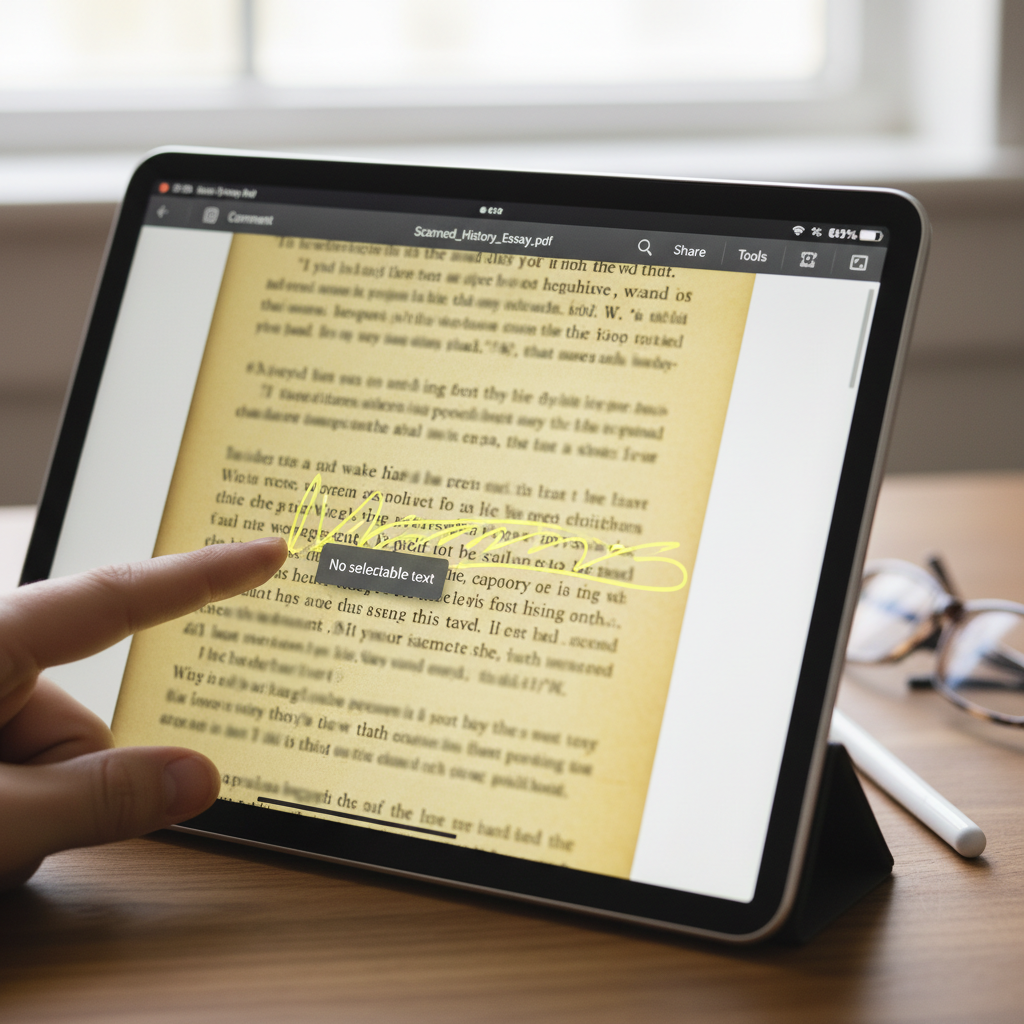
The user is unable to select or highlight text in a scanned PDF document using Adobe Acrobat Pro on an iPad.
- Product
- Adobe Acrobat Pro
- Device & OS
- iPad
- Scenario
- Attempting to annotate and highlight text within a scanned PDF file on a mobile tablet.
- Observed behavior
- The highlighter tool cannot detect or select any text because the document is a scanned image and lacks Optical Character Recognition (OCR).
Verify if your PDF is a flattened scanned image by attempting to long-press and select a single word; if the entire page is selected, the document needs OCR.
Perform OCR on a Desktop Platform
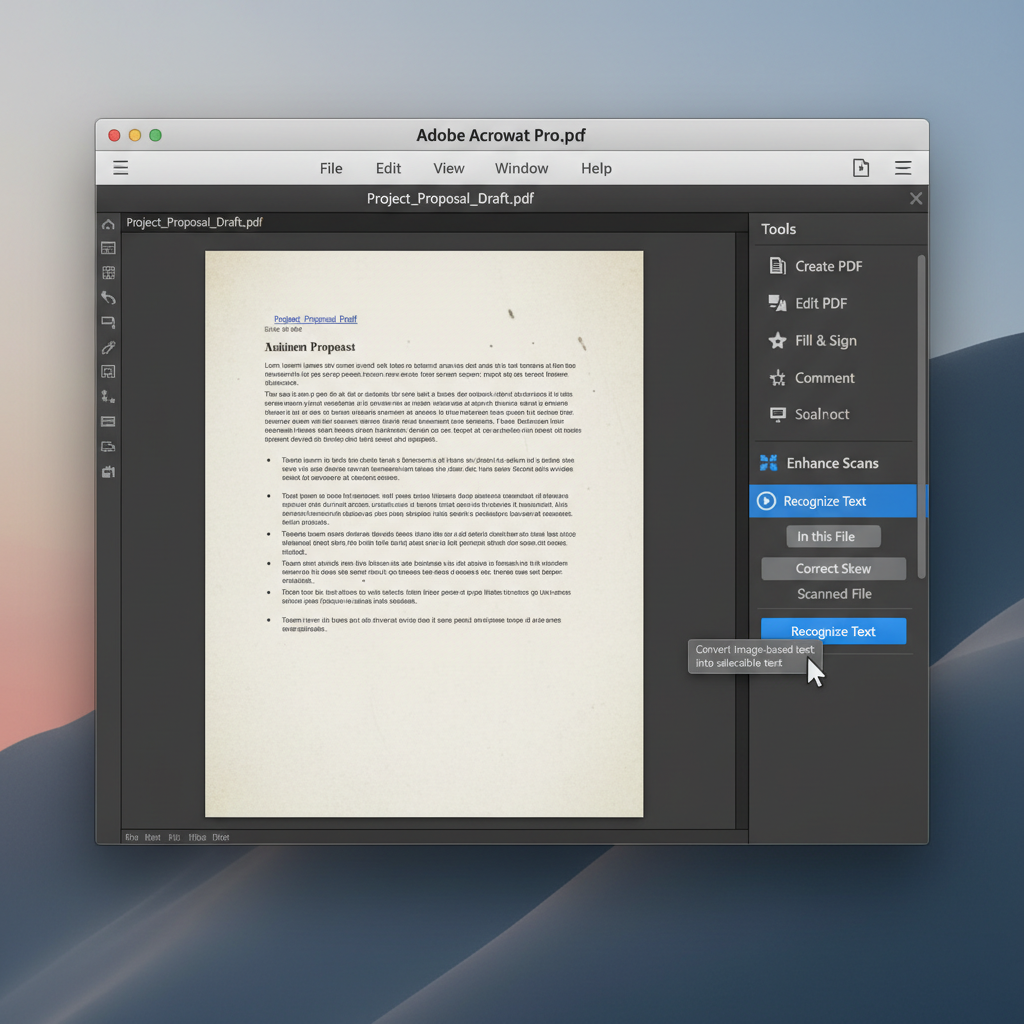
Since the iPad version of Acrobat lacks full OCR capabilities, you must use the desktop version of Acrobat Pro to convert the scanned image into selectable text.
The Adobe Acrobat app for iPad does not include the comprehensive OCR (Optical Character Recognition) engine required to process scanned images into selectable text. You will need to process the file on a desktop computer running Windows or macOS first.
Send the scanned PDF from your iPad to a Windows or macOS desktop computer using cloud storage or email.
Launch the full desktop version of Adobe Acrobat Pro and open your scanned PDF document.
Navigate to 'Scan & OCR' or 'Enhance Scans' from the right-hand tools pane.
Click on 'Recognize Text', choose 'In this File', and click the 'Recognize Text' button to process the document.
Save the newly processed PDF and transfer it back to your iPad. You will now be able to use the highlighter tool on the text.
Use an Online OCR Conversion Tool
If you do not have immediate access to a desktop computer, use a web-based OCR service directly from your iPad browser to make the text highlightable.
Use WPS Office to OCR and Highlight PDFs
WPS Office provides a comprehensive PDF toolkit, including powerful OCR capabilities to recognize text in scanned PDFs and easy-to-use annotation tools for highlighting.
- 1. Open your PDF: Launch WPS Office and open your scanned PDF document.
- 2. Navigate to OCR: Go to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Convert the document: Select the pages you want to process and choose to save them as a searchable PDF document.
- 4. Highlight the text: Navigate to the 'Comment' tab, select the 'Highlight' tool, and drag your cursor over the newly recognized text to highlight it.

Frequently Asked Questions
What is OCR and why do I need it for scanned PDFs?
OCR stands for Optical Character Recognition. It converts static images of text (like those generated by a scanner) into machine-readable text. Without OCR, a scanned PDF is treated as a flat picture, making it impossible to select or highlight individual words.
Can I use OCR in the Adobe Acrobat app on an iPad?
Currently, the mobile iPad version of Adobe Acrobat does not support the full OCR workflow required to convert scanned images into selectable text. This feature relies on the desktop version of Acrobat Pro for Mac or Windows.
How can I tell if my PDF is just a scanned image?
Try using the text selection or highlighter tool on a single word. If the tool selects the entire page as a single image or fails to grab individual letters, the document is a scanned image requiring OCR processing.


