

Fix Incorrect Characters When Copying Numbers from PDF

Question details
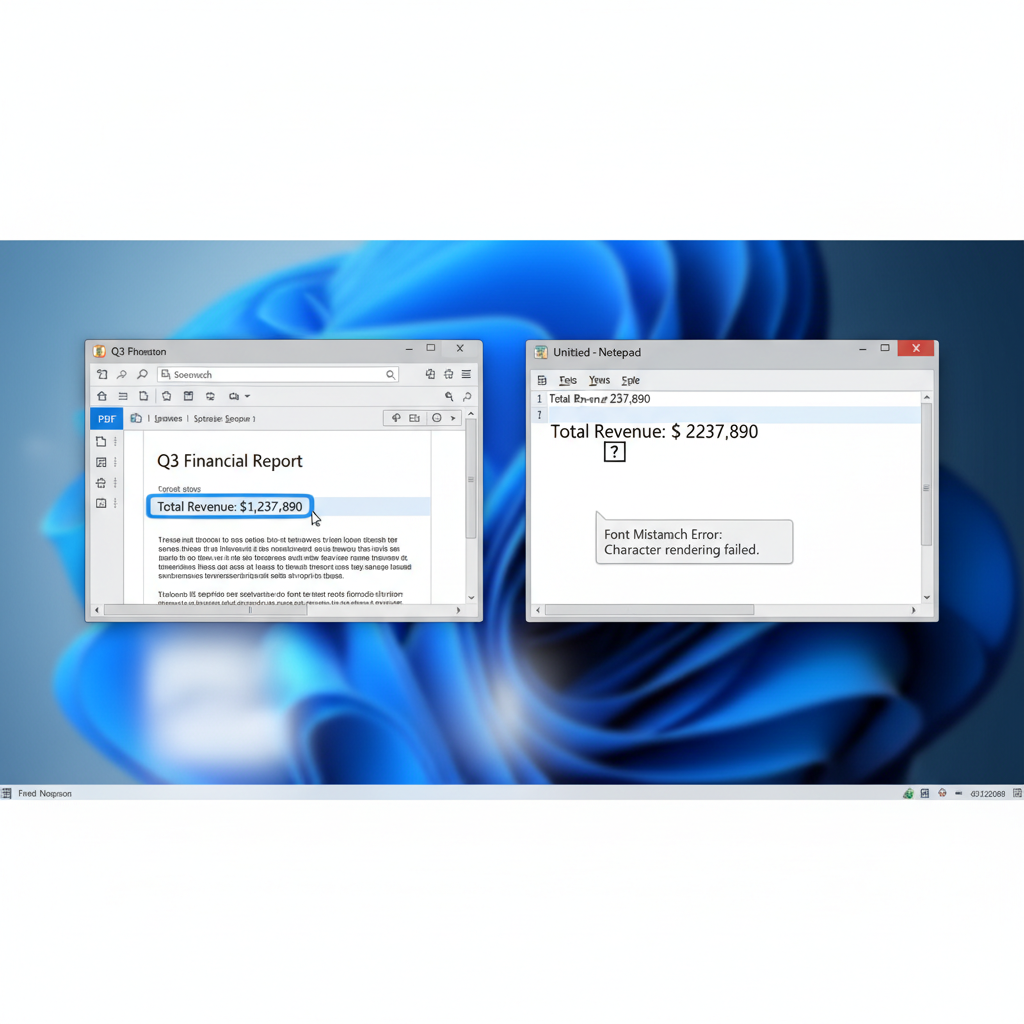
The user experiences an issue where copying a specific digit from a PDF document and pasting it into another application results in an invalid character symbol.
- Product
- Device & OS
- not provided
- Scenario
- Selecting and copying text from a PDF document to paste into a text editor like Microsoft Word or Notepad.
- Observed behavior
- The pasted character appears as a square, a question mark, or another unrecognized symbol instead of the original number, indicating a font mapping error.
Verify whether this issue occurs across multiple different PDF files or is isolated to one specific document, as this helps confirm if the document's internal encoding is the culprit.
Verify Font Encoding and Recreate the PDF
This is the most reliable method when the original source document is available. It resolves the root cause by fixing the font embedding before generating the PDF.
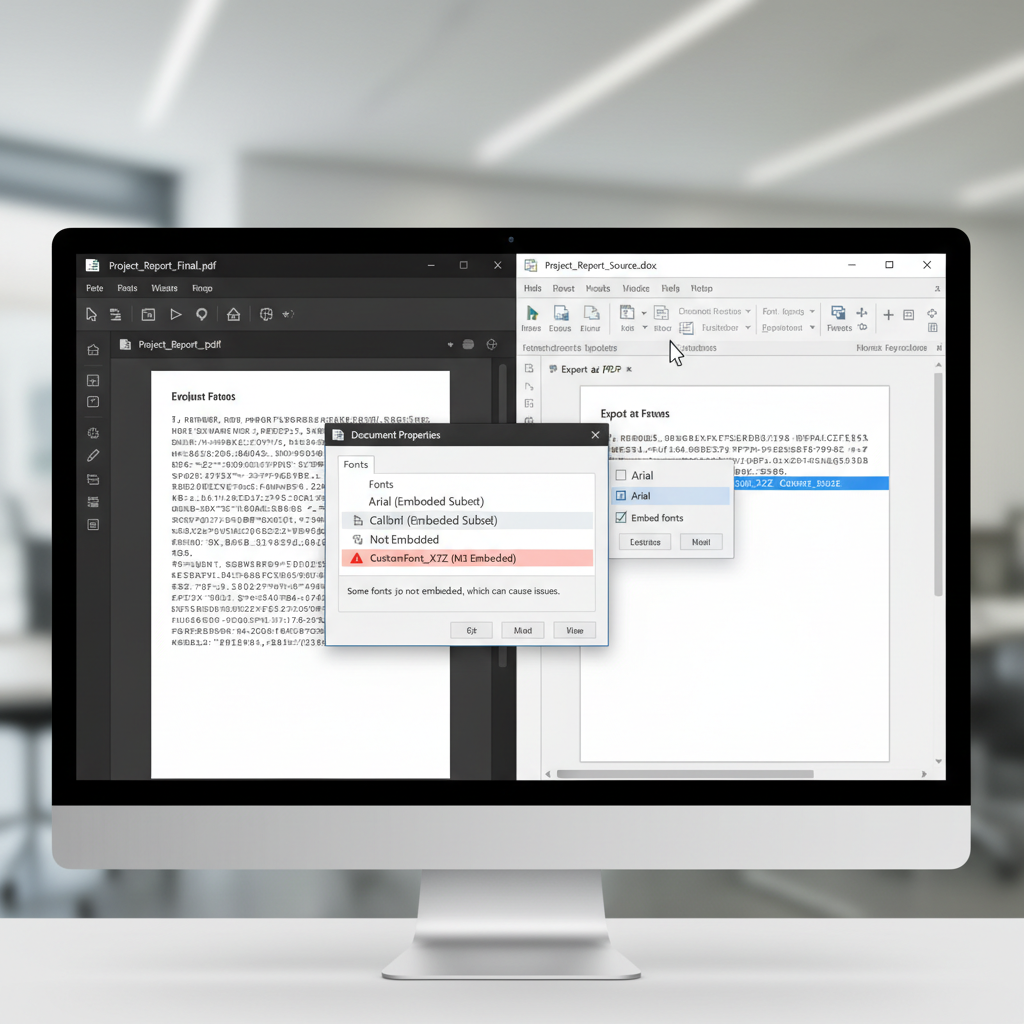
When a PDF is created, fonts must be properly embedded with standard Unicode mapping. If custom or corrupted fonts were used during the PDF creation, the text will look correct on the screen but will copy as invalid characters.
Open the problematic PDF in your PDF viewer. Navigate to File > Properties and select the Fonts tab to review the embedded fonts.
Look for fonts that lack 'Embedded' or 'Embedded Subset' status, or custom fonts that might not be Unicode-compatible.
Open the original source file (e.g., a Word document). Highlight the text causing the issue and change the font to a standard Unicode-compatible font like Arial, Calibri, or Times New Roman.
Save the document and export it as a new PDF, ensuring that the 'Embed fonts' option is checked in your export settings.
Use OCR (Optical Character Recognition) to Extract Text
Use this method if you do not have access to the original source document to recreate the PDF. OCR ignores the corrupted underlying font encoding and reads the visual text instead.
Fix PDF Text Extraction Issues with WPS Office
WPS Office includes a robust PDF editor equipped with advanced OCR technology and font management, making it easy to bypass text copying errors and convert documents seamlessly without encoding issues.
- 1. Open the PDF: Launch WPS Office and open your problematic PDF file.
- 2. Access OCR: Go to the 'Tools' tab on the top ribbon and click on 'OCR'.
- 3. Extract Text: Select 'Extract Text', choose the document language, and click 'Extract' to scan the page visually.
- 4. Copy Results: Once processing is complete, simply copy the accurately recognized text and paste it anywhere without encountering squares or question marks.

Frequently Asked Questions
Why do squares or question marks appear when I copy text from a PDF?
This usually happens because the PDF has missing or incorrect font encoding, or the font mapping is damaged. The computer knows there is a character present but doesn't know which Unicode character it represents, so it displays a placeholder like a square.
Will pasting into a different program fix the corrupted text?
No, changing the destination application (e.g., pasting to Notepad instead of Word) usually does not fix the problem because the issue lies in the source PDF's internal font encoding, not the application you are pasting into.
How can I tell if a font is properly embedded in my PDF?
Open the PDF properties (usually under File > Properties) and navigate to the Fonts tab. Here you will see a list of all fonts used. If a font says 'Embedded' or 'Embedded Subset', it is included in the file. If encoding issues persist despite embedding, the font itself might lack proper Unicode mapping.


