

Fix OCR Text Disappearing After Saving a Searchable PDF

Question details
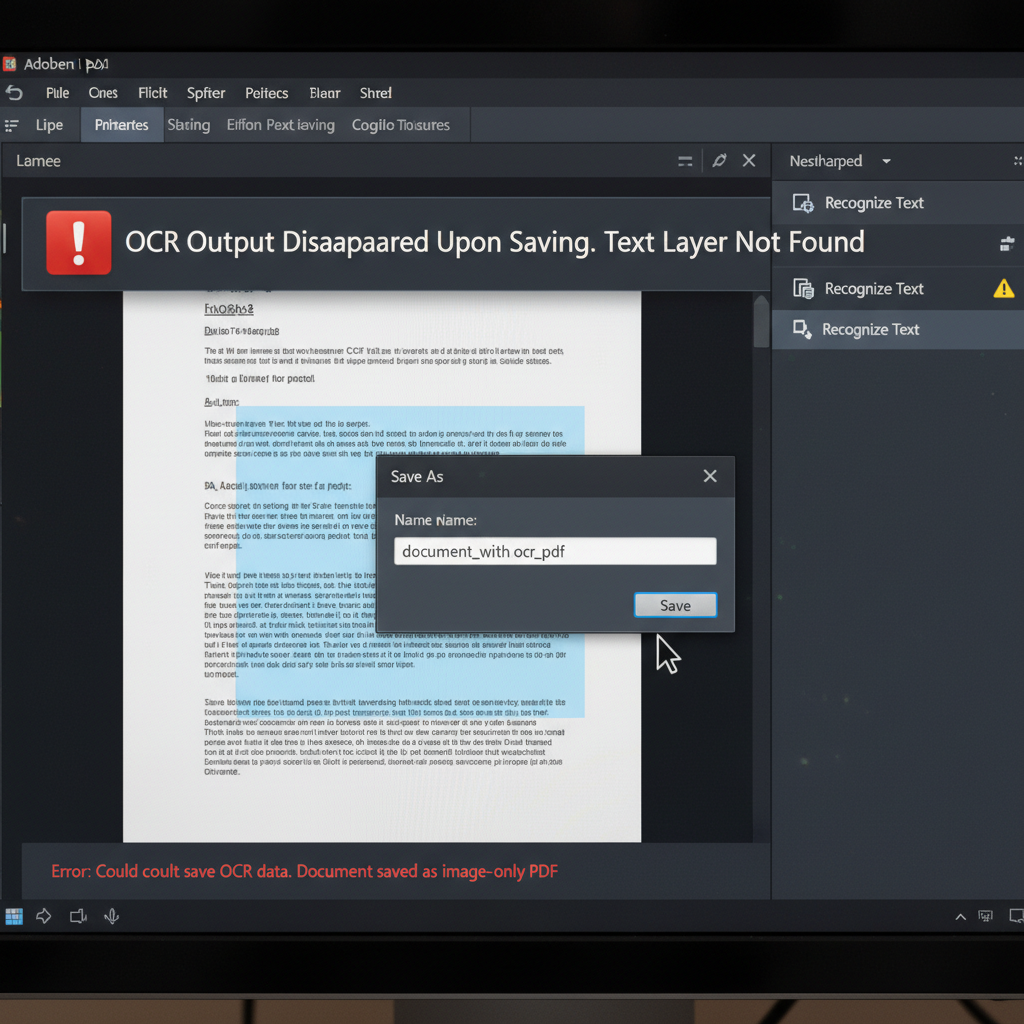
Users report that recognized text disappears after performing OCR and saving a searchable PDF document, leaving only an unsearchable image layer.
- Product
- PDF Document
- Device & OS
- not provided
- Scenario
- Attempting to save a PDF file after running the Optical Character Recognition (OCR) tool to make the text editable or searchable.
- Observed behavior
- The OCR output vanishes upon saving or reopening the file, making the text unsearchable or appearing as if the OCR process was never performed.
Ensure you are running the latest version of your PDF editor and verify that you have full write permissions for the destination folder to prevent permission-based file saving errors.
Select the Correct OCR Recognition Mode
Adjust the OCR settings to ensure the text is outputted as editable elements rather than invisible background text, which can mistakenly appear missing.
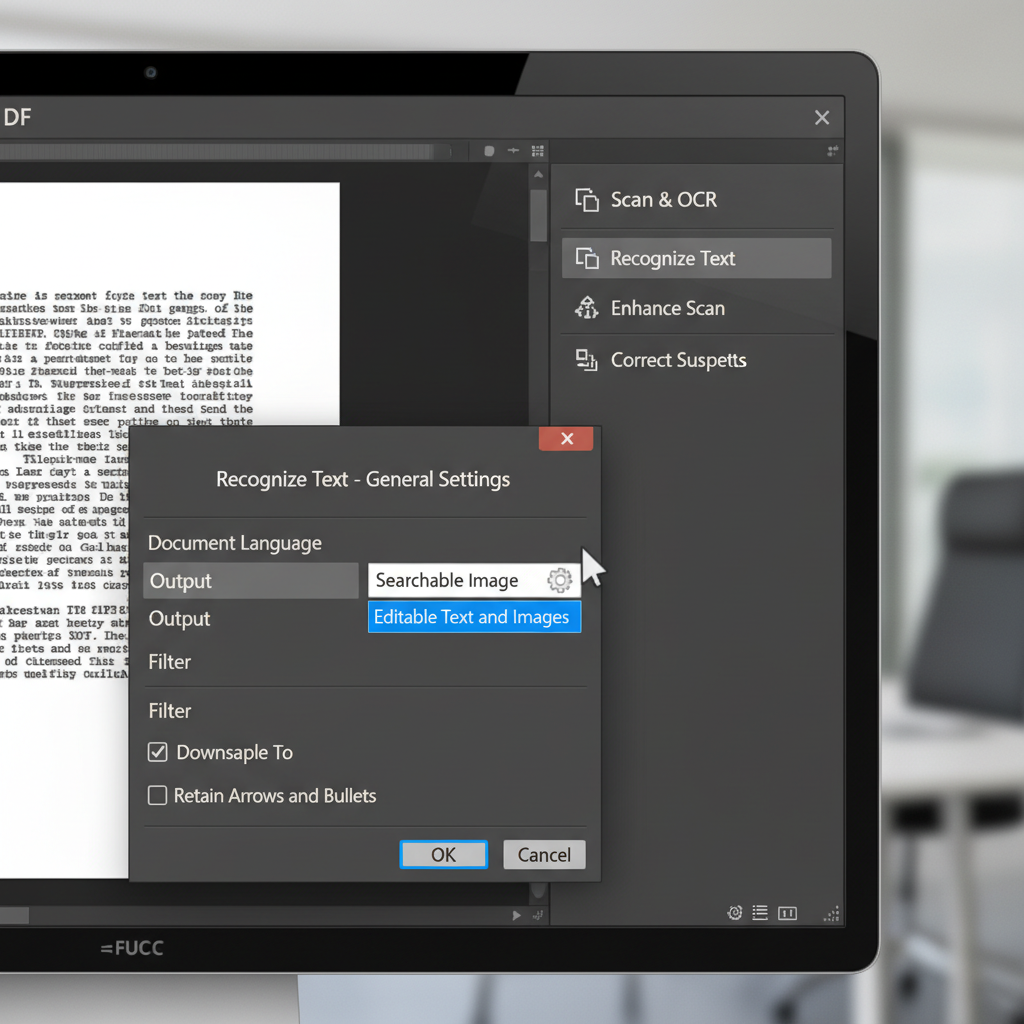
By default, the OCR engine may be set to 'Searchable Image', which places recognized text invisibly beneath the original image layer. If you need to see and modify the text directly, you must switch the setting to 'Editable Text and Images'.
Open your PDF in Acrobat and navigate to the 'Scan & OCR' tool from the right pane or the Tools menu.
Click on 'Recognize Text' and choose 'In this file'. Then, click the gear icon to open the Settings menu.
Under the Output dropdown, select 'Editable Text and Images' instead of 'Searchable Image'.
Click 'OK', run the OCR process, and then save the document to confirm the text remains visible and editable.
Save the Document Locally Before Transferring
Save the PDF to your local hard drive first to bypass server permission issues or cloud synchronization delays that cause the OCR layer to drop.
Update Preferences for Online Storage
Enable online storage preferences and ensure your PDF software is up to date to resolve known bugs related to Document Cloud saving.
Perform Reliable OCR and Edit PDFs with WPS Office
If you are experiencing persistent issues with OCR text disappearing, use WPS Office. Its advanced PDF editor provides a seamless and highly accurate OCR tool to extract text or create searchable PDFs without data loss.
- 1. Open PDF in WPS Office: Launch WPS Office and open your scanned PDF document in the PDF viewer.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Choose Extraction Mode: Select either 'Convert to Searchable PDF' to keep the original layout or 'Extract Text' to pull plain text, then configure your language settings.
- 4. Process and Verify: Click 'Start' to let the OCR engine process the document, then interact with the text to confirm it is fully recognized.
- 5. Save the Document: Go to 'File' and click 'Save' to securely store the new searchable PDF on your local computer.

Frequently Asked Questions
Why does my searchable PDF revert to a flat image after I save it?
This usually occurs if the file was saved to a network location where you lack full write permissions, causing the software to fail in saving the new OCR text layer. It can also happen if the OCR mode was set to 'Searchable Image', which visually looks exactly like the original flat image.
What is the difference between 'Searchable Image' and 'Editable Text and Images'?
The 'Searchable Image' setting maintains the exact look of your original scan while placing an invisible layer of searchable text behind it. 'Editable Text and Images' physically replaces the scanned text in the image with standard, editable digital fonts.
How can I check if the OCR process actually worked before saving?
After running OCR, use the text selection tool (cursor) and try to highlight paragraphs within the document, or press Ctrl+F (Windows) / Cmd+F (Mac) to search for a specific word. If it highlights correctly, the text has been recognized.


