

How to Automate Extracting Nonsequential PDF Pages into Separate Files
Question details
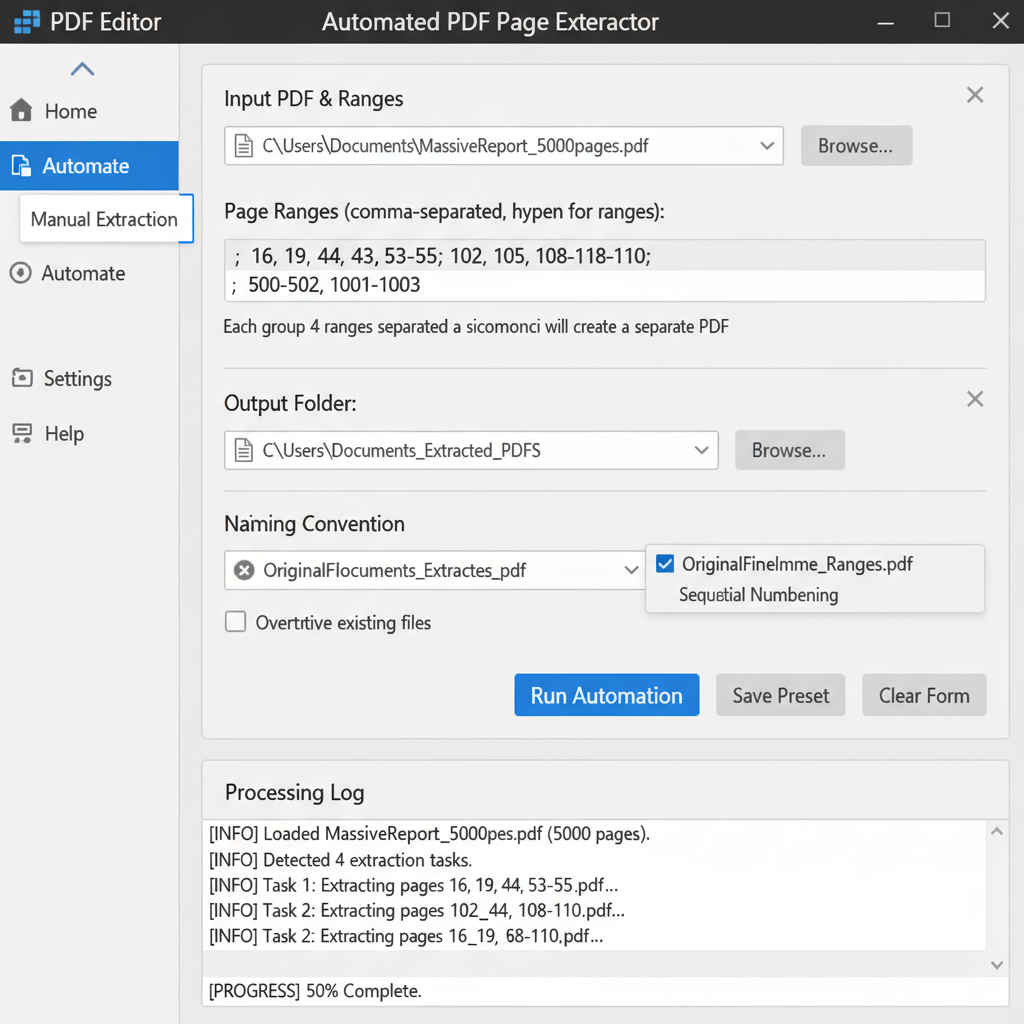
The user needs a method to frequently and automatically extract specific, nonsequential page ranges from a massive 5,000-page PDF and save each distinct list as a separate PDF document.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Processing a massive PDF file multiple times a week to isolate specific pages into new files without manually selecting them each time.
- Observed behavior
- Requires an automated solution that accepts input for nonsequential page ranges (e.g., 16, 19, 44, 53-55) and generates separate output files for each specified list.
Identify the exact page numbers or ranges you need to extract and ensure you have administrative access if you plan to install command-line utilities or execute custom JavaScript.
Use a Custom Acrobat JavaScript
Automate the extraction of complex page sequences directly within your PDF viewer using a custom JavaScript action.
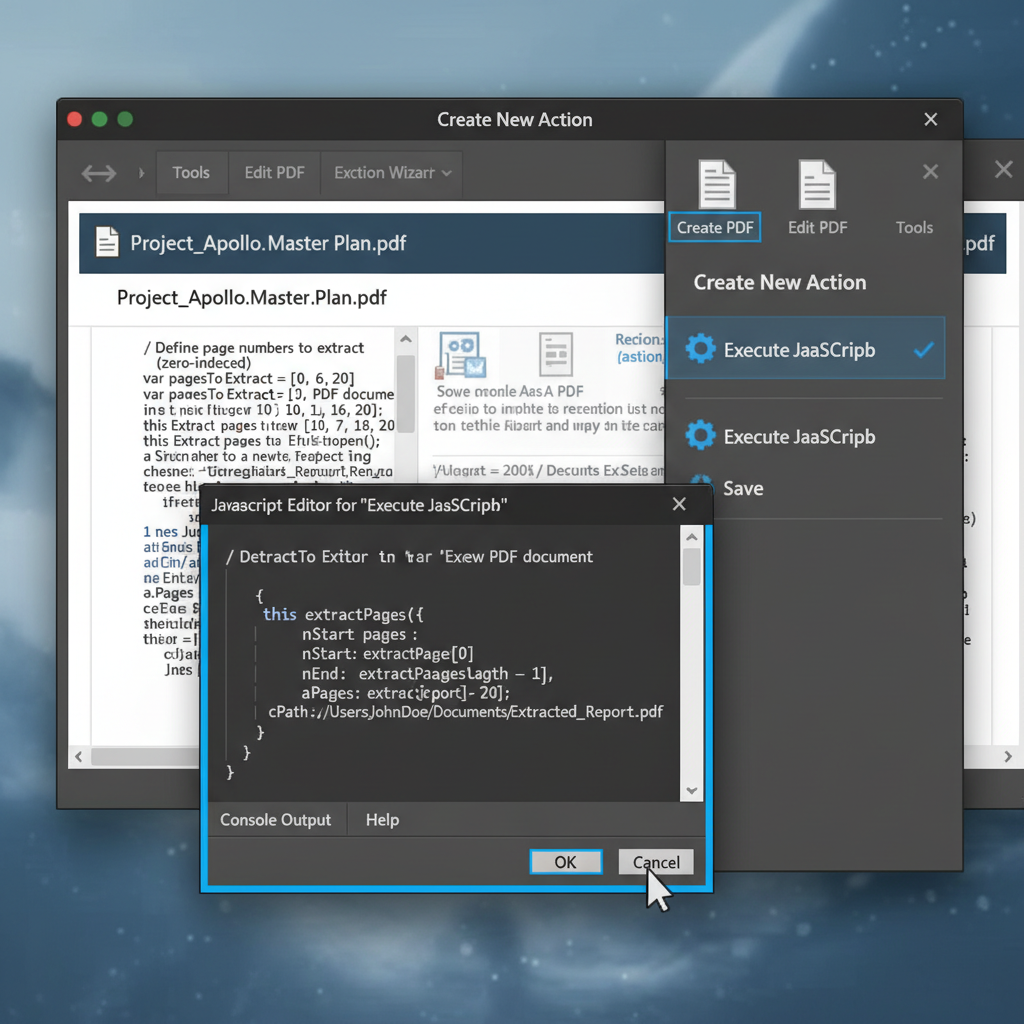
Advanced PDF editors like Adobe Acrobat support JavaScript API, allowing you to write scripts that interact with the document. By creating an automated Action that runs a script, you can define your page arrays and extract them rapidly.
Navigate to the Tools menu in your PDF editor and select the Action Wizard or Custom Actions feature.
Click 'New Action' and select 'Execute JavaScript' from the list of available tasks to add it to your action steps.
Click the options gear icon next to the JavaScript step and enter a script using the 'this.extractPages' method, specifying your target nonsequential pages.
Save the Action with a recognizable name. Whenever you open your large PDF, simply run this action to automatically generate your separated files.
Utilize Command-Line PDF Tools (e.g., PDFtk)
Process the extraction entirely in the background without manually opening the PDF viewer, ideal for scheduled or frequent automated tasks.
Easily Extract Specific PDF Pages with WPS Office
While scripting is great for backend automation, WPS Office provides an incredibly intuitive interface for extracting any combination of nonsequential pages in seconds. You can easily manage massive PDFs without writing a single line of code.
- 1. Open the PDF File: Launch WPS Office and open your massive PDF document within the WPS PDF tool.
- 2. Navigate to Page Extraction: Click on the 'Page' tab located on the top navigation toolbar, then select 'Extract Page'.
- 3. Input Custom Page Ranges: Choose the 'Custom' option and enter your nonsequential page numbers separated by commas (e.g., 16, 19, 44, 53-55).
- 4. Extract and Save: Click the 'Extract' button. WPS will immediately pull the specified pages and open them as a new, unsaved PDF file for you to save in your preferred location.
Frequently Asked Questions
What is the correct syntax for separating individual pages versus ranges?
Generally, you use commas to separate individual, nonsequential pages (e.g., 3, 7, 9) and a hyphen to denote a sequential range of pages (e.g., 12-15). Most PDF software and command-line tools recognize this standard format.
Can I automate PDF extraction without purchasing premium software?
Yes, you can use free, open-source command-line tools like PDFtk or Ghostscript. By writing simple batch scripts, you can automate the extraction process for massive PDFs completely free of charge.
Will extracting pages reduce the quality or resolution of the new PDF?
No. Extracting pages simply duplicates the exact data, text, and vector graphics from the original file into a new container. The visual quality and resolution remain identical to the source document.
Can I extract nonsequential pages using my web browser?
Yes, as a quick workaround for smaller files, you can open the PDF in Google Chrome, select 'Print', change the destination to 'Save as PDF', and select 'Custom' pages to input ranges like 1, 5, 8-10.


