

How to Automatically Rename Millions of PDF Files Using Their Contents
Question details
The user needs an industrial-scale workflow to read text from millions of PDF documents and automatically use the extracted text to rename the files.
- Product
- Device & OS
- not provided
- Scenario
- Batch processing a massive dataset of millions of PDF files to automate file renaming based on internal content, such as invoice numbers or client names.
- Observed behavior
- Standard software like Adobe Acrobat cannot handle this task because it lacks the industrial-scale automation required to extract text and rename millions of files without crashing or stalling.
Before deploying any automated workflow on your massive dataset, isolate a representative sample of 50 to 100 PDF files to test your text-extraction and renaming scripts for accuracy.
Implement an Enterprise Document Processing System
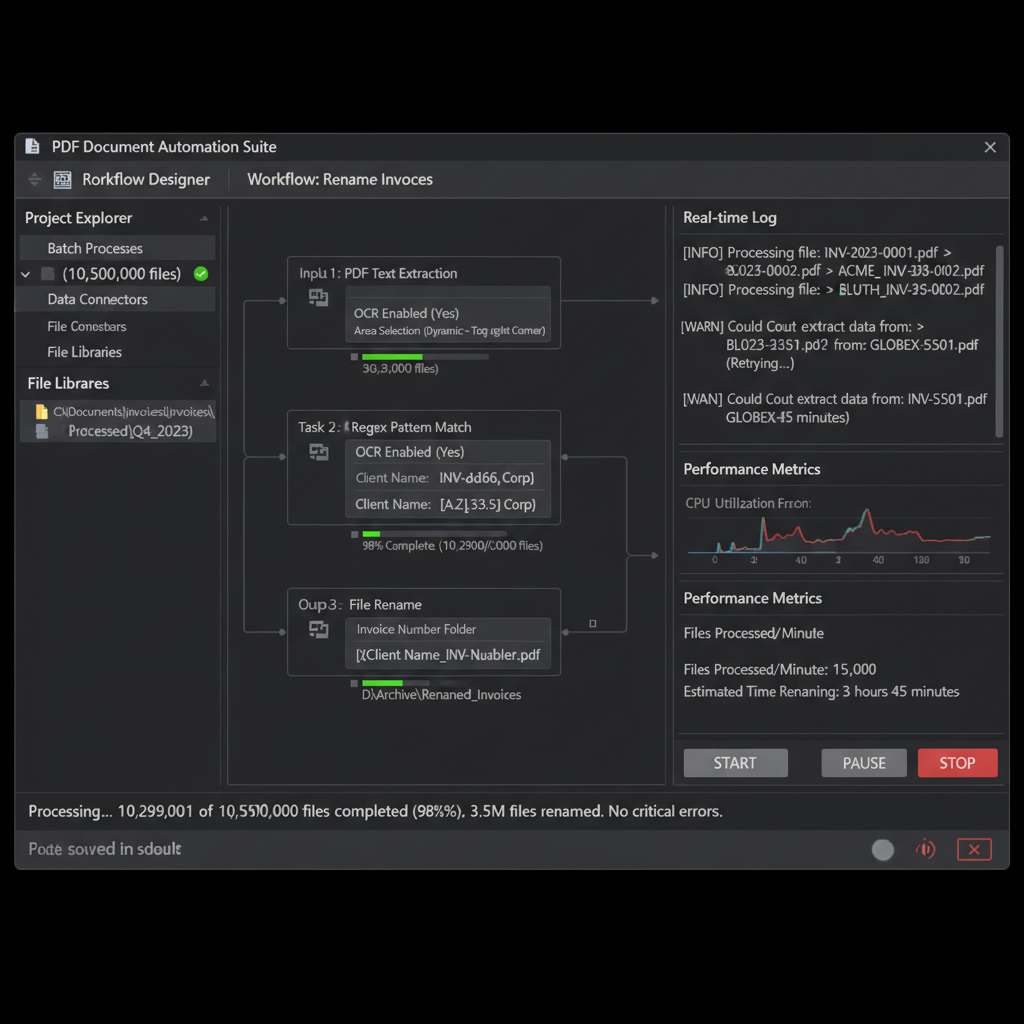
For an industrial dataset containing millions of files, you must use a dedicated data-extraction system with robust batch processing, OCR, and validation controls.
Standard desktop PDF editors are designed for manual or small-scale batch edits. Processing millions of files requires enterprise-grade software that can parse metadata, run Optical Character Recognition (OCR), and execute system-level file operations without failing.
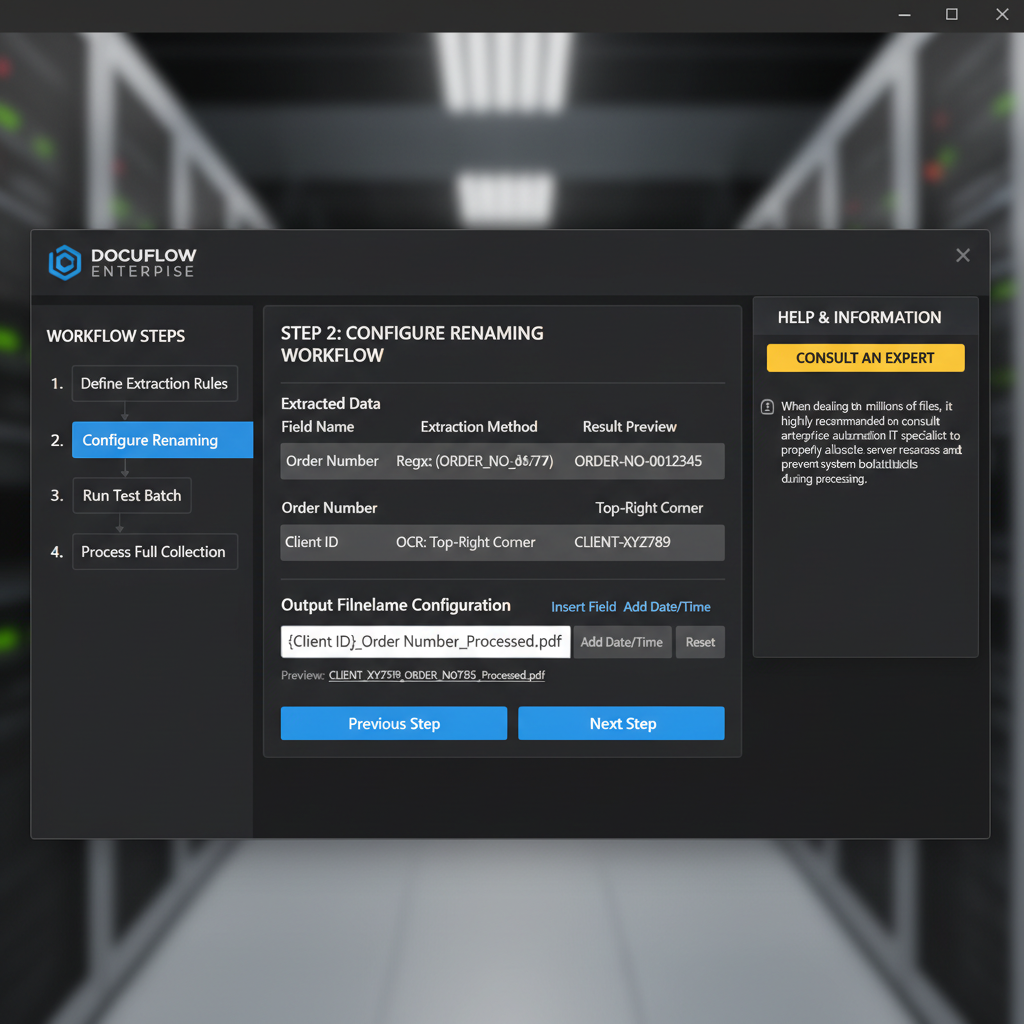
Configure your document processing software to identify the exact location or pattern of the text you want to extract, such as using regular expressions (Regex) to locate order numbers.
Set up the output module of your enterprise tool to map the extracted text string to the filename output variable.
Execute the workflow on a small, isolated folder of PDFs to ensure the system correctly extracts the text and applies the new filenames without altering the original documents.
Once validated, deploy the batch process across the full dataset while actively monitoring the software's error logs for any encrypted or unreadable files.
Automate Renaming Using Custom Python Scripting
If you have developer resources, writing a custom Python script provides a highly customizable and cost-effective way to parse PDF text and rename files at scale.
Manage and Edit PDF Files with WPS Office
While processing millions of files requires industrial data-extraction servers, WPS Office serves as an excellent, lightweight alternative to Adobe Acrobat for your everyday PDF editing, reading, and small-scale management needs.
- 1. Download the installer: Visit the official WPS Office website and click the free download button for your operating system.
- 2. Install the software: Run the downloaded installer and follow the on-screen prompts to set up the office suite.
- 3. Open your PDFs: Launch WPS Office and set it as your default PDF viewer to easily read and edit your documents.

Frequently Asked Questions
Why can't I use standard PDF editors to batch rename millions of files?
Standard PDF editors are optimized for manual editing and small-scale operations. When tasked with opening, reading, and renaming millions of files in succession, desktop applications will experience memory leaks, severe slowdowns, or outright crashes. This scale of operation requires dedicated enterprise IT solutions.
What is the best way to extract text from scanned PDFs for renaming?
If your PDFs consist of scanned images rather than digital text, you must incorporate an Optical Character Recognition (OCR) engine into your workflow. Tools like Tesseract OCR integrated with Python, or enterprise software like ABBYY, can convert the image pixels into machine-readable text before parsing it for filenames.
How do I prevent duplicate filenames when automating PDF renaming?
When configuring your renaming script or processing software, you should program a contingency rule. If the extracted text matches an existing filename in the destination folder, the script should automatically append a unique identifier, such as a sequential number or timestamp, to the end of the filename.
Can I use Windows File Explorer or Mac Finder to rename files based on their contents?
No. Native operating system file explorers only allow batch renaming based on sequential numbering, dates, or manually typed text strings. They do not have the capability to parse the internal textual contents of a PDF document to generate dynamic filenames.


