

How to Automatically Reorder PDF Pages by Class Code

Question details
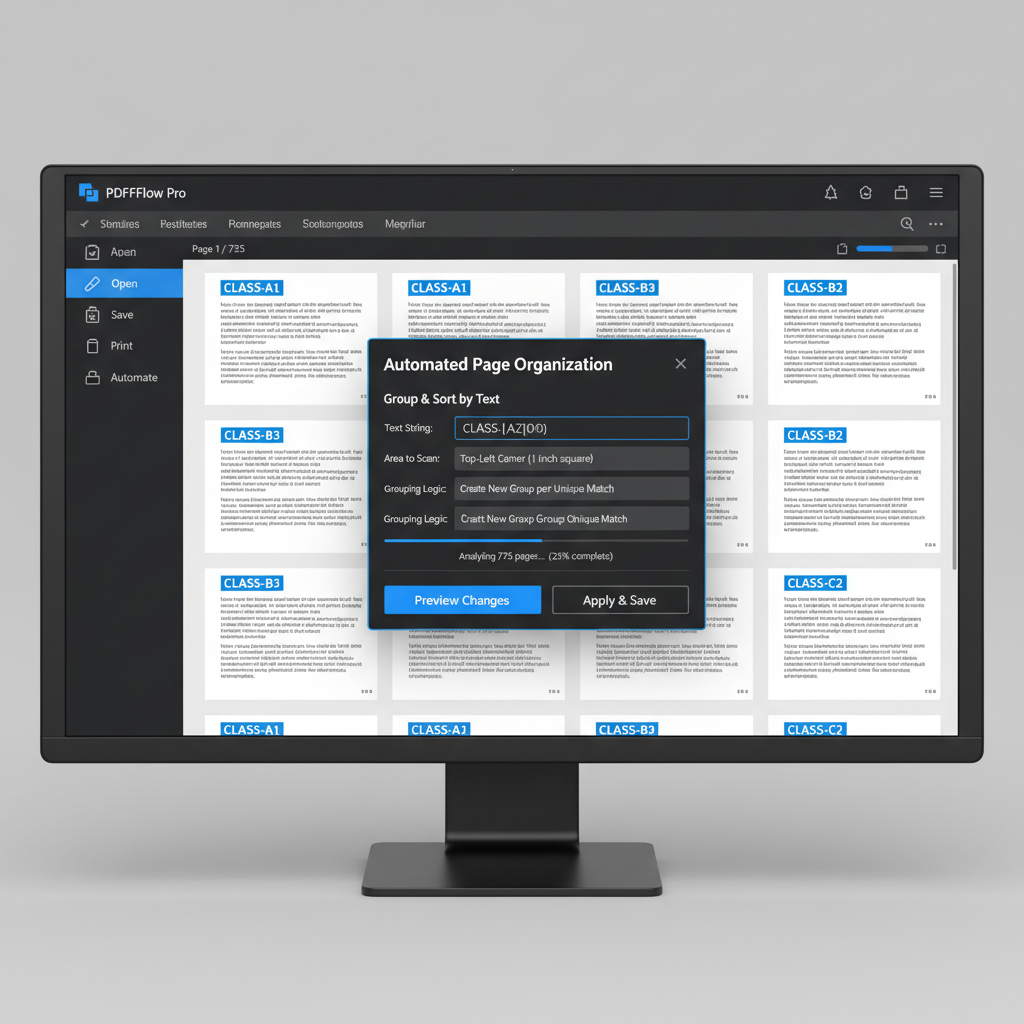
Automatically group and sort pages in a large PDF document based on a specific text string or class code located on each page.
- Product
- PDF Editors and Scripting Tools
- Device & OS
- not provided
- Scenario
- Organizing and printing a massive PDF document (e.g., 700 pages) where pages must be grouped by identifiers found in the top-left corner.
- Observed behavior
- Manually rearranging hundreds of pages is highly impractical, necessitating an automated solution to extract text and reorder the pages.
Verify that your PDF contains selectable text rather than flattened images. If the class codes are scanned, you will need to run an Optical Character Recognition (OCR) process before attempting to extract the text.
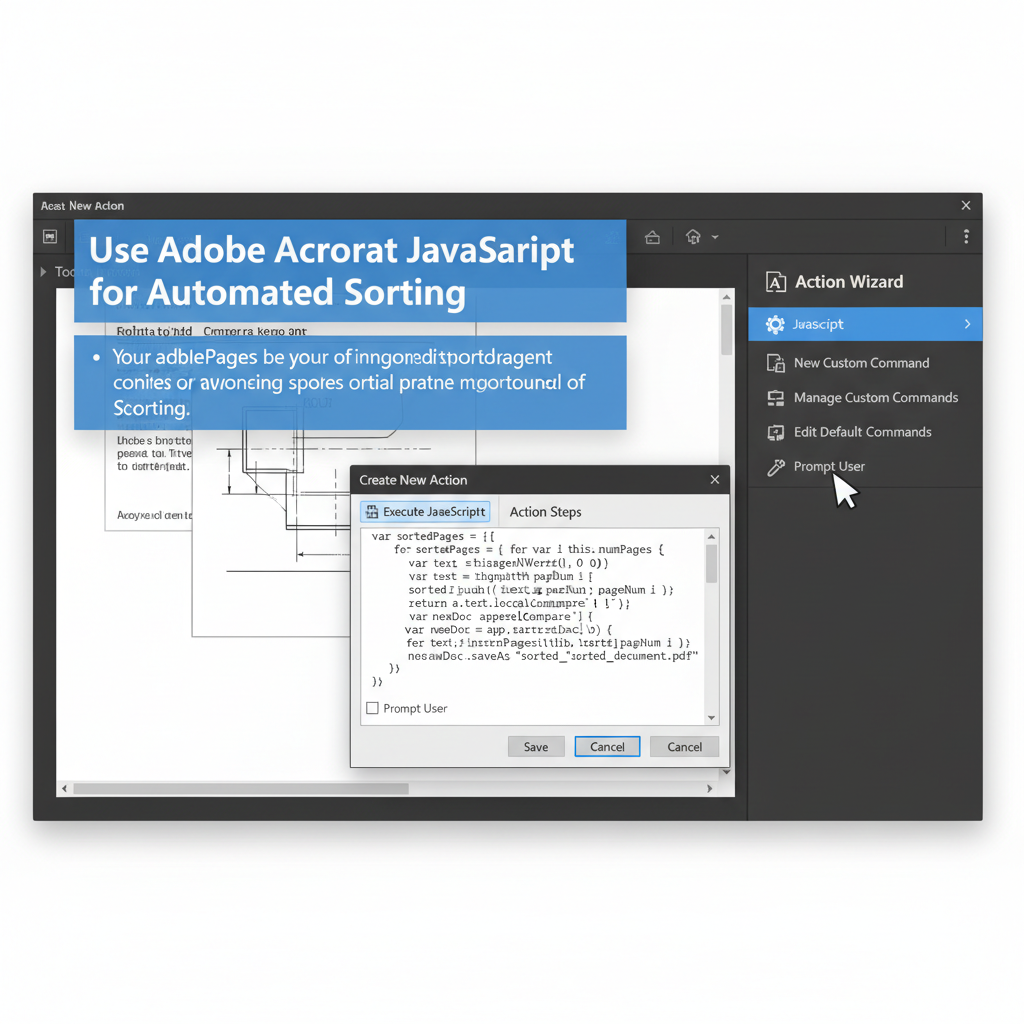
Use Adobe Acrobat JavaScript for Automated Sorting
Implement a custom JavaScript action within a professional PDF editor to read text from specific page coordinates and generate a newly sorted file.
Standard PDF editors do not have a built-in button to sort pages by localized text content. A custom script is the most reliable way to achieve this. The script will iterate through the document, extract text from a defined boundary box (your top-left corner), map it to the page number, and reorder the file.
Open your PDF in Adobe Acrobat Pro. Go to 'Tools', select 'Action Wizard', and choose 'New Custom Command'.
Add a JavaScript routine. You will need to use the 'getPageNthWordQuads' or 'getPageNumWords' methods to define the top-left coordinate box and extract the class code string for each page.
Within your script, push the extracted class codes and their corresponding page numbers into an array, then apply a standard JavaScript sort function to group them.
Use the 'extractPages' or 'insertPages' methods in your script to create a new PDF document that appends the pages in the newly sorted array order.
Automate PDF Reordering with Python
Use external Python libraries to extract text, sort the mapping, and reconstruct the PDF document automatically.
Easily Manage, OCR, and Organize PDF Pages with WPS Office
While automated text-based sorting requires custom scripting, WPS Office provides a highly intuitive and powerful suite of PDF tools. With built-in OCR and visual page management, you can easily make scanned class codes recognizable and reorganize large documents securely.
- 1. Open Your PDF: Launch WPS Office and open your large PDF document.
- 2. Run OCR if Necessary: Navigate to the 'Tools' tab and select 'OCR'. Choose 'Extract Text' to ensure your class codes are readable by your operating system or scripts.
- 3. Access Page Management: Click on the 'Page' tab. Here you will see a thumbnail grid of all your pages.
- 4. Split or Extract Pages: Use the 'Split PDF' or 'Extract Pages' functions to break down your massive 700-page document into manageable chunks based on visual class code groups.

Frequently Asked Questions
Why isn't my PDF script extracting the class codes properly?
This usually happens if the PDF pages are flattened images or scanned. The script is looking for text layers, but only sees an image. You must run an Optical Character Recognition (OCR) process first to convert the image pixels into machine-readable text.
Can I reorder PDF pages automatically without writing any code?
Most standard desktop PDF editors do not have a 'sort by text content' button out of the box. You typically need a custom script (like Acrobat JavaScript or Python) or a specialized, enterprise-grade document processing tool designed for bulk invoice/record sorting.
How do I safely test my PDF sorting script?
Extract a small sample of your document (e.g., the first 10-15 pages) and run your script on this smaller file. This ensures your text-extraction coordinates are accurate and your sorting logic groups the pages correctly before you commit to processing the entire 700-page file.


