

How to Batch OCR Thousands of PDFs from the Windows Command Line

Question details
The user needs to perform batch Optical Character Recognition (OCR) on thousands of PDF files using the Windows command line, with features like output file renaming and error handling.
- Product
- Adobe Acrobat DC
- Device & OS
- Windows
- Scenario
- Automating the conversion of thousands of scanned PDF documents into text-searchable files via a command-line script.
- Observed behavior
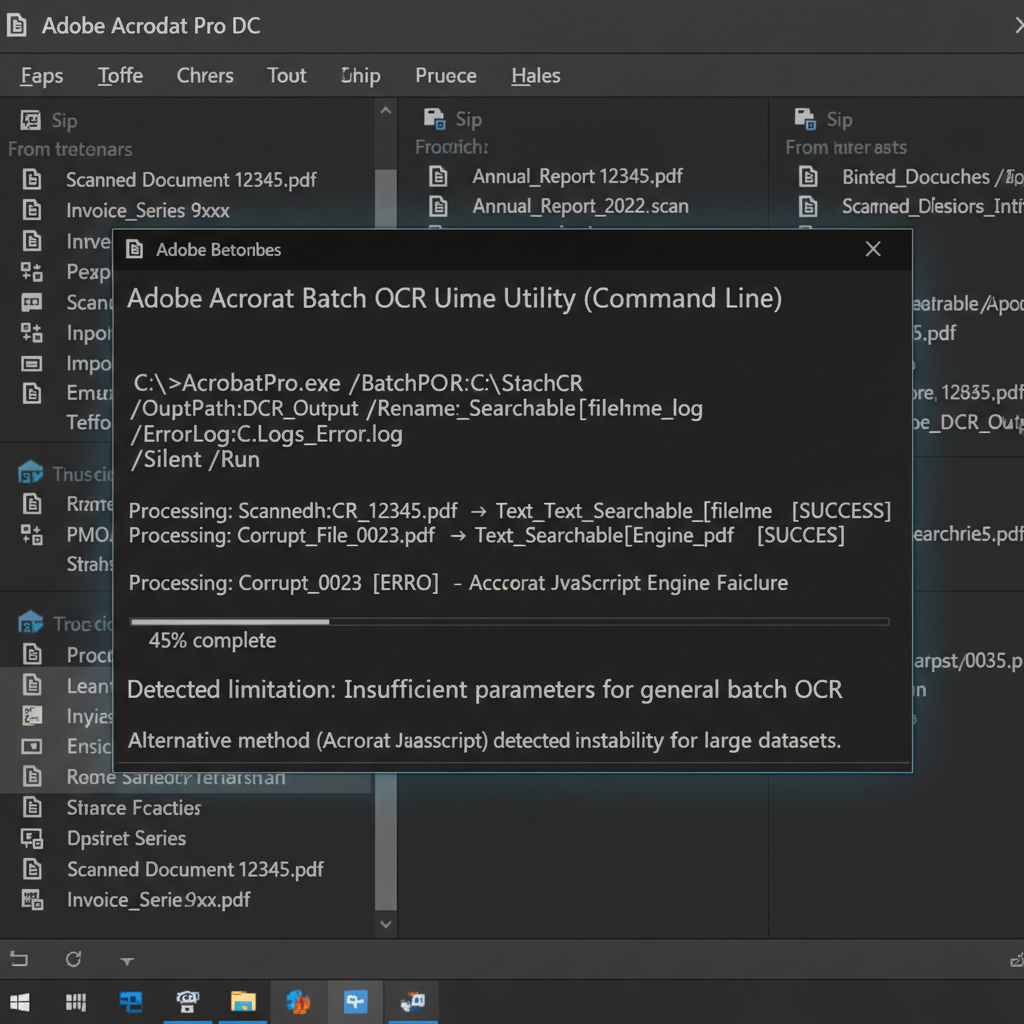
- Acrobat DC lacks the necessary parameters to function as a general command-line OCR tool, and Acrobat JavaScript is unstable for massive batch processing tasks.
Before running any automated batch processing scripts, ensure that all your original source PDFs are safely backed up in a separate directory to prevent accidental data overwriting.
Use a Dedicated Command-Line OCR Tool (e.g., Tesseract)
Since Adobe Acrobat cannot handle large-scale command-line OCR, using a dedicated open-source engine like Tesseract OCR paired with a scripting language is the most robust approach.
Adobe Acrobat DC is designed primarily as a desktop GUI application. It cannot be invoked via the command line to reliably process recursive folders, handle automated output naming, execute in the background, or gracefully continue after encountering a corrupted file. For thousands of files, you need a scriptable OCR engine.
Tesseract OCR is a highly accurate, open-source command-line tool that can be easily integrated into a Windows Batch or PowerShell script to loop through directories, apply OCR, and save the output systematically.
Download and install a command-line capable OCR engine such as Tesseract OCR or Ghostscript on your Windows machine.
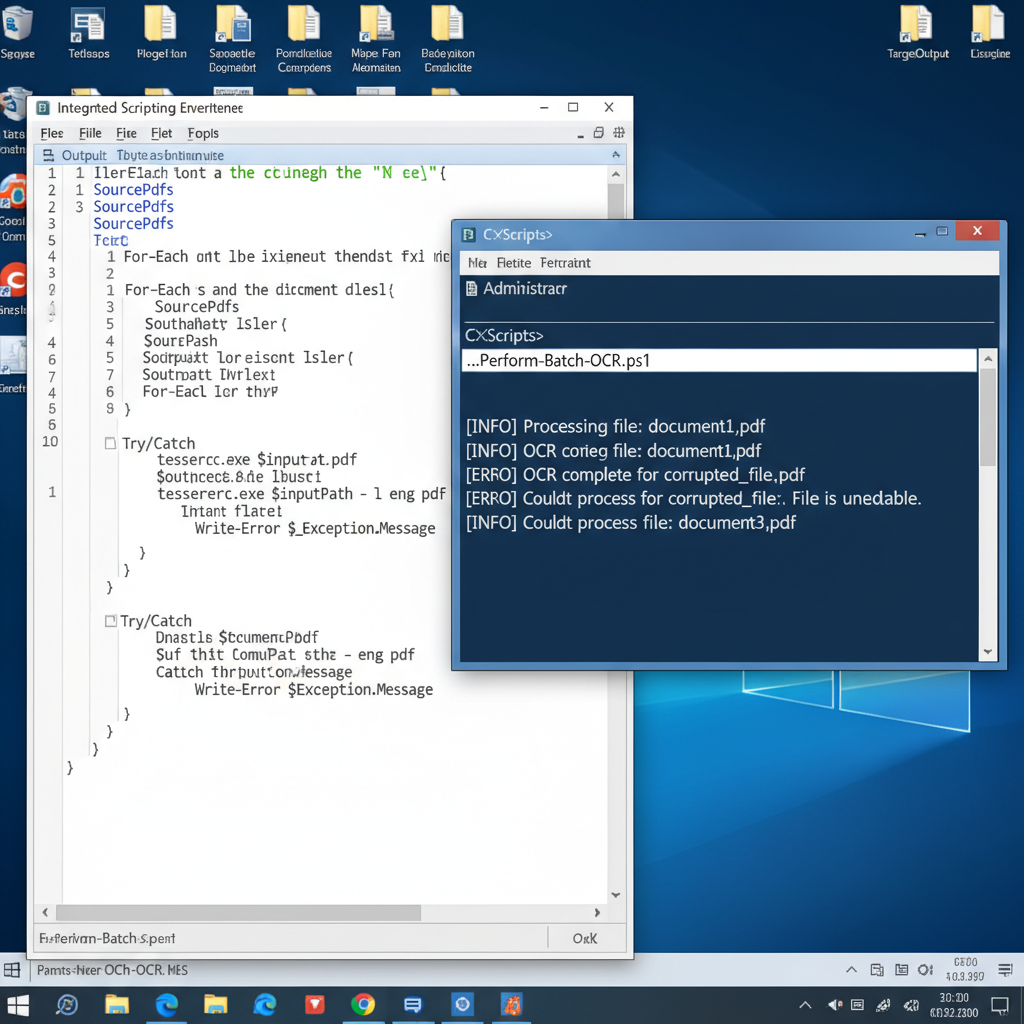
Open a text editor and write a PowerShell or Batch script that uses a 'For' loop to iterate through your target directory containing the source PDF files.
Within your script loop, define variables for the new output filenames and include 'Try/Catch' blocks (in PowerShell) to ensure the script logs any errors and continues processing the next file.
Open Command Prompt or PowerShell with administrator privileges, navigate to your script's location, and execute it to begin the background batch OCR process.
Implement an Enterprise PDF SDK
For businesses requiring commercial support, high-speed processing, and exact formatting retention, using an enterprise-grade PDF Command Line Interface (CLI) or SDK is recommended.
Batch OCR PDFs Easily with WPS Office
Skip the complex command-line scripts and potential coding errors. WPS Office provides a highly accurate, user-friendly graphical interface for batch OCRing your PDF files, saving you time and technical hassle while delivering professional results.
- 1. Open WPS Office: Launch the WPS Office application and navigate to the 'PDF' tab on the main interface.
- 2. Access the OCR feature: Click on the 'OCR' tool located in the top toolbar to open the text recognition module.
- 3. Add multiple files: Select the 'Add Files' option to import the batch of PDF documents you wish to process from your computer.
- 4. Start the Batch OCR process: Choose your desired output format and language, then click 'Extract Text' to begin processing all selected documents simultaneously.

Frequently Asked Questions
Why can't I use Adobe Acrobat DC for command-line batch OCR?
Adobe Acrobat DC does not natively support extensive command-line execution for OCR tasks. It lacks the necessary command-line arguments for recursive folder processing, continuous error handling, and silent background execution required for thousands of files.
Can I use Acrobat JavaScript to automate batch PDF processing?
While Acrobat JavaScript can automate minor tasks within the application, it is not designed or suitable for large-scale batch processing. It suffers from memory limitations and lacks robust error-recovery mechanisms when processing thousands of documents.
What is the best free tool for command-line PDF OCR?
Tesseract OCR is widely considered the best free, open-source engine. When combined with Python libraries like OCRmyPDF, it provides a powerful command-line solution capable of adding searchable text layers to thousands of scanned PDFs.


