

How to Convert a PDF to Apache OpenOffice Format with Images

Question details
The user needs to convert a PDF document into an Apache OpenOffice format but is experiencing missing or dropped embedded images during the conversion process.
- Product
- PDF / Apache OpenOffice
- Device & OS
- not provided
- Scenario
- Converting standard or scanned PDFs into OpenOffice readable formats (like ODT or DOC) while keeping complex layouts and embedded images intact.
- Observed behavior
- Standard document conversion tools frequently omit embedded images or fail to process complex layouts, leaving only plain text in the resulting OpenOffice document.
Verify whether your original PDF is text-based or a flattened scanned image. If it is a scanned document, you will absolutely need a conversion tool that features Optical Character Recognition (OCR) to successfully extract both the text and the embedded images.
Use an OCR-Enabled PDF to ODT Converter
The most effective method for ensuring images are retained is using a dedicated PDF conversion tool that supports OCR and outputs to OpenDocument Text (.odt).
Many free online converters simply extract the text layer of a PDF and ignore the image streams. Using an advanced converter like Adobe Acrobat or a premium online OCR tool guarantees that visual elements are mapped correctly into the new document structure.
Launch Adobe Acrobat or navigate to a reputable online PDF-to-ODT conversion service that clearly advertises OCR capabilities.
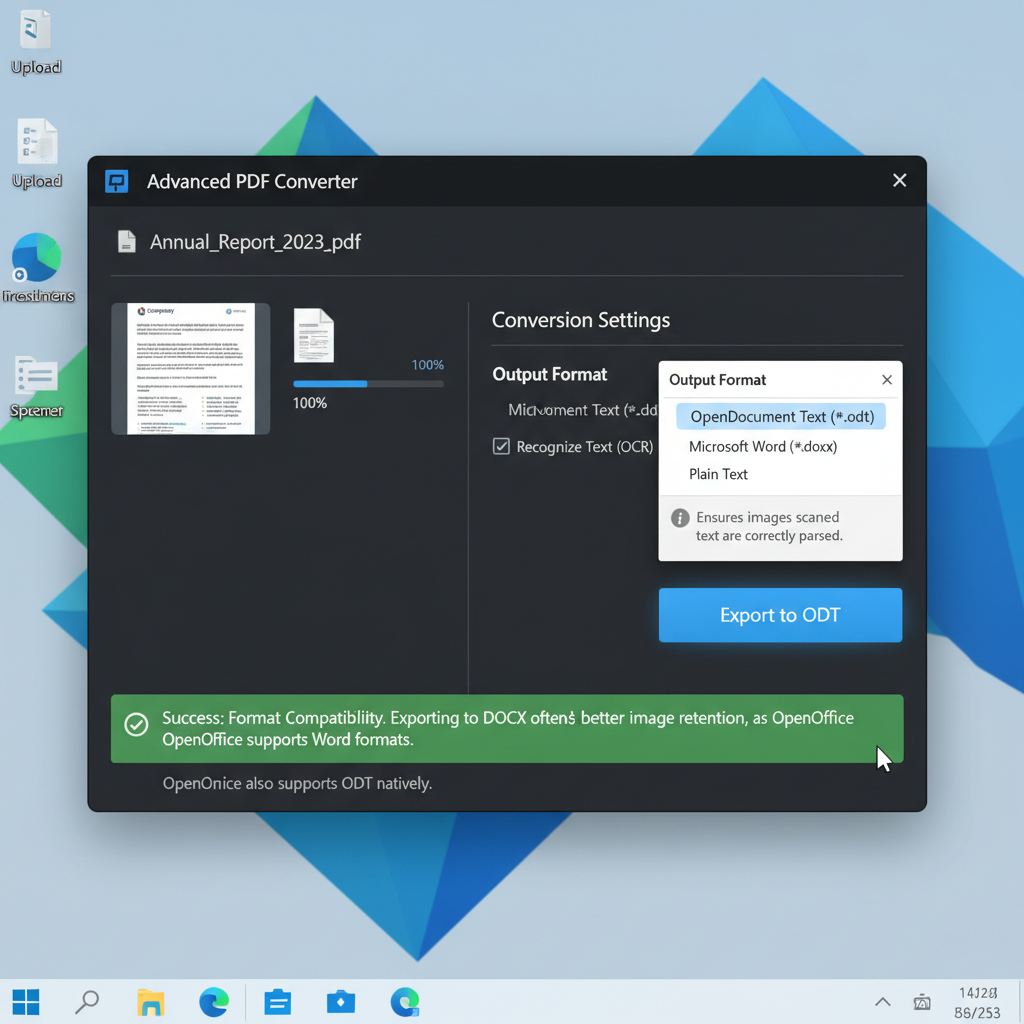
Import your PDF file into the software and select 'OpenDocument Text (*.odt)' or 'Microsoft Word (*.docx)' as your target format, as OpenOffice can read both.
Check the software settings to ensure 'Recognize Text' or 'OCR' is enabled so that images are parsed correctly, then click 'Export' or 'Convert'.
Open the newly downloaded file in Apache OpenOffice Writer to confirm that all images and complex layouts have been successfully retained.
Extract and Insert Missing Images Manually
If only a few images are missing after a basic text conversion, manually extracting them from the PDF and pasting them into OpenOffice is a reliable workaround.
Use WPS Office to Convert PDFs with Perfect Image Retention
WPS Office features a powerful, built-in PDF toolkit that perfectly converts complex PDF files into editable formats. Its advanced engine ensures that all embedded images, graphics, and layouts are flawlessly preserved, making it an ideal bridge for working with OpenOffice.
- 1. Open the PDF in WPS Office: Launch WPS Office and open your target PDF document directly within the application.
- 2. Select PDF to Word: Navigate to the 'Tools' tab on the top ribbon and click the 'PDF to Word' button.
- 3. Adjust Conversion Settings: In the dialog box, ensure that the layout retention settings are prioritized so images are mapped correctly, and choose your save location.
- 4. Export and Use: Click 'Start' to convert the file to a DOCX format, which you can then edit freely in WPS Office or natively open in Apache OpenOffice without losing any visual elements.
Frequently Asked Questions
Why do images disappear when I convert a PDF to OpenOffice?
Many basic PDF converters only extract text layers (the actual text data) and ignore the embedded image streams to save processing time. To retain images, you need a converter that actively parses complex layouts and visual elements, or uses OCR.
Can Apache OpenOffice open PDF files directly?
OpenOffice cannot open PDFs natively for text editing in Writer. You can install an extension called 'PDF Import', but this generally opens the PDF in OpenOffice Draw, treating each line of text and image as individual, hard-to-edit graphic objects.
What is OCR and why do I need it for PDF conversion?
OCR stands for Optical Character Recognition. It is a technology that scans images to identify the text within them. If your PDF is a scanned document rather than a digitally created one, OCR is absolutely required to separate the text from the background image so both can be imported properly.
Is there a way to extract only the images from a PDF file?
Yes. Advanced PDF software, including Adobe Acrobat and WPS Office, have export functions specifically designed to extract all images from a PDF and save them into a dedicated folder as JPG or PNG files.


