

How to Extract Matching Bookmarked Pages from Multiple PDFs

Question details
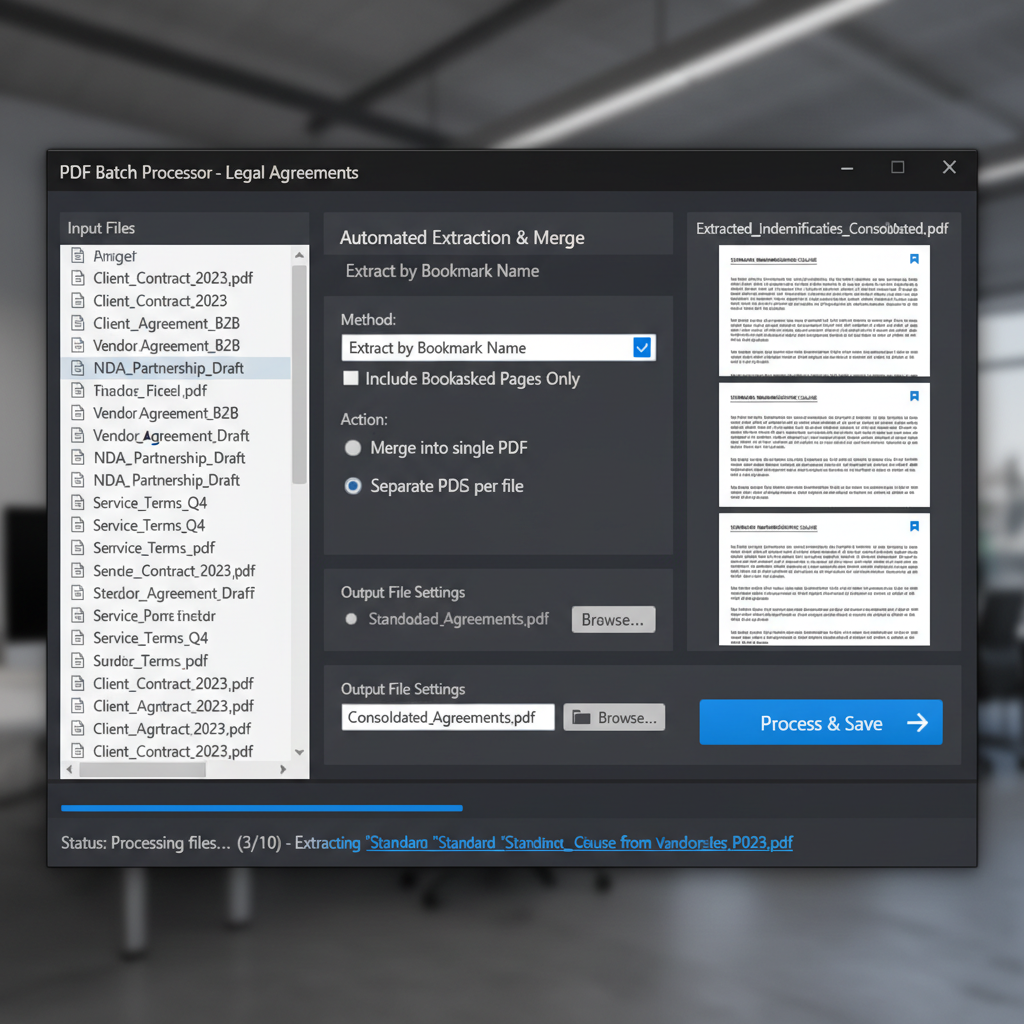
The user needs a method to identify and extract pages that share a specific bookmark name from multiple PDF documents, and then merge all those extracted pages into one new PDF file.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Collecting identical sections, such as specific legal agreements or standard forms, from a large batch of customer PDFs without manually opening and splitting each file.
- Observed behavior
- The goal is to automate the extraction of bookmarked page ranges across multiple files and append them to a single destination document.
Gather all the customer PDFs into a single dedicated folder on your computer and verify that they all use the exact same bookmark title for the section you intend to extract.
Use an Acrobat Action Wizard with Custom JavaScript
Automate the batch extraction process by combining the Action Wizard tool with a custom JavaScript snippet to locate bookmarks and extract their corresponding pages.
This automated method requires a professional PDF editor that supports batch actions and scripting. You will need to prepare a custom JavaScript code that loops through the document's bookmark tree, finds the specific target bookmark, identifies its exact page range, and executes an extraction command to append those pages to your destination PDF.
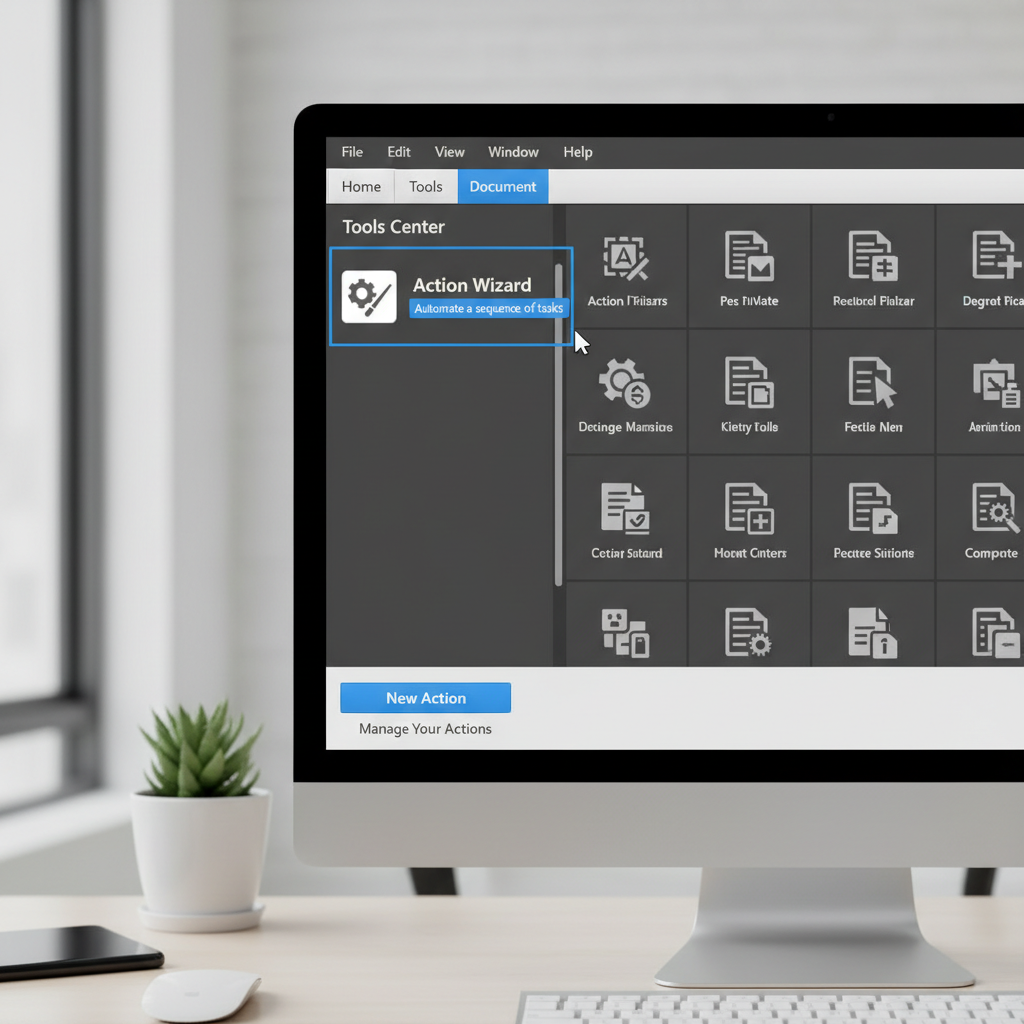
Launch your advanced PDF editor, navigate to the Tools menu, select 'Action Wizard', and click on 'New Action'.
In the 'Files to be Processed' section, click on 'Add Folder' and select the directory where you placed all the customer PDF files.
Under the tools panel, locate the 'More Tools' or 'Processing' section, select 'Execute JavaScript', and click the plus (+) icon to add it to your action steps list.
Uncheck the 'Prompt user' box, click 'Specify Settings', and paste your custom JavaScript designed to scan for the specific bookmark name and extract the underlying pages.
Add a 'Save' step to define where the output files should go. Save the Action, give it a descriptive name, and run it on a small batch of 2-3 files first to ensure the script functions properly before processing your entire folder.
Easily Extract and Merge PDF Pages with WPS Office
If you do not have scripting experience, WPS PDF offers a highly intuitive graphical interface that lets you quickly extract specific pages from documents and merge them together in just a few clicks.
- 1. Open Your PDF: Launch WPS Office, go to the PDF tab, and open your source customer document.
- 2. Extract Target Pages: Navigate to the 'Page' tab on the top ribbon and click 'Extract Page'. Select the specific page numbers that correspond to your desired bookmarked section.
- 3. Save as a New File: Choose the option to extract the selected pages as a separate PDF file and save it into a designated folder.
- 4. Merge the Extracted PDFs: Once all pages are extracted, click on 'Merge PDF' under the 'Tools' tab. Add all your newly created files into the dialog box and click 'Merge' to combine them into one single master document.

Frequently Asked Questions
Can I extract pages by bookmark natively without using a script?
Most standard PDF editors do not have a built-in one-click button to batch extract pages by bookmark name across multiple files. You typically have to specify page ranges manually or use advanced scripting like JavaScript to automate the bookmark text recognition.
How do I determine the exact page range of a bookmark?
You can find the start page by clicking on the bookmark in your PDF reader's navigation pane. The section generally ends exactly one page before the starting page of the next top-level bookmark in the list.
Why did my automated extraction script fail?
Script failures usually occur if the target bookmark name is misspelled in the code (it is case-sensitive), if a PDF is missing that specific bookmark, or if the PDF's security settings restrict page extraction and document assembly.


