

How to Extract PDF Pages Containing Specific Text in Acrobat DC

Question details
The user needs to extract specific pages from a long PDF document based on whether those pages contain a certain word or phrase.
- Product
- Adobe Acrobat DC
- Device & OS
- not provided
- Scenario
- Filtering and isolating pages in a large PDF file based on the presence of targeted keywords or phrases.
- Observed behavior
- Pages containing the specified text string need to be successfully identified and extracted into a separate document using automated scripts.
Before starting, verify that your PDF contains searchable text by pressing Ctrl+F (or Cmd+F) and searching for your target phrase. If the text cannot be found, the PDF might be a scanned image and will require Optical Character Recognition (OCR) first.
Use Action Wizard and JavaScript in Acrobat DC
Use a custom Action Wizard sequence to automatically search for and extract pages containing a specific string of text.
Adobe Acrobat DC allows you to automate repetitive tasks using the Action Wizard. By importing a specific JavaScript-based sequence (like ExtractPagesWithString.sequ), you can search through long documents and pull out only the pages you need.
Locate and download the 'ExtractPagesWithString.sequ' action file from a trusted Adobe script provider.
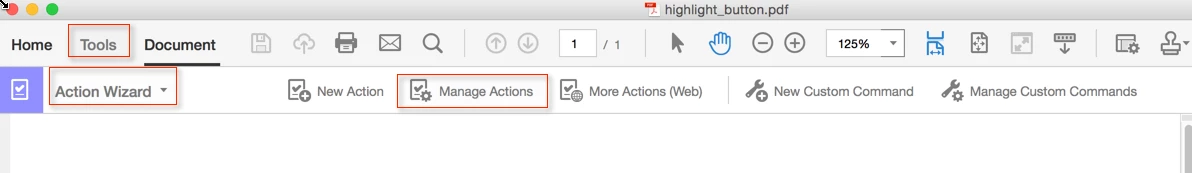
Launch Adobe Acrobat DC, navigate to the 'Tools' tab, and select 'Action Wizard'.
Click 'Manage Actions' and select 'Import'. Browse for the downloaded .sequ file and add it to your Action Wizard list.
Edit the imported action to ensure the JavaScript prompt is enabled. This prompt is what allows you to type in the custom text string you want to search for.
Click the newly imported action to run it. When prompted, enter your target word or phrase. Acrobat will process the document and extract the matching pages.
Easily Search and Extract PDF Pages with WPS Office
WPS Office provides a highly intuitive interface to search for specific text and easily extract individual or ranges of pages without needing to install complex JavaScript files.
- 1. Open the PDF: Launch WPS Office and open your target PDF document.
- 2. Search for Text: Press Ctrl+F to open the search bar. Type your target word or phrase and note down the page numbers where the text appears.
- 3. Access Page Tools: Navigate to the 'Page' tab located on the top navigation ribbon.
- 4. Select Extract Page: Click the 'Extract Page' button. In the dialog box, select 'Custom' and enter the specific page numbers you noted earlier.
- 5. Complete Extraction: Choose whether to extract them as a single combined PDF or multiple individual PDFs, then click 'Extract'.

Frequently Asked Questions
Why can't Acrobat find the specific text in my PDF?
If the standard search function (Ctrl+F) fails to locate your text, your PDF is likely a scanned image rather than a text-based document. You must perform Optical Character Recognition (OCR) first to convert the image text into searchable data.
Is it possible to delete pages containing a specific word instead of extracting them?
Yes, similar custom JavaScript actions can be written or downloaded to delete pages based on text content. Alternatively, you can use the search function to locate the pages and manually delete them using the Organize Pages tool.
Can I extract pages from a secured or locked PDF?
You cannot extract pages from a PDF if it has password restrictions preventing document assembly or extraction. You must first unlock the PDF with the appropriate permissions password before running any extraction scripts.
Does the extraction script work on macOS as well as Windows?
Yes, Acrobat DC's Action Wizard and JavaScript functionalities are supported on both Windows and macOS, provided the PDF contains searchable text.


