

How to Extract PDF Pages That Contain Specific Search Results

Question details
The user wants to find specific terms within a large PDF file and automatically extract only the pages containing those search results into a new, smaller document.
- Product
- PDF Editors
- Device & OS
- not provided
- Scenario
- When reviewing lengthy documents like manuals, legal contracts, or transcripts, users often need to isolate specific information by searching for a keyword and saving only the relevant pages to a new file.
- Observed behavior
- Most mainstream PDF software lacks a built-in, one-click command to automatically extract pages based on search terms. Users must utilize alternative workarounds such as exporting advanced search results to CSV, using third-party scripts, or utilizing redaction marks to filter pages.
Ensure your PDF document is fully searchable and not a scanned image file. If you cannot highlight the text natively, you will need to run OCR (Optical Character Recognition) before attempting to search and extract.
Use Redaction Marks and Comment Extraction (Workaround)
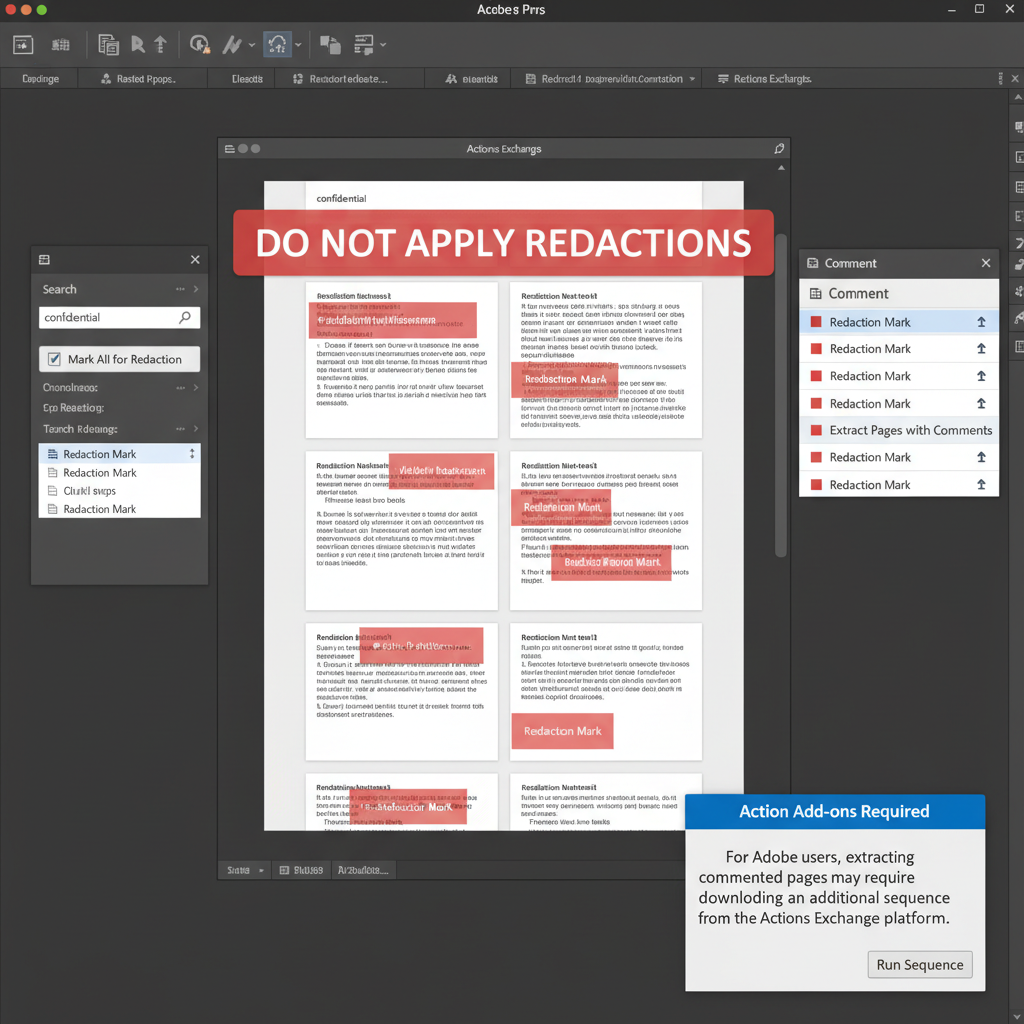
This method uses the Search and Redact feature available in advanced PDF editors to mark targeted words, treating the marks as comments that can then be extracted.
Since standard PDF editors do not have an 'extract by search' button, you can leverage the redaction tool as a marker. By searching for your keyword and applying redaction marks (without actually applying the final redaction), the software registers these marks as annotations.
You can then use built-in or custom Action scripts to extract pages that contain annotations or comments.
Open your PDF editor and navigate to the Redact or Search tool. Search for your desired keyword and choose the option to mark all search results for redaction.
Leave the redaction marks as they are. Do not execute the 'Apply Redactions' command, as this will permanently black out the text.
Use your PDF software's Comment summary or Actions Exchange feature to isolate and extract pages containing comments. Since the software treats redaction marks as comments, it will successfully extract only the pages with your search terms.
Export Advanced Search to CSV and Use Scripts
For users comfortable with scripting or third-party paid plugins, you can export search results and automate the page extraction.
Search and Extract PDF Pages Quickly with WPS Office
While automated extraction by keyword requires complex scripts, WPS Office provides an incredibly intuitive PDF Search and Page Extraction tool. You can quickly locate your terms and seamlessly extract the exact pages you need into a new, lightweight document without needing advanced coding knowledge.
- 1. Open your PDF document: Launch WPS Office and open the PDF file you wish to search and extract from.
- 2. Search for your keywords: Press Ctrl+F to open the search bar. Enter your keyword to find all instances, and jot down the page numbers where the relevant results appear.
- 3. Open the Extract tool: Navigate to the 'Page' tab on the top ribbon and click the 'Extract Page' button.
- 4. Input page numbers and extract: Select the 'Custom' page range option, input the specific page numbers you noted (e.g., 5, 12, 18-20), and click 'Extract' to save them as a new PDF.

Frequently Asked Questions
Can I extract PDF pages based on multiple search terms at the same time?
Yes, but this typically requires using an Advanced Search feature to look for multiple keywords, exporting the combined results to a CSV file, and then using a third-party script to extract the compiled list of pages.
Why is the search tool not finding words in my PDF?
If your PDF is created from scanned paper documents or images, it does not contain readable text layers. You must first use an OCR (Optical Character Recognition) tool to convert the document into searchable text before searching or extracting.
Is there a free, fully automated way to extract pages by search result?
Fully automated, one-click solutions for this specific task are generally found in paid third-party scripts or plugins. The best free alternative is to manually search the document, record the matching page numbers, and use a free PDF editor's built-in 'Extract Pages' tool to pull them out manually.


