

How to Extract Specific PDF Pages Using a Name List from Excel

Question details
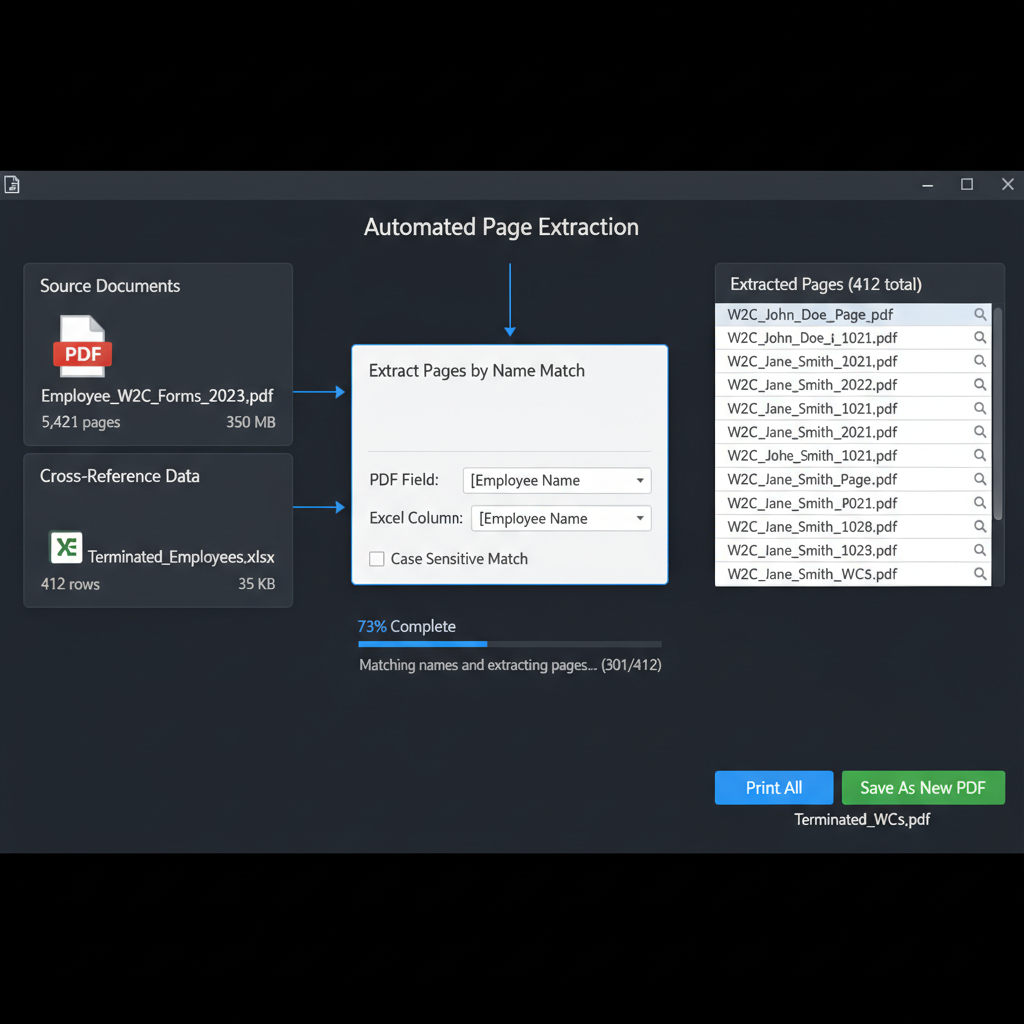
The user needs to extract or print specific pages from a large PDF document by cross-referencing a list of employee names stored in an Excel spreadsheet.
- Product
- PDF, Excel
- Device & OS
- not provided
- Scenario
- Filtering and managing a large batch of sensitive PDF documents (such as employee W-2C tax forms) based on a targeted list of terminated employees in an external spreadsheet.
- Observed behavior
- Manually searching for hundreds of specific employee names within a large PDF to extract their corresponding pages is highly inefficient and time-consuming.
Since you may be handling highly sensitive data like W-2C tax forms, ensure your environment is secure and avoid uploading confidential documents to unauthorized online third-party extraction tools.
Automate Page Extraction Using a Custom Script and CSV
Convert your Excel spreadsheet into a plain-text format and use a custom script or a dedicated document-processing tool to automate the matching and extraction of the PDF pages.
Standard PDF editors cannot natively read an Excel (.xlsx) file to automate page extraction. You will need to export the data and utilize an automated script to bridge the information between the spreadsheet and the PDF document.
Ensure your PDF document consists of searchable text. If it is a scanned document, you must run Optical Character Recognition (OCR) first so the script can accurately identify the employee names.
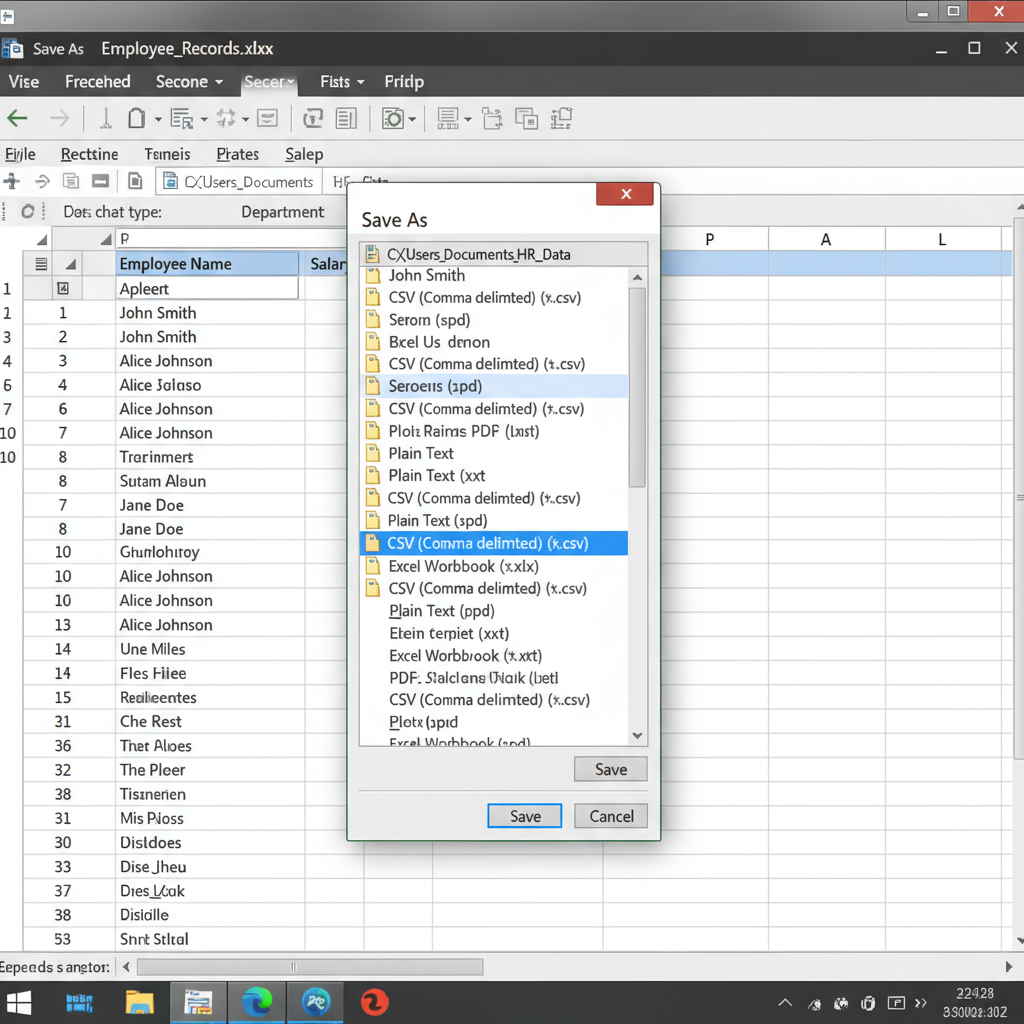
Open your Excel spreadsheet containing the list of names. Go to 'File', select 'Save As', and choose 'CSV (Comma delimited)' or 'Plain Text' format to make the data readable for scripts.
Open the large PDF file. Verify that the employee names or identifiers are readable text (not flat images). Use your PDF editor's OCR function if necessary.
Utilize a custom script (e.g., using Python with PyPDF2 and Pandas) or a specialized document processing tool. Configure the script to loop through the PDF, search for each name from your CSV file, and extract the matching pages into a new, secure PDF document.
Easily Extract PDF Pages and Manage Excel Lists with WPS Office
WPS Office offers a comprehensive suite featuring a powerful PDF editor and a robust Spreadsheet program. Seamlessly prepare your name lists in WPS Spreadsheet, and use WPS PDF to extract, split, or merge specific pages securely.
- 1. Prepare your data in Spreadsheets: Open your spreadsheet in WPS Office, format your employee list, and quickly save it as a CSV file via the 'Save As' menu.
- 2. Open and OCR the PDF: Launch your document in WPS PDF. If your document is scanned, use the built-in OCR tool to ensure all employee names are searchable text.
- 3. Extract the Required Pages: Navigate to the 'Page' tab and select 'Extract Page' to seamlessly separate the required pages, or integrate your prepared CSV with an offline automated script.

Frequently Asked Questions
Can I directly link an Excel file to my PDF editor to extract pages automatically?
No, standard PDF editors cannot natively read an Excel (.xlsx) file to automate page extraction. You generally need to save the Excel data as a CSV or plain text file and use a custom script or a specialized plug-in to bridge the two.
Are online PDF splitters safe for extracting tax forms?
It is highly discouraged. Tax forms like W-2Cs contain sensitive Personally Identifiable Information (PII). Uploading them to free online PDF tools exposes you to significant privacy and security risks. Always use secure, offline software for sensitive extraction.
How do I make sure the PDF text is readable by my extraction script?
If your PDF was created from a scan or image, you must first apply Optical Character Recognition (OCR) to convert the images into searchable text. This allows your script to identify and match employee names or IDs on the pages.


