

How to Extract Tabular PDF Data into Excel Without Column Borders

Question details
The user needs a reliable method to extract tabular data from a PDF that lacks visible column borders into a Microsoft Excel spreadsheet.
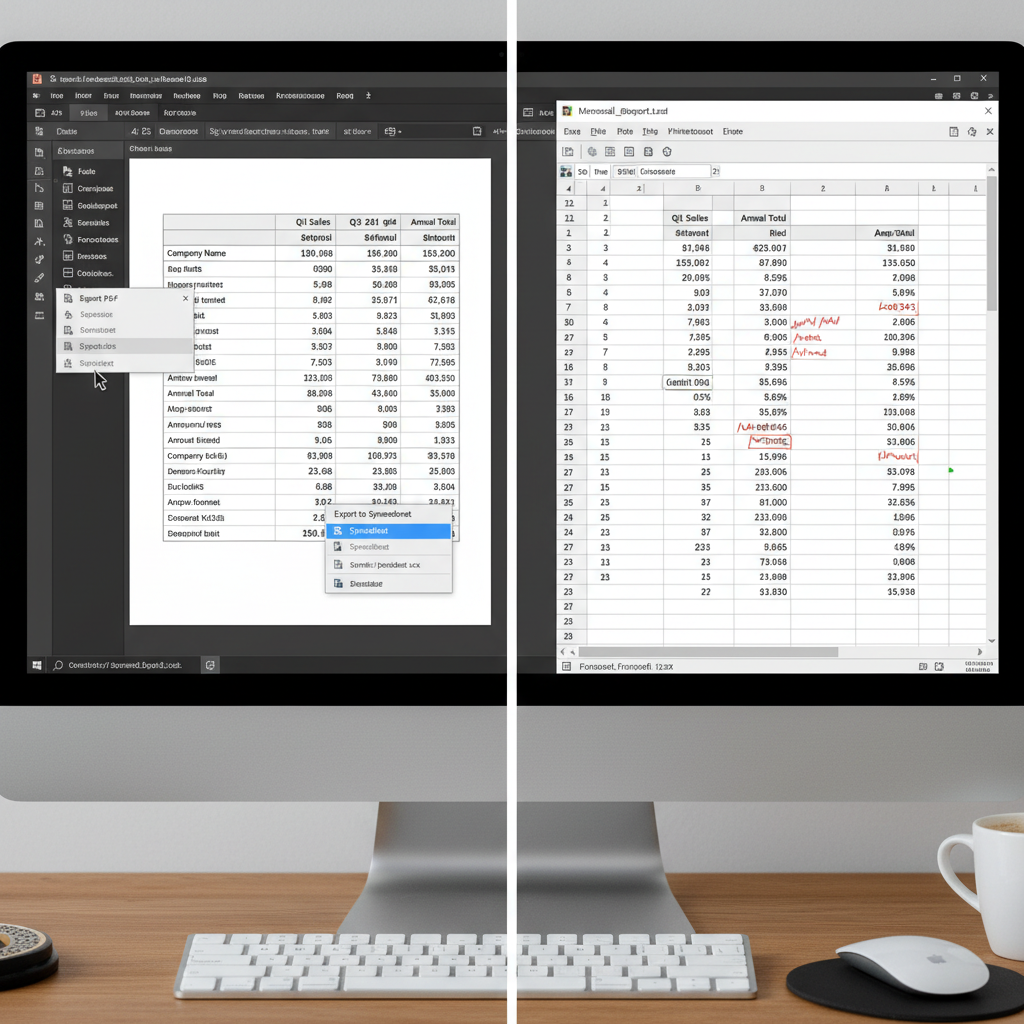
- Product
- Adobe Acrobat and Microsoft Excel
- Device & OS
- not provided
- Scenario
- Exporting borderless tabular data from a PDF document to Excel for further data manipulation.
- Observed behavior
- PDF editors cannot reliably infer column rules for borderless tables, resulting in improperly formatted Excel data that requires manual adjustment.
Ensure that the text in your PDF is selectable. If the document is a scanned image, you will need to perform Optical Character Recognition (OCR) first so the text can be successfully exported.
Export via Acrobat and Format with Excel Text to Columns
Use a PDF editor to export the raw text data into Excel, then manually split the data into structured columns using Excel's built-in tools.
Because PDF documents handle text purely based on coordinates rather than structural cells, borderless tables are particularly difficult to extract. Standard PDF editors cannot definitively know where one column ends and another begins. The most reliable method is to export the text as-is and structure it directly inside Excel.
Open your PDF file and try to highlight the tabular data. If you can highlight individual words, the document is searchable and ready for export.
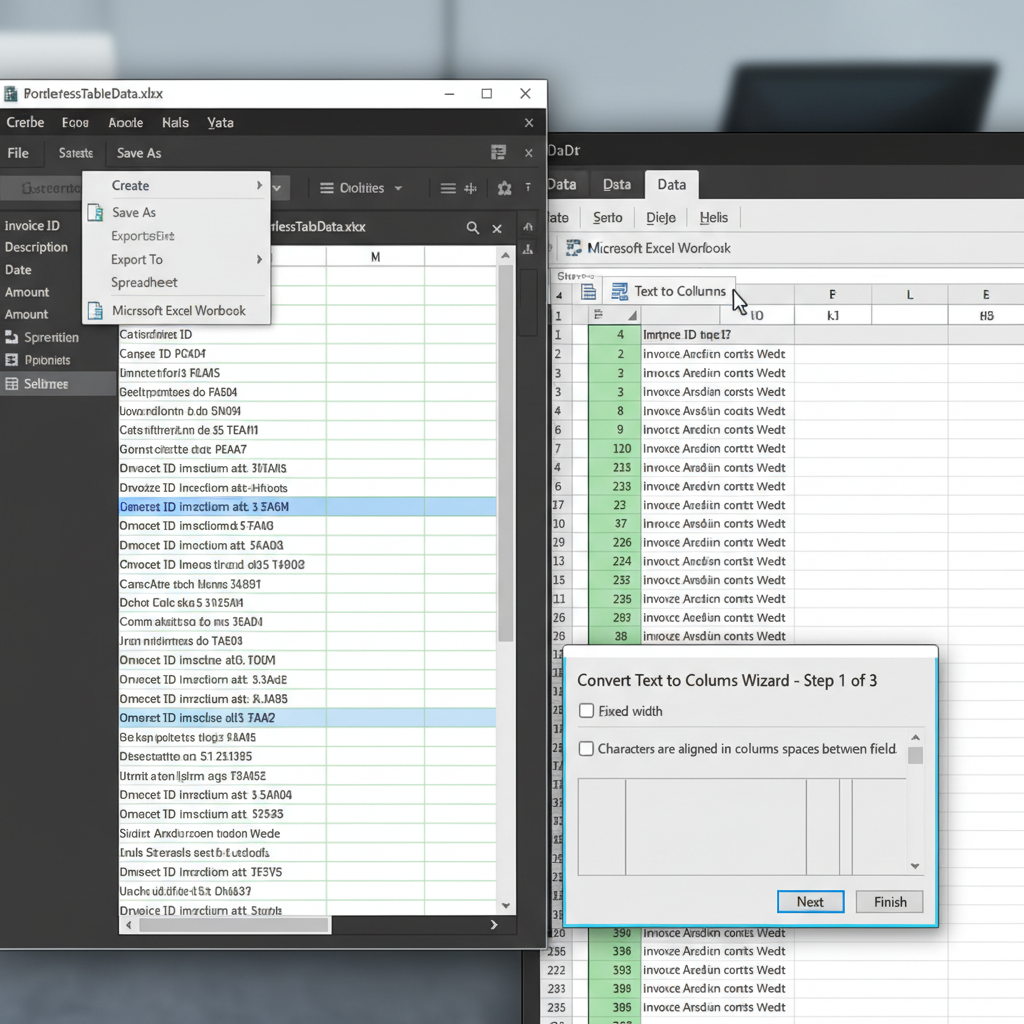
Navigate to 'File' > 'Export To' > 'Spreadsheet' > 'Microsoft Excel Workbook' and save the resulting file to your computer.
Open the exported file in Microsoft Excel. If the data is compressed into a single column, select the entire column containing your borderless table data.
Go to the 'Data' tab on the Excel ribbon and click on 'Text to Columns'.
Choose 'Fixed width' since the data is from a table, click 'Next', visually set your column breaks where the gaps in the data appear, and click 'Finish'.
Convert PDF to Excel Flawlessly with WPS Office
WPS Office provides an advanced PDF to Excel converter that intelligently detects table structures and spacing, even without explicit borders, saving you hours of manual formatting in Excel.
- 1. Open PDF in WPS Office: Launch WPS Office on your computer and open the target PDF file containing the tabular data.
- 2. Select PDF to Excel Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'PDF to Excel' conversion feature.
- 3. Convert and Format: Select the pages you wish to convert, set your output folder, and click 'Convert' to automatically generate a seamlessly formatted spreadsheet.

Frequently Asked Questions
Why does my extracted PDF table look messy in Excel?
PDF files are designed for fixed layout presentation, not structured data storage. When tables lack explicit borders, PDF editors struggle to identify where columns begin and end, causing data to merge or misalign during export.
How can I convert a scanned borderless PDF table to Excel?
You must first use OCR (Optical Character Recognition) software to convert the image into searchable text. Once recognized, you can export the document to Excel and use the 'Text to Columns' tool to organize the data manually.
Can I manually draw borders in the PDF before exporting?
Drawing visual lines on a PDF using standard annotation tools will not help with data extraction. Export engines parse the underlying text positioning rather than visual line annotations drawn over the document.
Is there a way to extract only a specific borderless table instead of the whole page?
Yes. You can use the text selection tool in your PDF viewer to highlight just the tabular data you need, copy it, and paste it directly into an Excel worksheet. Afterwards, apply the 'Text to Columns' function to separate the data into standard cells.


