

How to Extract Text from a PDF and Use It as the File Name

Question details
The user wants to locate specific text in a consistent area of a PDF, such as a bill date or invoice number, and use that extracted value to rename the file.
- Product
- Device & OS
- not provided
- Scenario
- Organizing and renaming PDF files based on their internal text content to streamline document management.
- Observed behavior
- The goal is to automate the extraction of specific text from the PDF and map it directly to the document's file name.
Ensure your PDFs are text-searchable; if you are dealing with scanned documents or images, you must perform OCR (Optical Character Recognition) first to make the text selectable.
Automate Renaming Using Adobe Acrobat Action Wizard
For users with Adobe Acrobat Pro, you can use the Action Wizard combined with a custom JavaScript snippet to locate specific text and rename the file automatically.
Acrobat alone does not have a native one-click button to rename files based on positional text. To accomplish this, you must rely on advanced scripting or custom actions that extract text values and assign them to the output filename.
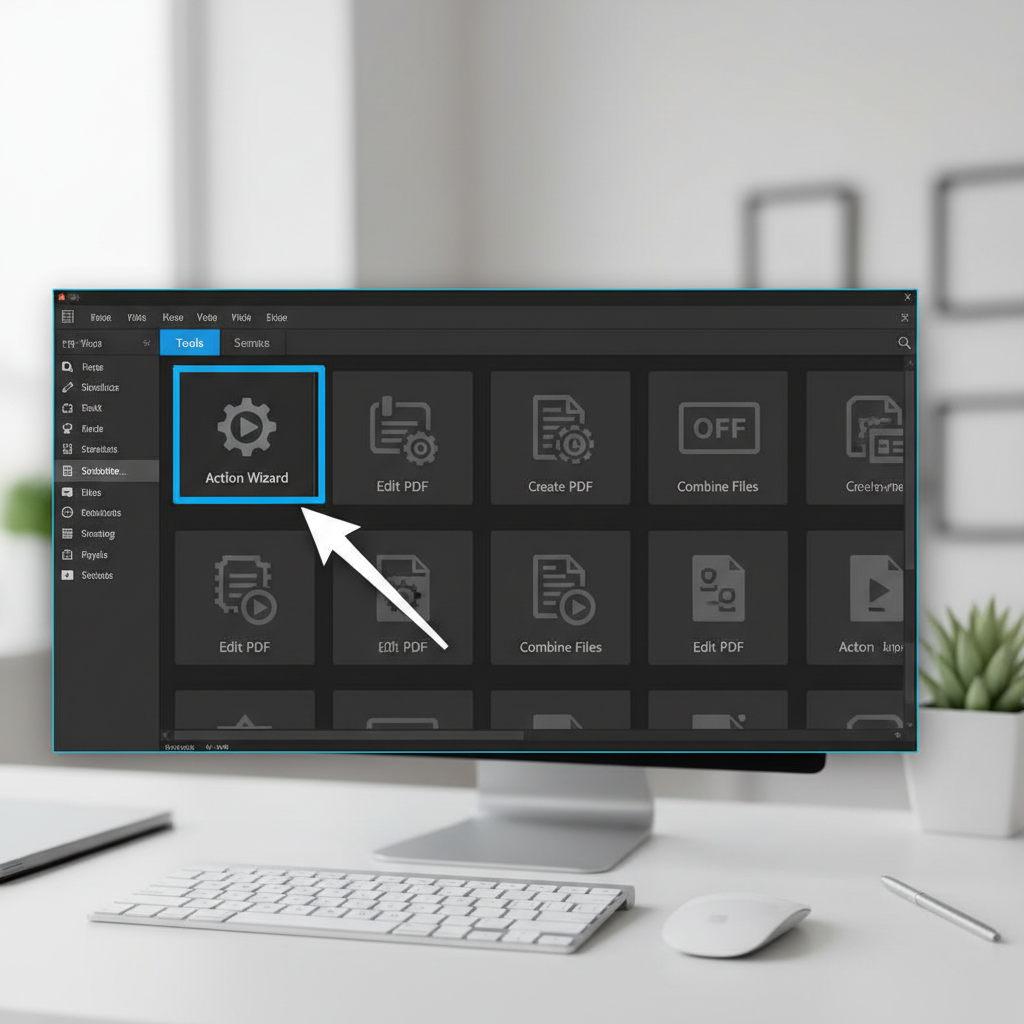
Launch Adobe Acrobat Pro, navigate to the 'Tools' tab, and select 'Action Wizard'.
Click 'New Action' from the top toolbar. Add the files or folders containing the PDFs you want to process into the 'Files to be Processed' panel.
Under 'Choose tools to add', expand 'More Tools' and click 'Execute JavaScript'. Click the '+' icon to add it to your action steps.
Uncheck 'Prompt user', click 'Specify Settings', and paste your custom JavaScript code designed to extract the text (e.g., using the getPageNthWord method) and save the document with the new name.
Save the action with a descriptive name. Click on your newly created action in the Action List and hit 'Start' to batch rename your PDFs.
Manually Extract Text and Save As
If you only have a few files to process, manually copying the target text and renaming the file during the 'Save As' process is the most reliable method.
Extract Text and Manage PDFs Easily with WPS Office
WPS Office features a powerful PDF editor equipped with advanced OCR technology. Whether you need to extract invoice numbers manually or convert scanned bills into editable formats, WPS PDF makes selecting text and managing your files incredibly simple.
- 1. Open PDF in WPS Office: Launch WPS Office and open your target PDF document.
- 2. Run OCR (If Scanned): If the text cannot be highlighted, click on the 'Tools' tab and select 'OCR' to convert the image to selectable text.
- 3. Copy Target Text: Highlight the bill date or specific text you want to use for the file name, right-click, and select 'Copy'.
- 4. Save with New Name: Click 'Menu' in the top-left corner, choose 'Save As', paste the copied text into the File Name box, and click 'Save'.

Frequently Asked Questions
Can I batch rename multiple PDFs based on their text content automatically?
Yes, but standard PDF readers do not offer this natively. You will need dedicated batch processing software, advanced tools like Adobe Acrobat Pro using custom JavaScript, or third-party file renaming utilities that support PDF content extraction.
Why can't I select or extract the text from my PDF?
If you cannot highlight text in your PDF, the document is likely a scanned image or has been flattened. You must apply OCR (Optical Character Recognition) using a PDF editor like WPS Office to convert the image into recognizable, selectable text before extracting it.
How do I extract a specific coordinate's text in a PDF using code?
If you are writing a custom script in Adobe Acrobat, you can use the JavaScript method getPageNthWord() by looping through words on a page and matching their quad or coordinate properties to find text located exclusively in the upper-right corner.


