

How to Extract Text from an Image-Only PDF

Question details
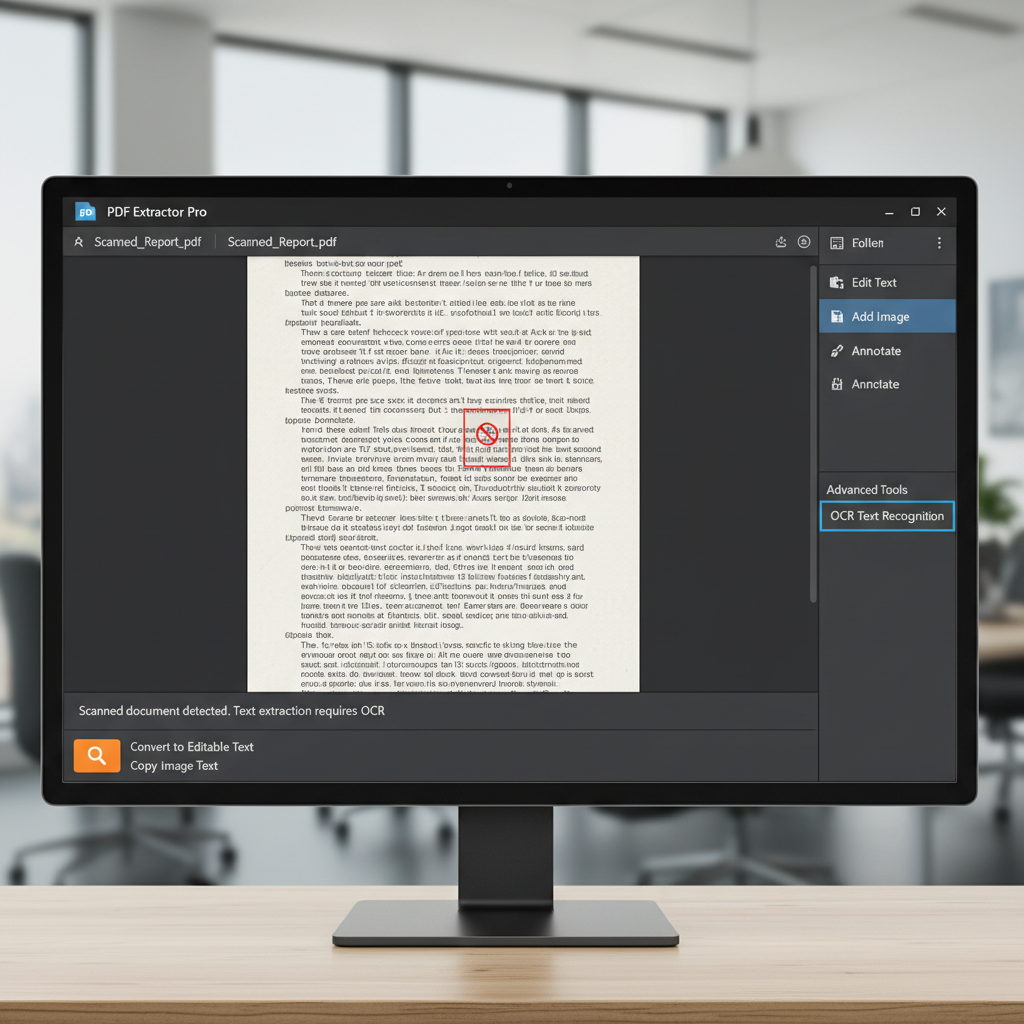
The user needs a method to extract editable plain text from a PDF document that consists entirely of scanned images.
- Product
- Device & OS
- not provided
- Scenario
- Attempting to copy, convert, or extract text content from an image-only or scanned PDF document.
- Observed behavior
- Text cannot be selected or extracted directly because the PDF lacks a text layer, necessitating the use of Optical Character Recognition (OCR).
Ensure your scanned PDF has adequate resolution and lighting; removing unnecessary headers, footers, and complex graphics before processing will significantly improve OCR text recognition accuracy.
Export the PDF to Word with OCR Enabled
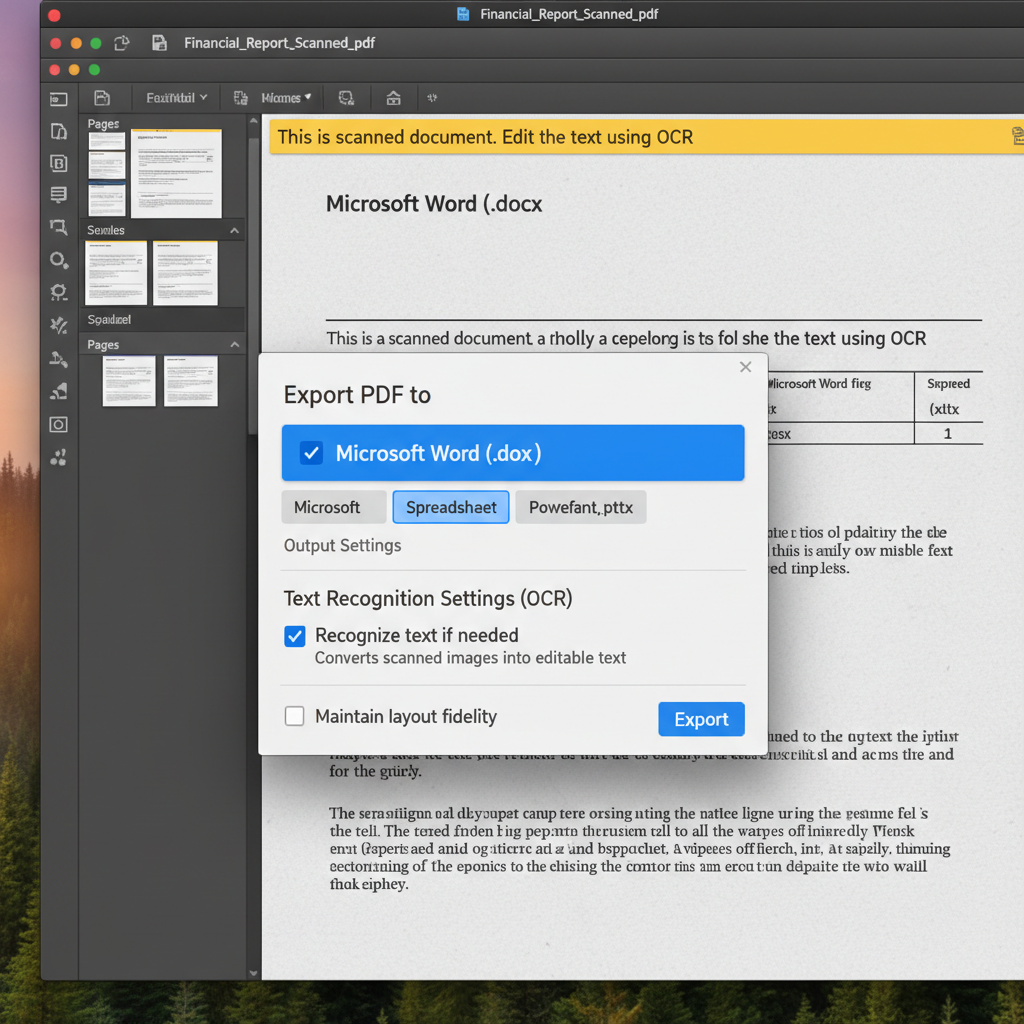
Use a PDF editor's export feature with text recognition capabilities to convert the scanned images into an editable Word document.
This method is highly effective for clear image-based PDFs, as modern PDF editors can automatically recognize text characters and reconstruct the layout into an editable Word file.
Before exporting, use a PDF cropping tool to remove unnecessary graphics, page borders, headers, and footers that might clutter the final text output.
Open the image-only PDF in your preferred PDF editor (such as Adobe Acrobat or WPS Office) and navigate to the 'Export to Word' or 'PDF to Word' conversion tool.
Look for a settings checkbox labeled 'Recognize text if needed' or 'Enable OCR' and ensure it is selected prior to starting the conversion.
Click export and wait for the process to finish. Open the newly generated Word document to review the extracted text, manually correcting any hyphenation or ligature errors caused by unique fonts.
Run a Dedicated OCR Scan on the Original PDF
Process the file using specialized OCR software to embed a searchable text layer directly into the original PDF.
Extract Text from Scanned PDFs Instantly with WPS Office
WPS Office includes a highly accurate, built-in OCR feature that effortlessly recognizes text within image-only PDFs. You can extract text or convert scanned documents directly into editable Word files with just a few clicks.
- 1. Open the PDF: Launch WPS Office and open your scanned or image-only PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on 'OCR'.
- 3. Select Extraction Mode: Choose whether you want to 'Extract Text' directly on the screen or 'Convert to Word' for a completely editable document.
- 4. Process and Save: Confirm the language settings and initiate the scan. Once finished, save your newly extracted text or Word document to your device.

Frequently Asked Questions
Why can't I select or copy text in my PDF?
If your PDF was created from a scanner or saved as an image, it functions like a photograph and lacks a digital text layer. You must use Optical Character Recognition (OCR) software to analyze the image and generate selectable text.
How can I improve OCR accuracy on poor-quality PDFs?
To improve OCR text recognition, ensure the original scan has high contrast and is not blurry. Cropping out dark edges, unnecessary graphics, and complex headers before running the OCR tool can also significantly reduce text conversion errors.
Can I extract text from an image PDF for free?
Yes, many free tools and online converters offer basic OCR functionality. Comprehensive free office suites like WPS Office also provide powerful built-in OCR tools that allow you to extract plain text or convert the PDF to an editable Word document.


