

How to Fix Acrobat Cannot Find Paper Capture & OCR Recognition Errors

Question details
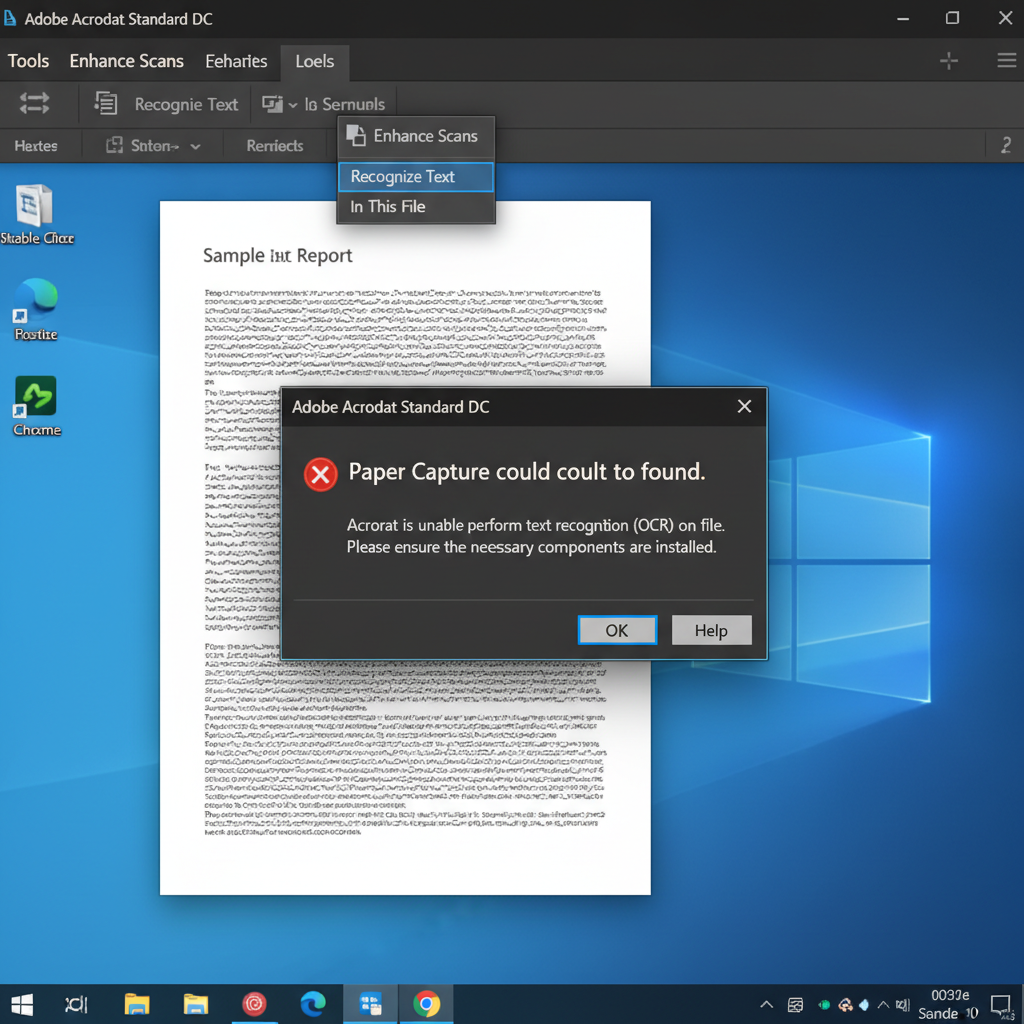
The user needs to fix an OCR failure in Acrobat Standard DC where the software fails to recognize text in scanned PDFs and states it cannot find Paper Capture.
- Product
- Adobe Acrobat Standard DC
- Device & OS
- Windows
- Scenario
- Attempting to run text recognition (OCR) on newly scanned documents after installing a new printer.
- Observed behavior
- Acrobat fails to process the scanned document, displaying an error that it cannot access or locate the recognition service/Paper Capture component.
Ensure you are logged in to your Windows computer with administrator privileges, as repairing or reinstalling core PDF software components requires administrative rights.
Repair the Acrobat Installation
Use the built-in repair tool to restore missing or corrupted OCR and Paper Capture components.
The 'cannot find Paper Capture' error is typically caused by missing or damaged OCR libraries rather than the physical scanner or printer. Running a software repair will verify and replace the missing recognition service files.
Launch your Acrobat Standard DC application on your Windows PC.
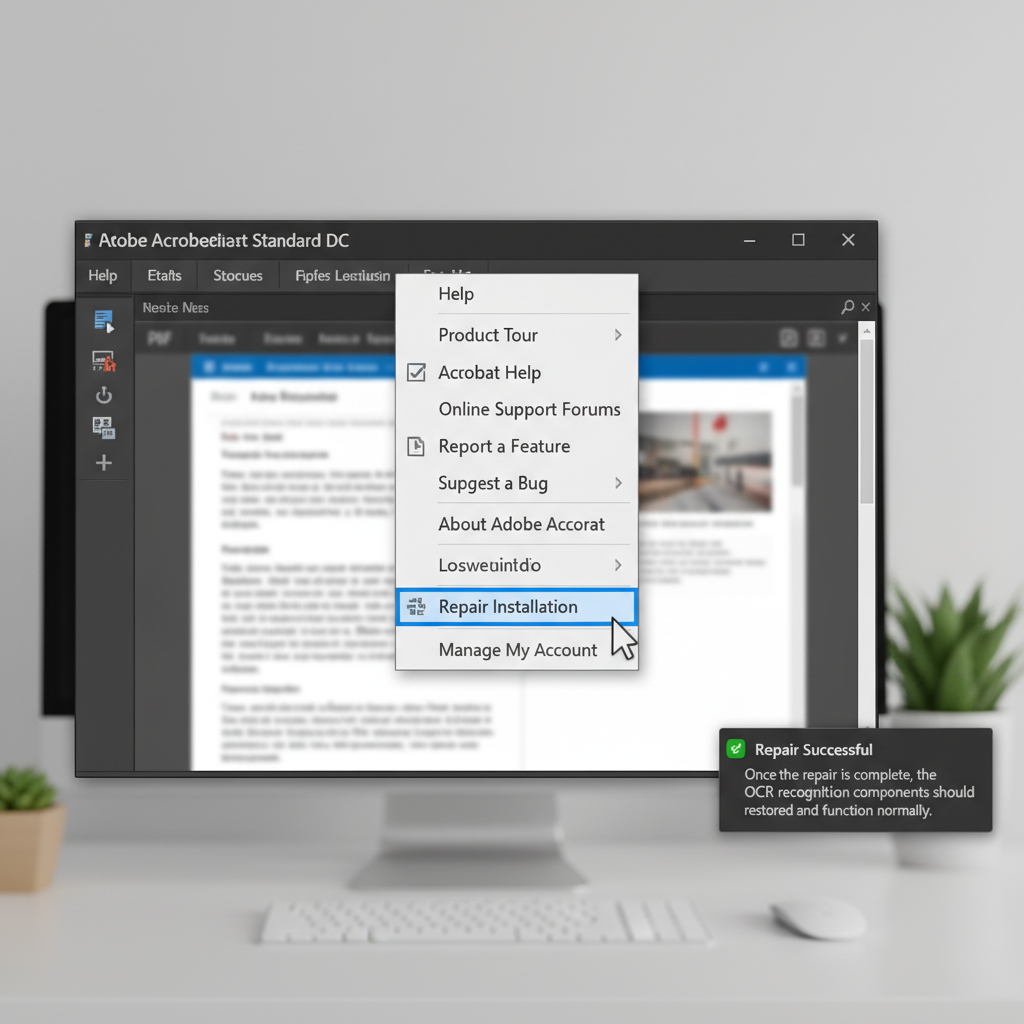
Click on the 'Help' menu at the top of the application window and select 'Repair Installation'.
Follow the on-screen instructions to complete the repair process, then restart your computer before attempting to OCR a document again.
Update Acrobat to the Latest Version
Check for available software updates to resolve known bugs related to the recognition service.
Extract Text from Scanned PDFs Instantly with WPS PDF
If your current PDF reader's OCR components remain corrupted, you can seamlessly recognize and extract text from any scanned document using the built-in OCR feature in WPS PDF.
- 1. Open Scanned Document: Launch WPS Office and open your scanned PDF document.
- 2. Access OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Select Output Mode: Choose whether you want to extract the text on screen or convert the entire document to an editable Word format.
- 4. Process Document: Select the document's language and click 'Start OCR' to quickly turn the scanned image into selectable text.

Frequently Asked Questions
Why does my PDF software say it cannot access the recognition service?
This error occurs when the core OCR modules or internal Paper Capture libraries have been corrupted, accidentally deleted, or blocked by restrictive Windows permissions.
Can installing a new scanner or printer break PDF OCR functionality?
While uncommon, installing a new printer or scanner can occasionally alter registry settings or replace shared system drivers, creating a conflict that prevents the PDF software from accessing its text recognition services.
How do I know if my PDF actually needs OCR?
If you try to highlight, select, or search for text within a PDF and nothing registers (the page acts as a flat photograph), it is a scanned image file that requires OCR to become searchable and editable.
Does WPS Office offer OCR functionality?
Yes, WPS Office includes a powerful built-in OCR tool within its PDF editor, allowing you to quickly extract text from scanned images and convert them into editable documents without installing secondary plugins.


