

How to Fix Acrobat DC Not Creating Searchable OCR PDFs

Question details
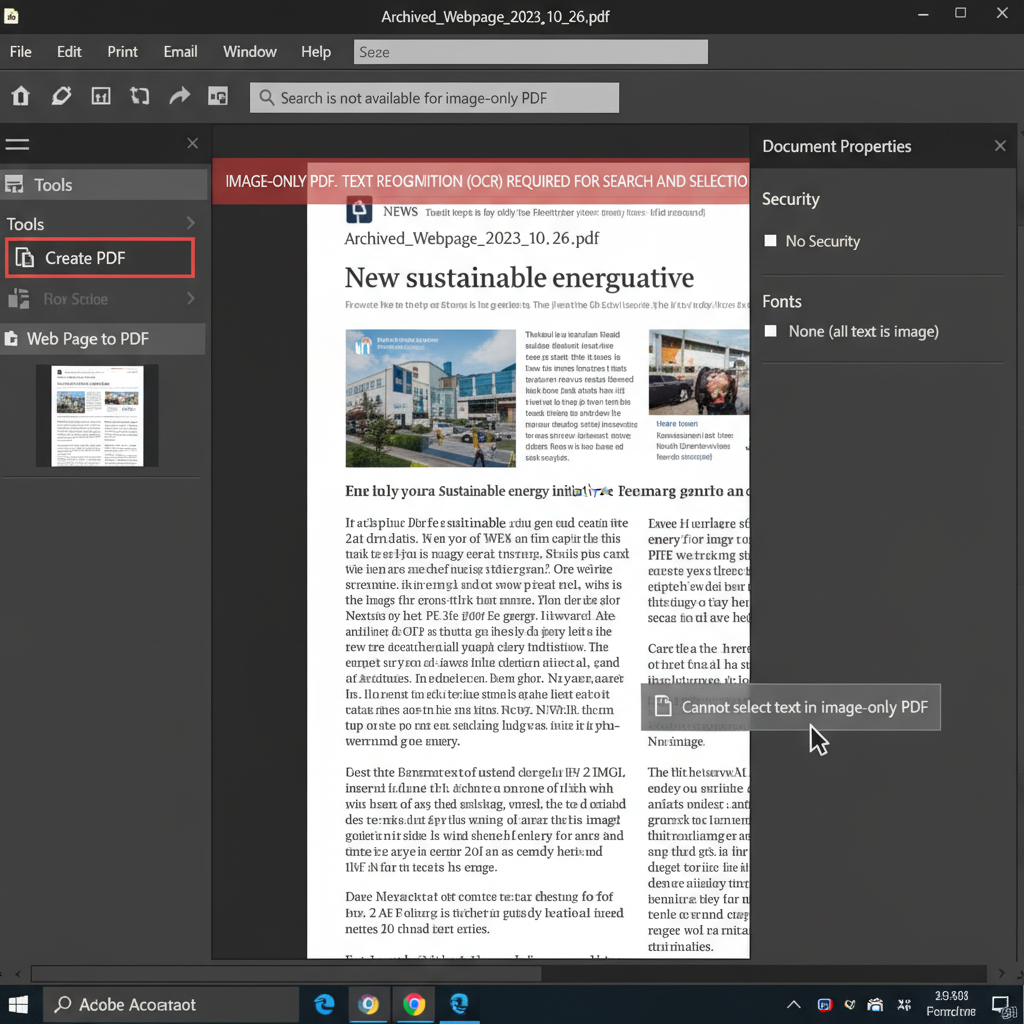
The user needs to make PDFs generated from web captures searchable, as the current output prevents keyword searches and text selection.
- Product
- Adobe Acrobat DC
- Device & OS
- not provided
- Scenario
- Using a web capture workflow to save web pages as PDF documents for archiving or reading.
- Observed behavior
- The software creates an image-only PDF without executing optical character recognition (OCR), leaving the text unsearchable.
Verify that your document is not secured with a permissions password that restricts text extraction, and ensure you are using the premium Adobe Acrobat DC version, as the free Adobe Reader cannot perform OCR.
Manually Run OCR on the Image-Only PDF
Force Acrobat to analyze the image and recognize the text to make the document fully searchable.
When an automated capture fails to process text, you can manually trigger the Optical Character Recognition (OCR) engine. This method scans the visual text in your image-only PDF and adds a hidden layer of searchable text.
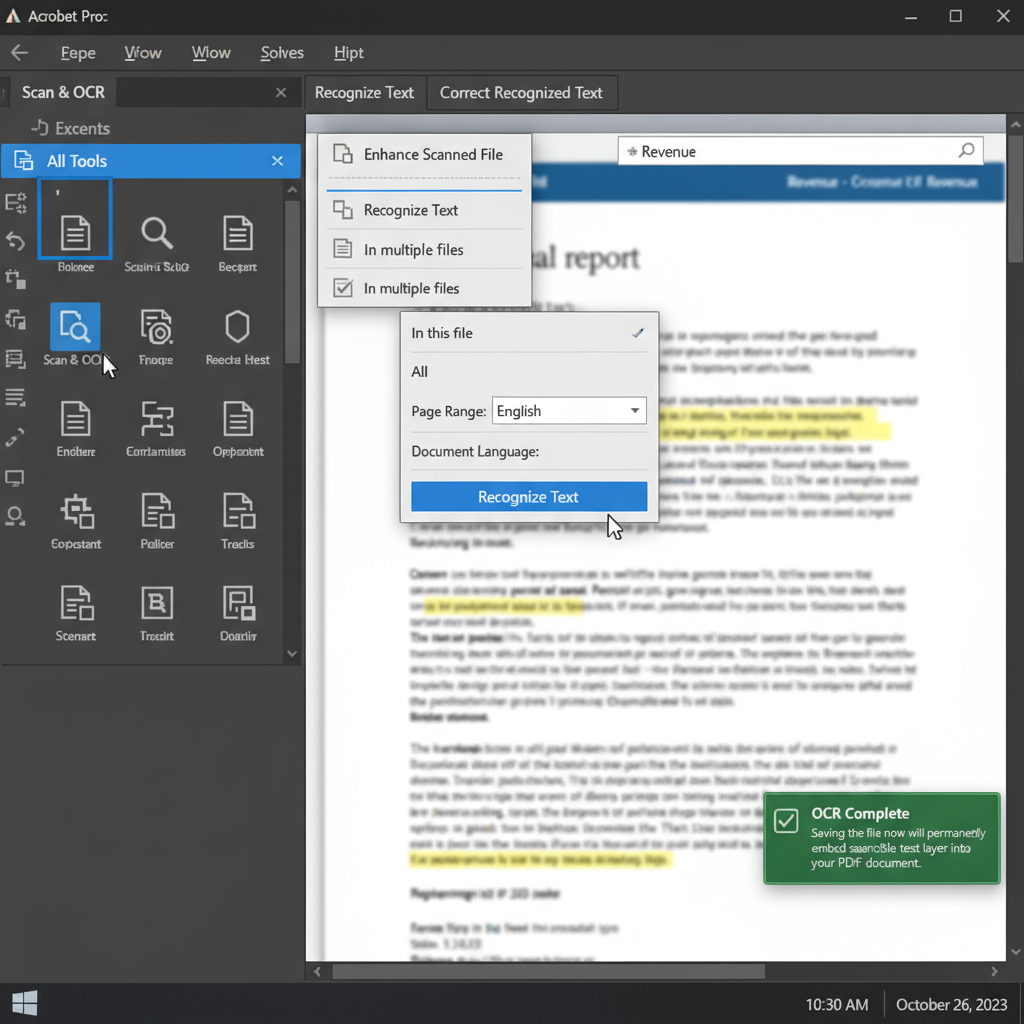
Launch Adobe Acrobat DC, open your captured PDF, click on 'All Tools' in the menu, and select 'Scan & OCR'.
Click on 'Recognize Text' from the available options, select 'In this file', and ensure the correct document language is selected.
Click the 'Recognize Text' button to start processing. Once finished, press Ctrl+F (or Cmd+F on Mac) to search for a keyword and confirm the document is now searchable.
Check Settings and Repair Acrobat Installation
Fix underlying software issues if automatic OCR fails during web capture or if the OCR tool is completely missing.
Easily Create Searchable PDFs with WPS Office
If your current software struggles with text recognition, use WPS PDF to seamlessly apply OCR to any image-only document, making it fully searchable and editable in seconds.
- 1. Open the file in WPS PDF: Launch WPS Office and open your unsearchable, image-based PDF document.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and click the 'OCR' button.
- 3. Select OCR parameters: Choose 'Convert to Searchable PDF', select the language of your document, and confirm.
- 4. Save the new document: Wait a few moments for the process to finish, then save your newly converted, fully searchable PDF file.

Frequently Asked Questions
Why did my PDF save as an image instead of text?
This happens when a document is created using a scanner or a web capture tool that simply takes a snapshot of the visual content without running an Optical Character Recognition (OCR) engine to convert the pixels into digital text.
Does Adobe Acrobat Reader have the OCR feature?
No, the free Adobe Acrobat Reader does not include OCR capabilities. You need a premium subscription like Acrobat Pro DC, or a capable alternative like WPS Office, to perform text recognition on image-only PDFs.
How do I know if my PDF is searchable before trying OCR?
Try clicking and dragging your mouse over the text. If you can highlight individual words and sentences, the PDF is already searchable. If the entire page highlights as one large block, it is an image-only PDF.
Can OCR accurately recognize handwritten notes?
Standard OCR technology is optimized for printed, typed fonts. While advanced OCR can recognize highly legible handwriting, the results are typically inconsistent and may require extensive manual proofreading.


