

How to Fix Acrobat Error 15 When Extracting PDF Pages

Question details
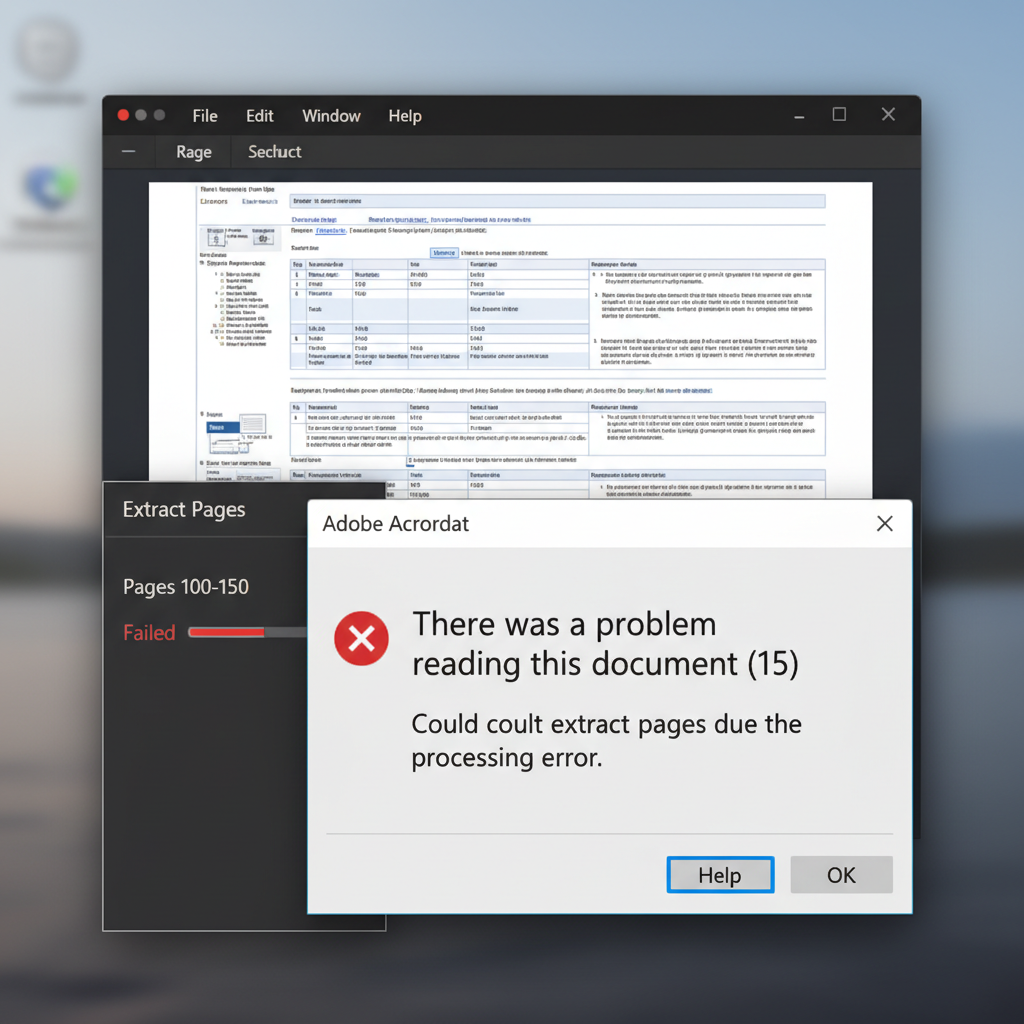
The user encounters Error 15 when attempting to extract pages from a structurally complex or large PDF document.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Extracting specific pages or page ranges from a large PDF file containing numerous cross-references and internal links.
- Observed behavior
- Acrobat fails the extraction process and displays the error message: 'There was a problem reading this document (15)'.
Before proceeding, check your system resources to ensure your computer has sufficient available RAM and free disk space, as extracting pages from complex PDFs is highly resource-intensive.
Split the Document by Deleting Pages and Saving
Bypass the extraction error by manually dividing the large PDF into smaller, manageable sections using the Delete and Save As functions.
If a PDF contains heavy internal linking and cross-references, Acrobat struggles to process the entire file during standard extraction. Manually deleting unwanted pages and saving as a new file bypasses this memory bottleneck.
Open your large or complex PDF document in Adobe Acrobat.
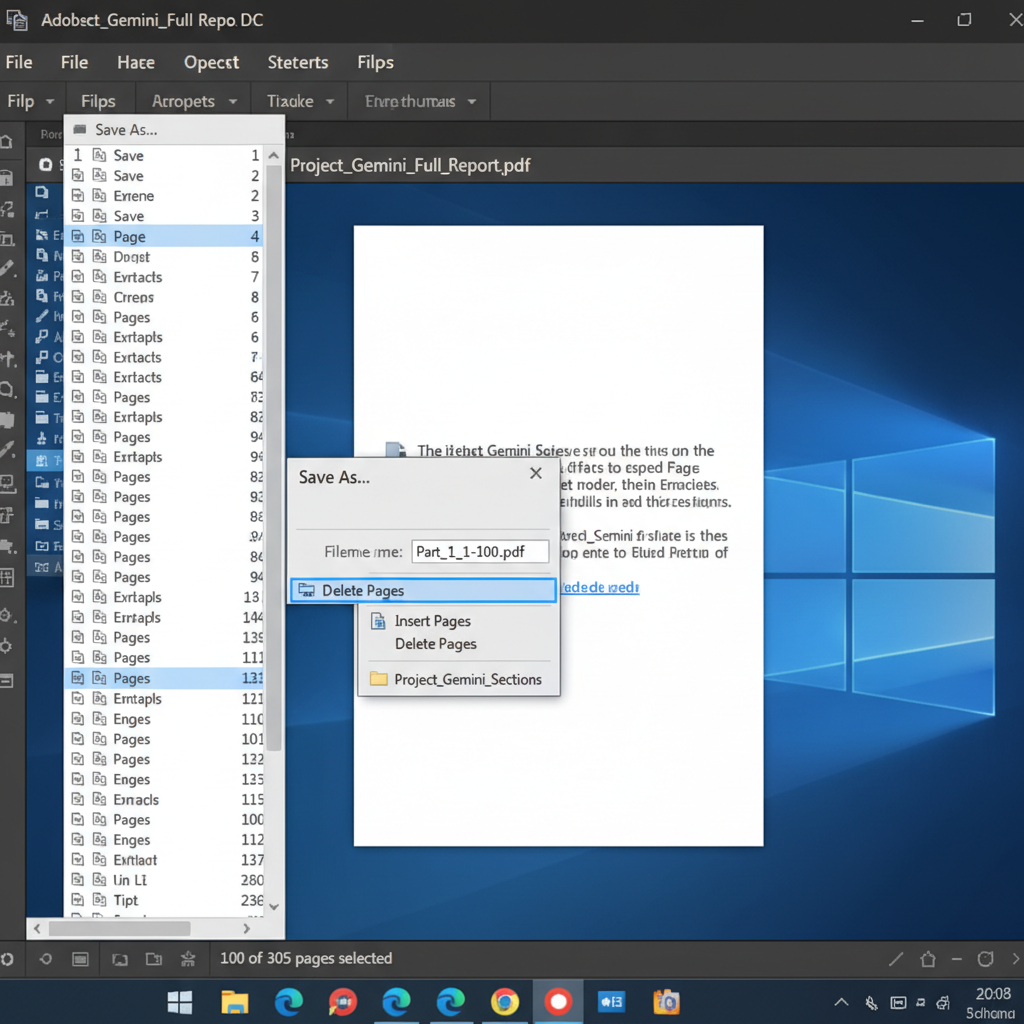
Navigate to the page thumbnails, select pages from 101 onward (or a suitable chunk), and delete them so only pages 1–100 remain.
Go to 'File' > 'Save As' and save this portion as a new document (e.g., 'Part_1_1-100.pdf'). Do not simply click 'Save', or you will overwrite the original file.
Reopen the original large PDF, delete pages 1–100 and pages 201 onward, and use 'Save As' to create 'Part_2_101-200.pdf'. Repeat this process adjusting the page ranges as needed based on the document's structure.
Once the document is divided into multiple 100-page sections, open the specific smaller section you need and extract the required pages without triggering Error 15.
Free Up System Memory and Disk Space
Ensure your system has the necessary hardware resources available to process large PDFs.
Extract Pages from Large PDFs Seamlessly with WPS Office
If Acrobat continues to display Error 15, switch to WPS PDF. Its lightweight engine efficiently handles large, complex files, allowing you to extract, split, or merge pages without software crashes or resource overloads.
- 1. Open your PDF: Launch WPS Office and open your large PDF document.
- 2. Navigate to the Page tools: Click on the 'Page' tab located in the top menu bar to access the page management tools.
- 3. Select Extract Page: Click the 'Extract Page' button from the toolbar options.
- 4. Define your page range: In the dialog box, choose the specific page range or select individual pages you wish to extract.
- 5. Complete the extraction: Click 'Extract' to securely split the pages into a new PDF document, bypassing any structural errors.
Frequently Asked Questions
What does 'There was a problem reading this document (15)' mean in Acrobat?
Error 15 typically indicates that Acrobat is struggling to process the structural complexity of a PDF. This often happens due to an abundance of cross-references, internal links, or excessive file size, especially when system memory or disk space is low.
Can I prevent Error 15 without having to split my PDF document?
Sometimes. Closing background applications to free up RAM or clearing your disk space can provide enough resources for Acrobat to process the extraction. Alternatively, you can try printing the document to a new PDF (using 'Microsoft Print to PDF'), which flattens complex structures, though this will remove internal hyperlinks.
Why does my PDF have so many cross-references causing this error?
PDFs generated from large technical manuals, CAD software, or extensively hyperlinked Word documents naturally contain thousands of internal references. When Acrobat attempts to extract pages, it tries to parse all these links simultaneously, leading to memory overload.


