

How to Fix Acrobat Treating PDF Text as Images and Preventing Copying

Question details
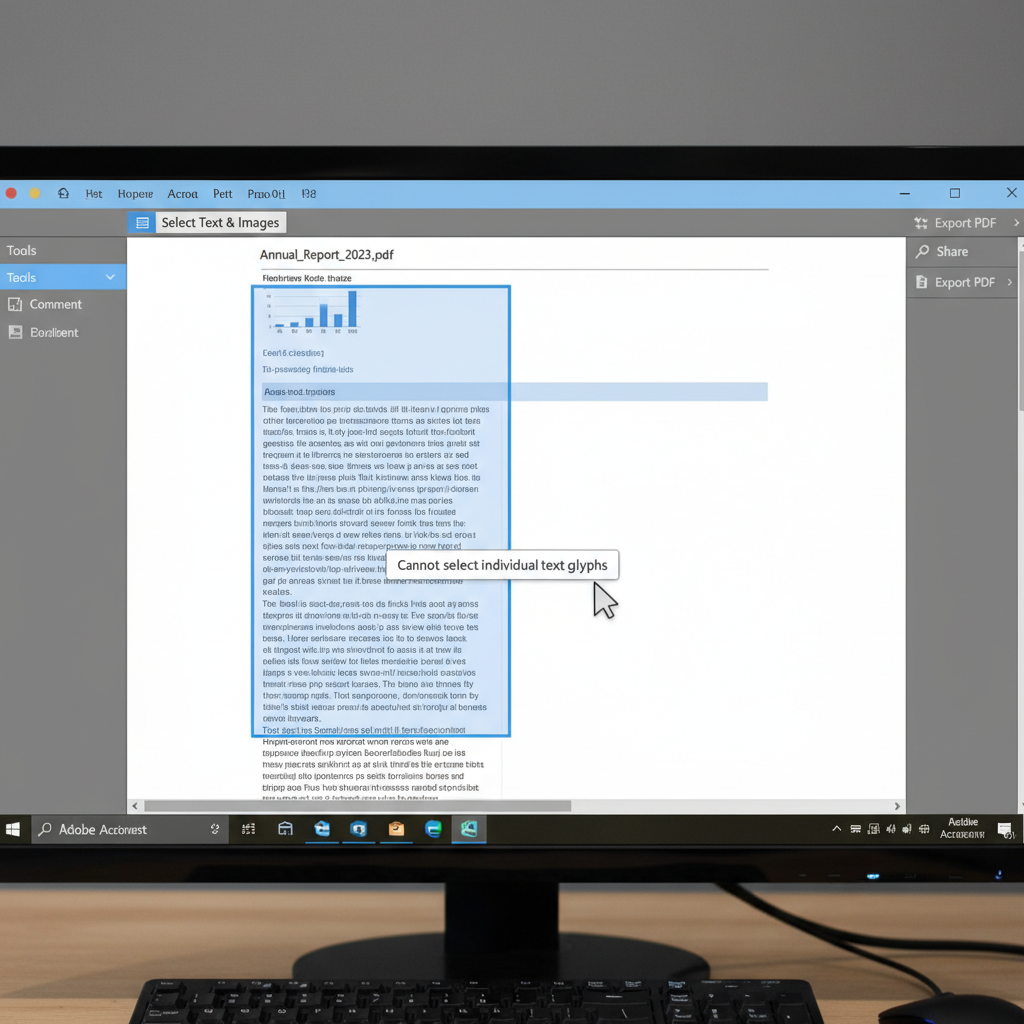
Users are unable to select, copy, or paste text in a PDF because the software treats the document like a giant page-sized image or a collection of overlapping object boxes.
- Product
- Adobe Acrobat
- Device & OS
- Windows 7, Windows 10
- Scenario
- Attempting to copy text from a PDF or export the PDF to Word, but the resulting document contains inaccessible text wrapped in image borders.
- Observed behavior
- When clicking or highlighting, the entire page content moves as one object. Text cannot be individually selected, and exporting to other formats produces inaccessible image boxes instead of editable text.
Before proceeding, determine if your PDF is natively generated from a word processor or if it is a scanned document. Scanned PDFs consist of images, requiring Optical Character Recognition (OCR) to convert those images into editable text.
Use Scan & OCR to Recognize Text
Applying Acrobat's OCR feature will analyze the image-based PDF and generate a hidden layer of selectable text over the image.
If a PDF was created via a scanner or saved strictly as an image, it lacks a text layer. Running the built-in OCR (Optical Character Recognition) tool scans the visual shapes and converts them into actual characters that you can highlight, copy, and paste.
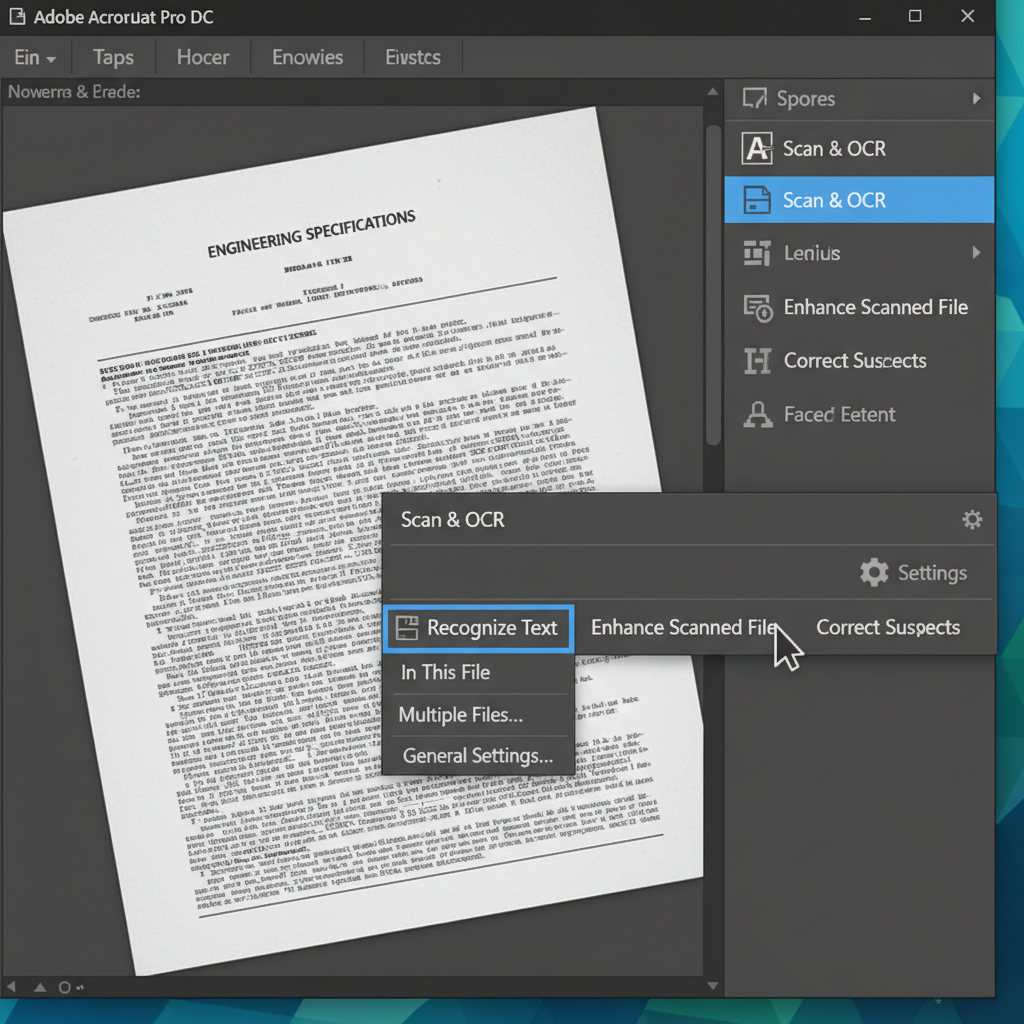
Open the problematic PDF in Adobe Acrobat. On the right-hand tools pane, scroll down and click on 'Scan & OCR'.
In the Scan & OCR toolbar, click on 'Recognize Text' and choose 'In This File' from the dropdown menu.
Click on 'Settings' (the gear icon) to ensure the correct document language is selected. This drastically improves the accuracy of text recognition.
Click the 'Recognize Text' button. Wait for Acrobat to process the pages. Once completed, try highlighting the text with your cursor.
Export PDF to Word with Text Recognition Enabled
If you need to completely edit the document's content, exporting it directly to Word with OCR settings enabled ensures the resulting file contains typed text rather than inserted images.
Use WPS Office to Easily OCR and Edit Scanned PDFs
If you are struggling with unselectable PDF text, WPS Office provides a powerful, built-in OCR feature that effortlessly extracts text from image-based PDFs. You can instantly convert scanned documents into fully editable text or Word formats.
- 1. Open the PDF: Launch WPS Office and open your image-based or scanned PDF document.
- 2. Navigate to the OCR Tool: Click on the 'Tools' tab in the top ribbon and select the 'OCR' feature.
- 3. Extract Text: Select the specific pages or screen area you want to scan, set your document's language, and click 'Extract Text' to instantly make the content selectable and copiable.

Frequently Asked Questions
Why does my entire PDF page move when I try to highlight text?
This occurs because the PDF was created as a single, large image (often from a scanner) and does not contain an underlying text layer. The software sees the page as one solid photograph, meaning you must use OCR to recognize and separate the characters from the background.
How can I tell if a PDF has selectable text before trying to copy it?
Try hovering over the text with your mouse. If the cursor changes from an arrow or hand to an 'I-beam' text selector, the text is recognizable. If the cursor remains a hand and dragging it highlights the whole page in blue, the document is an image-based PDF.
Why is my exported Word document still showing text in uneditable image boxes?
If a PDF is not processed with OCR before or during the export, Word will simply place the exact page images into the new document. You must ensure that OCR or 'Recognize text' is explicitly enabled in your PDF editor's export settings.
Does OCR always perfectly recognize and convert PDF text?
Not always. OCR accuracy depends heavily on the image quality, resolution, font clarity, and background noise of the original scan. Malformed PDFs or pages with heavy artifacts may produce inaccurate text that requires manual correction.


