

How to Fix Missing Spaces in Accessible Text Exported from PDFs

Question details
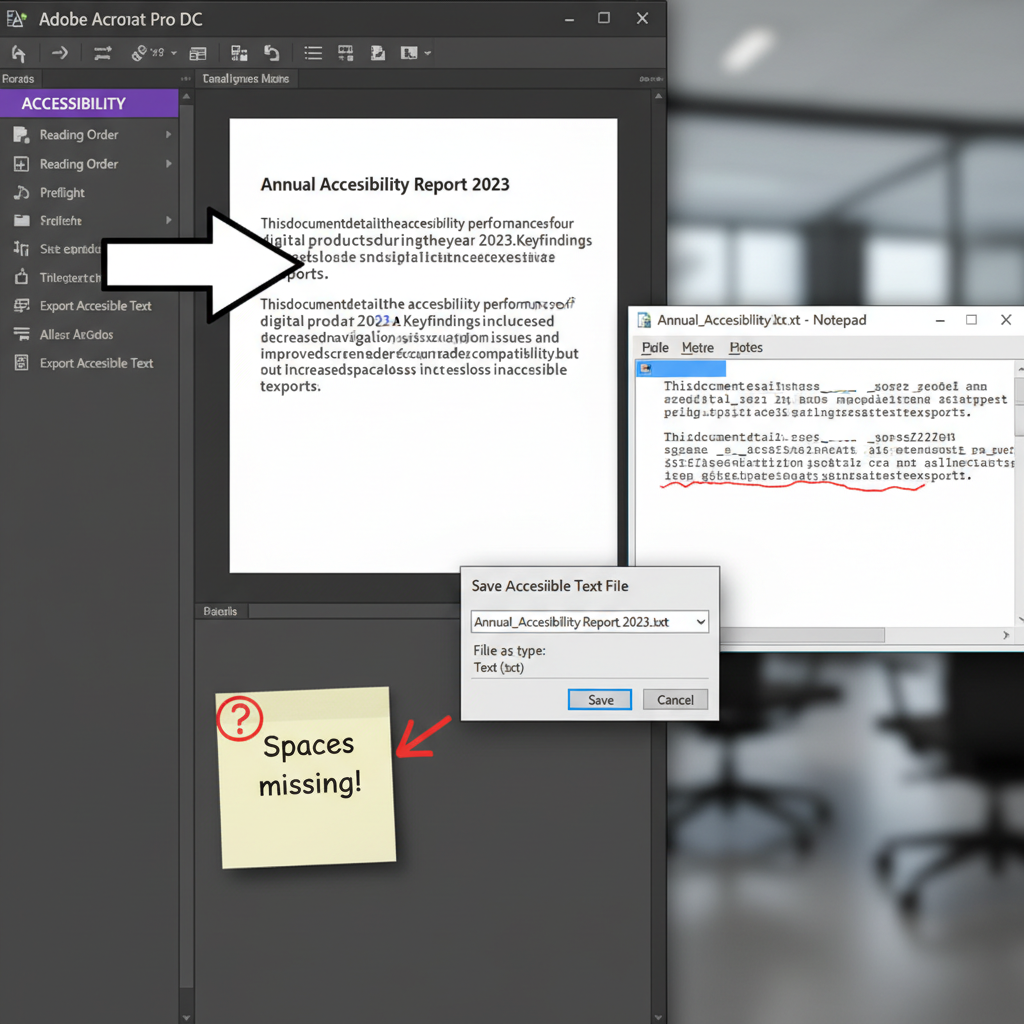
Users experience an issue where text exported from a tagged PDF using the accessible text option loses spaces between words, even though plain-text export and screen reader outputs appear correct.
- Product
- PDF Editors / Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Exporting accessible text from a tagged PDF document for accessibility compliance or content reuse.
- Observed behavior
- Spaces are omitted in the exported accessible text file, causing individual words to run together inappropriately.
Ensure you have access to a professional PDF editor with tag inspection capabilities, and ideally, have the original source document available in case the PDF needs to be regenerated.
Inspect and Correct the PDF Tag Tree
Identify and fix structural issues in the PDF tags that may cause space characters to drop during accessible text extraction.
Accessible text export relies heavily on the PDF's structure tree, reading order, and precise character positioning. If the application that generated the PDF created incorrect word-boundary information or improperly nested tags, the exported text might drop spaces.
Correcting the logical structure and reading order in the accessibility panel can often restore proper text extraction.
Launch your PDF editor, open the problematic tagged PDF, and navigate to the Accessibility or Document Structure panel.
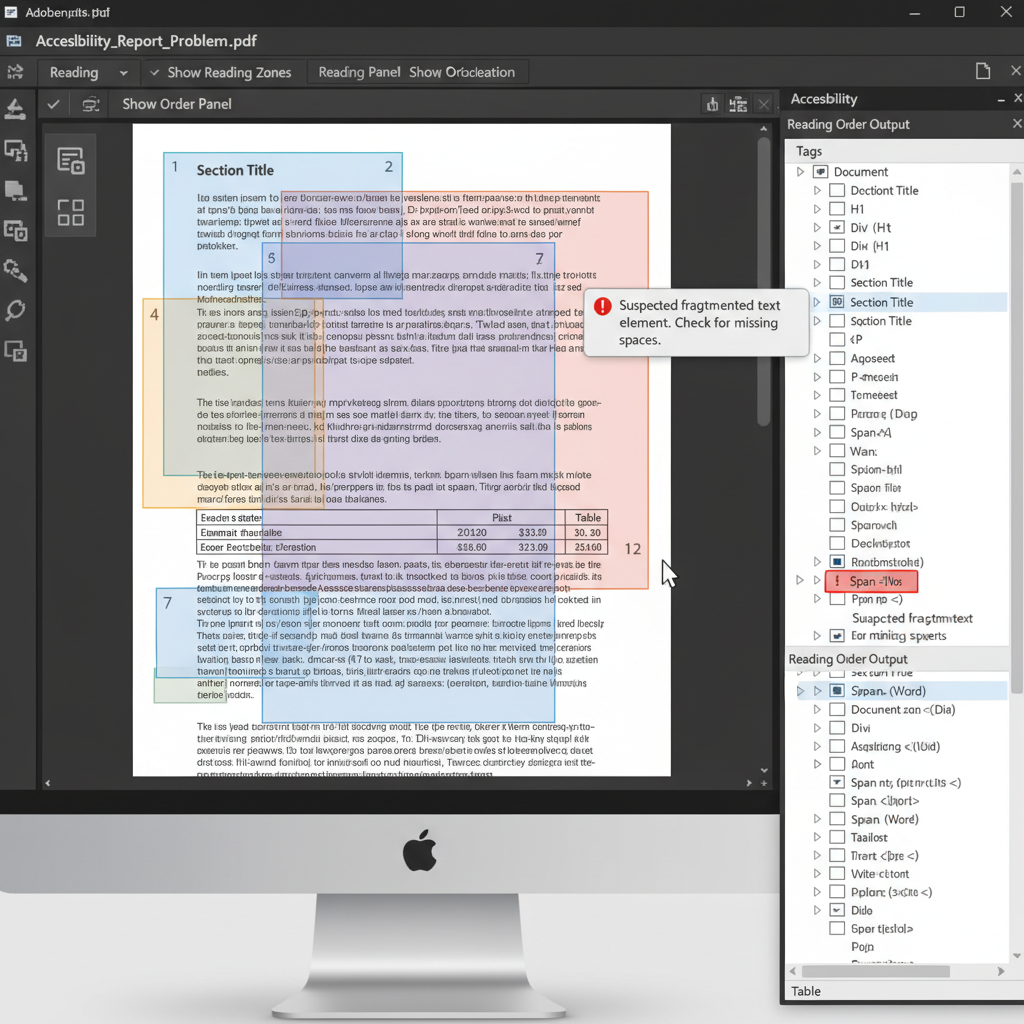
Select the Reading Order tool to ensure the text blocks are logically sequenced and that no bounding boxes are overlapping irregularly.
Open the Tags tree from the navigation pane. Verify that text elements are properly enclosed in standard paragraph or heading tags without unnecessary breaks or fragmented word spans.
Regenerate the Tagged PDF from the Source Application
Recreate the tagged PDF directly from the original source file to resolve underlying font encoding or structural glitches.
Extract Text from PDFs Flawlessly with WPS Office
Avoid missing space issues and complex tag tree debugging by using WPS Office's built-in PDF to Word and text extraction features. WPS PDF accurately recognizes character positioning, structural layouts, and formatting to ensure your exported text maintains its original word spacing.
- 1. Open PDF in WPS Office: Launch WPS Office and open your PDF document using the WPS PDF viewer.
- 2. Select the PDF to Word Tool: Navigate to the 'Tools' tab on the top ribbon and select 'PDF to Word' to initiate the conversion process.
- 3. Configure Export Settings: Choose your desired output format, such as .docx or .txt, and confirm the document language for optimal text recognition.
- 4. Convert and Edit: Click 'Start' to extract the text. The converted file will automatically open in WPS Writer with intact spacing, ready for modification.

Frequently Asked Questions
Why does plain text export keep spaces while accessible text export loses them?
Plain text export relies on a straightforward character extraction process that reads the basic text layer of the PDF. Accessible text export, however, relies heavily on the PDF's structural tree, reading order, and word-boundary data. If the tags or bounding boxes are flawed, the accessible export may fail to recognize the spaces.
Can font encoding cause missing spaces in PDF text exports?
Yes. If the original font lacks proper Unicode mapping or space character encoding, the PDF generator might rely on precise coordinate positioning instead of actual space characters. This often causes text extraction tools to misinterpret word boundaries and drop spaces.
What is the fastest way to fix a PDF tag tree to improve text extraction?
While you can use a professional PDF editor to manually inspect the Tags panel and adjust nested text blocks, recreating the PDF from the original source file (like Word or InDesign) with accessibility tags enabled is usually the fastest and most reliable way to resolve these structural issues.


