

How to Fix OCR Performance Issues for Large PDF Files
Question details
The user needs to perform Optical Character Recognition (OCR) on massive scanned PDFs containing over 1,000 pages but faces performance issues and software instability.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
- Attempting to run an OCR process on bulk-scanned PDF documents to make them searchable, while dealing with hardware and software limitations.
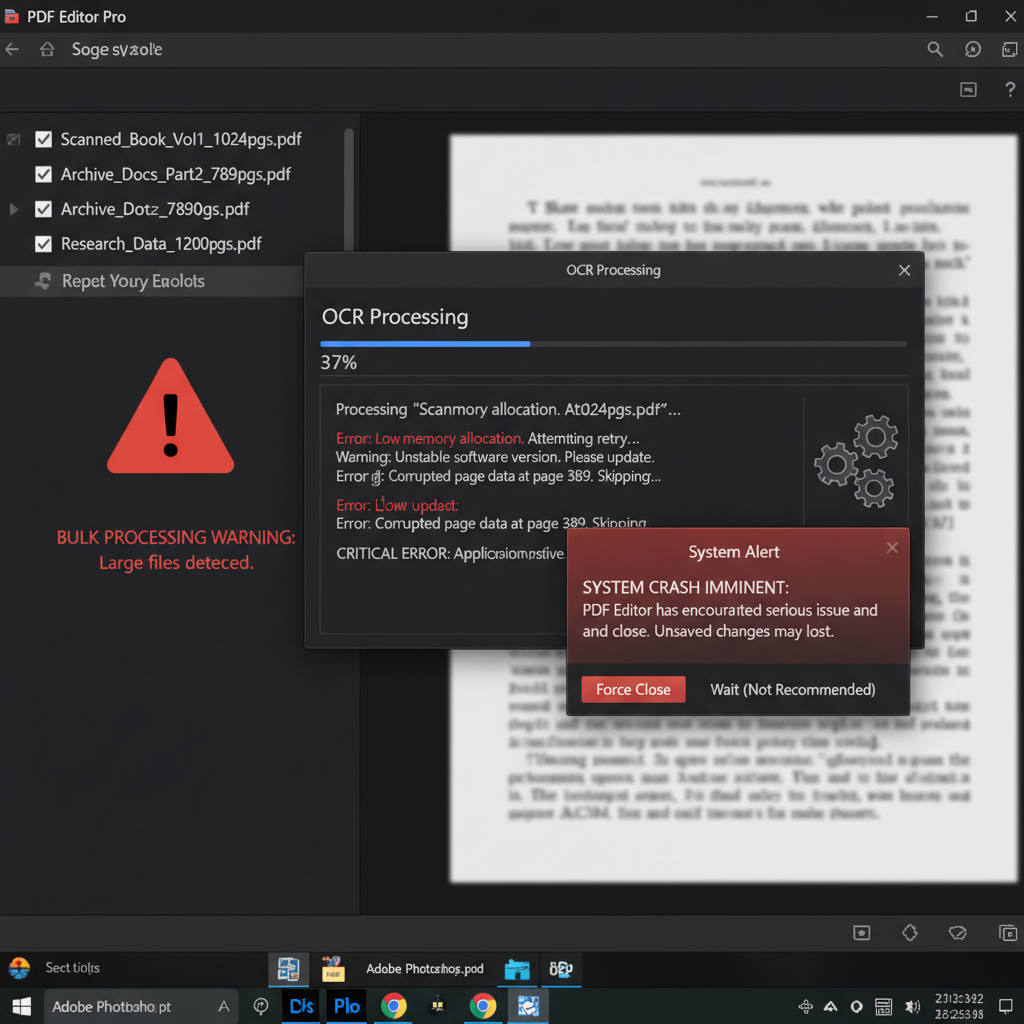
- Observed behavior
- Processing highly complex or large files causes unreliable OCR results, significant system slowdowns, and application freezing, especially with low scan resolutions or older software versions.
Ensure your computer is plugged in and has sufficient memory available, as OCR processing for large files is highly resource-intensive. Always back up your original massive PDF before splitting or converting it.
Split Large PDFs and Recombine After OCR
Breaking a massive document into smaller chunks prevents software crashes and improves OCR reliability.
Processing over 1,000 pages at once can overwhelm system memory and cause PDF editors to freeze. Splitting the document into smaller batches ensures smoother processing and protects against progress loss.
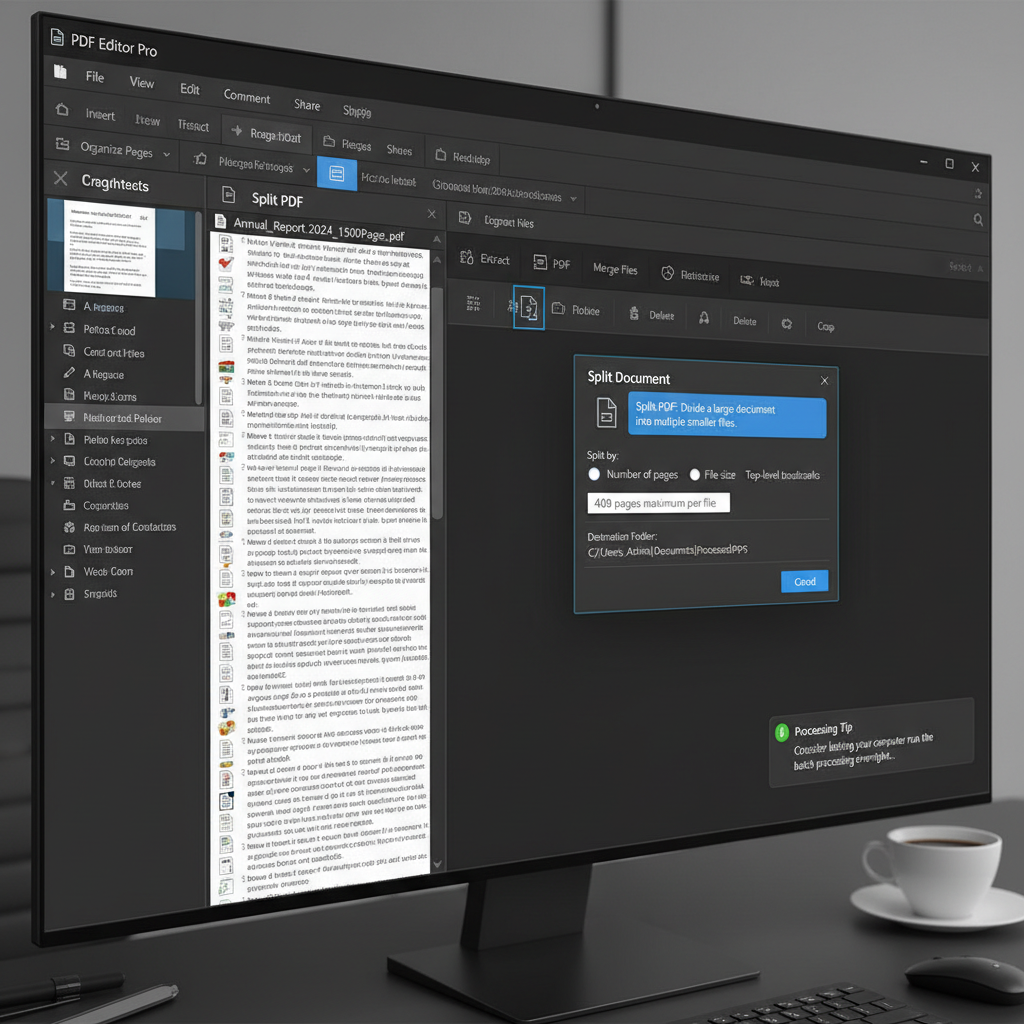
Launch your PDF editor, open the large document, and navigate to the 'Organize Pages' or 'Page' menu. Select the 'Split PDF' option.
Configure the tool to split the document into smaller files containing a maximum of 400 pages each, then save the split files to a dedicated folder.
Open each 400-page section individually and run the 'Recognize Text' or 'OCR' command.
Once all sections have been successfully processed, use the 'Combine Files' or 'Merge PDF' tool to reunite the sections into a single, fully searchable PDF.
Optimize Scan Resolution for Better Accuracy
Adjusting the initial scan resolution improves OCR accuracy without unnecessarily inflating the final file size.
Upgrade Software or Use Dedicated OCR Tools
Older software versions struggle with modern large-scale OCR tasks. Upgrading can bypass these legacy limitations.
Use WPS Office to OCR and Manage Large PDF Files
WPS Office provides robust PDF editing and OCR capabilities, allowing you to quickly extract text, split large documents into manageable sizes, and optimize your files with ease.
- 1. Open your Document: Launch WPS Office and open your massive scanned PDF document.
- 2. Split the PDF: Navigate to the 'Page' tab and select 'Split PDF' to divide the document into sections of 400 pages for stable processing.
- 3. Run OCR: Go to the 'Tools' tab and click on 'OCR' to accurately recognize and extract text from your scanned pages.
- 4. Save or Export: Save the optimized document as a searchable PDF or export it directly to a Microsoft Word format for further editing.
Frequently Asked Questions
What is the best DPI/PPI for scanning documents for OCR?
For optimal OCR accuracy and manageable file sizes, a scanning resolution between 300 and 400 PPI (Pixels Per Inch) is highly recommended. Lower resolutions cause misinterpretation of characters, while higher resolutions slow down processing without noticeable quality gains.
Why does my computer freeze when running OCR on a large PDF?
OCR is a highly resource-intensive computational process. Processing hundreds or thousands of pages simultaneously can consume all your available RAM and max out your CPU, causing the system or the application to freeze.
How many pages should I include in a single OCR batch?
To ensure stable performance and prevent software crashes, it is advisable to split large documents into smaller sections of approximately 400 pages each before running the OCR process.
Does higher scan resolution significantly increase the final PDF file size?
Interestingly, once the OCR process is complete and the file is optimized by modern PDF editing software, the final document size does not differ drastically whether you originally scanned the pages at 100, 300, or 600 ppi.


