

How to Prevent Adobe Acrobat Pro from Running OCR Twice

Question details
Users need to stop Adobe Acrobat 2017 Pro from running Optical Character Recognition (OCR) multiple times on the same PDF file.
- Product
- Adobe Acrobat 2017 Pro
- Device & OS
- Windows 10
- Scenario
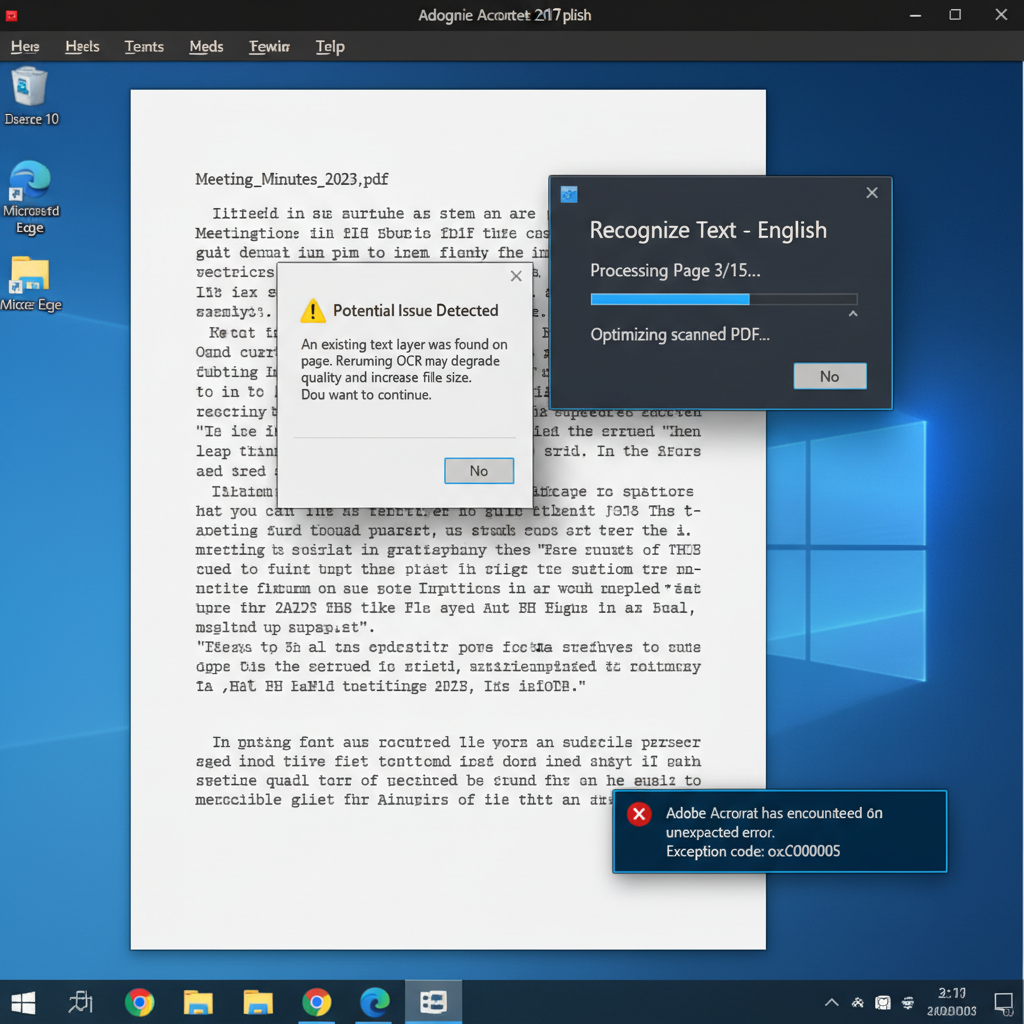
- User is processing PDF files that already contain an OCR layer.
- Observed behavior
- Acrobat fails to recognize the existing text layer, reruns the OCR process, creates a shadow effect on the text, increases processing time, and sometimes crashes with exception code 0xc0000005.
Verify whether your PDF already contains selectable text by attempting to highlight words in the document before initiating any batch OCR processes.
Optimize the PDF and Repair Adobe Acrobat
Use this method to resolve text layer recognition issues and fix Acrobat crashes associated with exception 0xc0000005.
This behavior typically occurs when Acrobat's OCR engine fails to recognize the existing text layer due to formatting issues or corrupted application files.
By re-optimizing the PDF and repairing the software, you can restore normal OCR functionality.
Open your PDF, select the text tool, and attempt to highlight the text. If it is selectable, the document is already OCR-processed and should not be processed again.
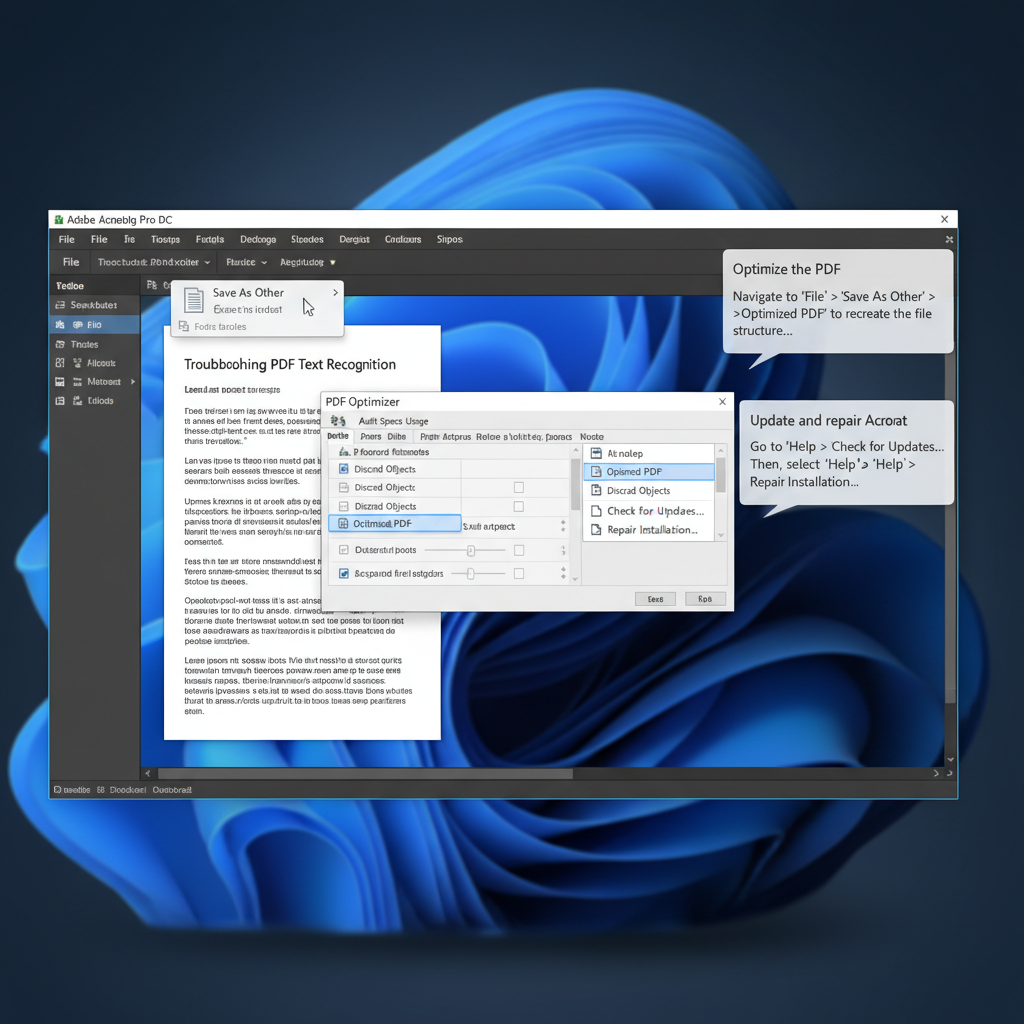
Navigate to 'File' > 'Save As Other' > 'Optimized PDF' to recreate the file structure. This can help clear hidden corrupted layers before attempting to run OCR again.
Go to 'Help' > 'Check for Updates' to install the latest patches. Then, select 'Help' > 'Repair Installation' to fix missing or corrupted application files.
If Acrobat continues to crash with exception code 0xc0000005, collect the Windows crash dump files and contact Adobe Support for advanced troubleshooting.
Extract and Recognize Text Seamlessly with WPS PDF
Avoid application crashes and redundant processing by using WPS PDF. Its intelligent OCR engine accurately identifies existing text layers and converts scanned documents to editable formats quickly, fully compatible with standard PDF files.
- 1. Open WPS PDF: Launch WPS Office and open your scanned or standard PDF document.
- 2. Access OCR Features: Navigate to the 'Tools' tab on the top ribbon and select 'OCR' or 'Picture to Text'.
- 3. Select Output Options: Choose whether you want to extract the text, convert it to an editable Word document, or create a searchable PDF.
- 4. Start Recognition: Click 'Convert' or 'Extract'. WPS PDF will process the document quickly without creating overlapping shadow text.
Frequently Asked Questions
Why does Adobe Acrobat create a shadow effect when running OCR?
A shadow effect occurs when Acrobat fails to detect an existing invisible OCR text layer and creates a second text layer slightly offset from the original text, resulting in overlapping or blurred letters.
What does Acrobat exception code 0xc0000005 mean?
Exception code 0xc0000005 is an access violation error in Windows. In Acrobat, it often happens when the software attempts to read or write to an invalid memory location during intensive processing tasks like OCR on large documents.
How can I easily check if a PDF has already been OCR processed?
Open the PDF document, select the Text Selection tool, and try to highlight the text on the page. If you can select individual letters or words and copy them, the file already contains an OCR text layer and does not need processing.
Can I undo an OCR process in Adobe Acrobat?
Acrobat does not have a dedicated 'Undo OCR' button once the file is saved. You can use the 'Sanitize Document' tool to remove hidden text layers, or you will need to revert to the original scanned image file.


