

How to Prevent Cropped Edges When Scanning Documents in Adobe Acrobat

Question details
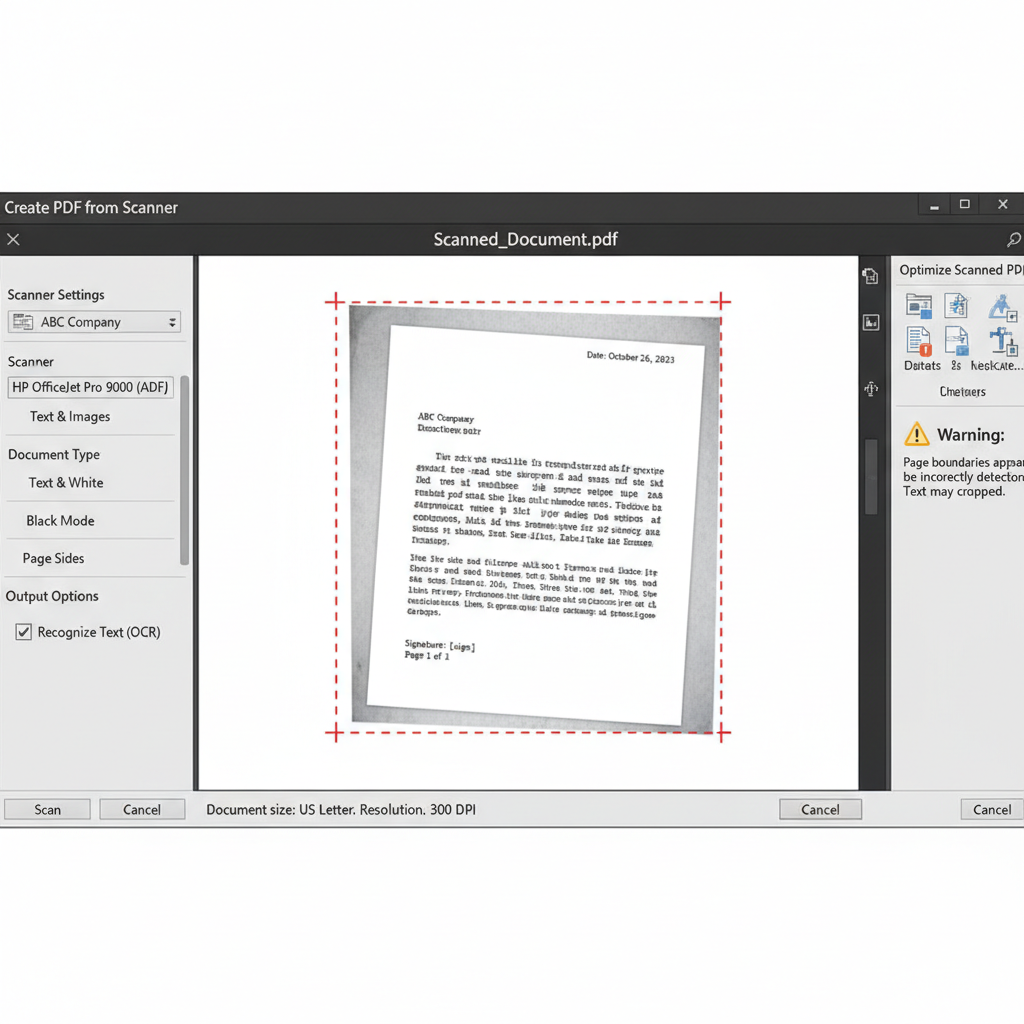
The user is experiencing an issue where text is cut off at the edges when scanning documents through an automatic feeder directly into Acrobat.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Scanning multiple physical documents via an automatic document feeder (ADF) to generate an OCR-searchable PDF.
- Observed behavior
- The resulting PDF contains cropped edges and missing text around the margins because the Acrobat scanning interface misinterprets the page boundaries.
Ensure your scanner's native drivers and scanning software (such as Fujitsu Scan) are properly installed and updated on your computer.
Use Native Scanner Software and Combine Files in Acrobat
Bypass Acrobat's scanning interface to let the native scanner driver handle page edges accurately, then merge the images.
Acrobat's built-in scanning interface can sometimes miscalculate the edges of documents fed through an automatic document feeder (ADF). Using the scanner's native software ensures accurate edge detection.
To preserve maximum quality for text recognition, save the scanned files in a high-quality image format like TIFF before converting them to PDF.
Open your scanner's native application (e.g., Fujitsu Scan) and scan your documents. Save the output as TIFF files in a dedicated folder.
Ensure your scanning resolution is set to at least 300 ppi. For difficult or faded documents, use 600 ppi for optimal Optical Character Recognition (OCR) results.
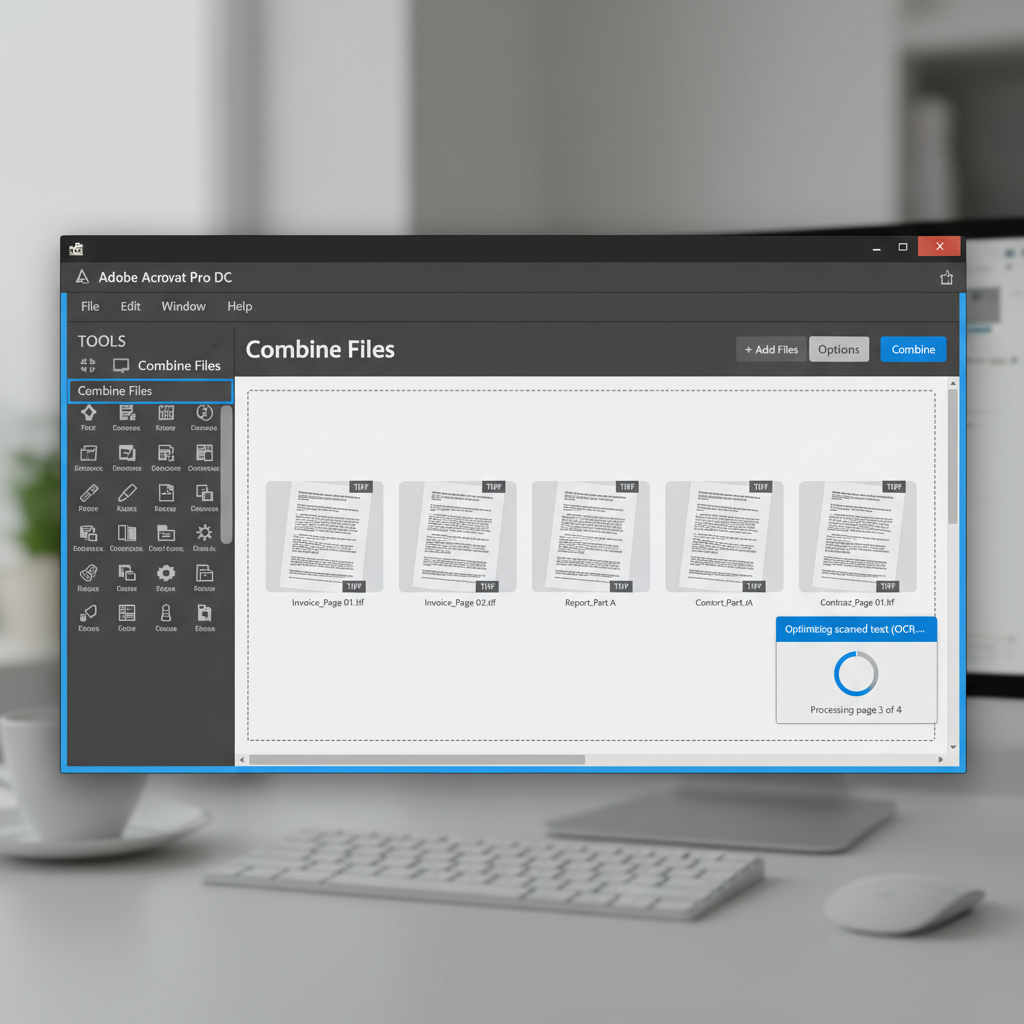
Launch Adobe Acrobat, navigate to the 'Tools' menu, and select 'Combine Files'.
Add the TIFF images you saved earlier. As Acrobat combines them into a single PDF, it will automatically run OCR to make the text searchable.
Combine and Convert Scans to PDF with WPS Office
WPS Office provides a highly efficient and lightweight PDF editor. You can easily combine multiple scanned images into a single PDF document and extract text using its built-in OCR feature, without draining your computer's resources.
- 1. Open WPS PDF: Launch WPS Office and switch to the PDF tab.
- 2. Create PDF from Images: Click on 'Picture to PDF' and select your scanned TIFF or JPG files from your folder.
- 3. Combine and Save: Ensure 'Merge into one PDF' is checked, then click 'Convert' to generate your combined file.
- 4. Apply OCR: Open the newly created PDF, navigate to the 'Tools' tab, and click 'OCR' to recognize and edit the text.

Frequently Asked Questions
Why does Adobe Acrobat crop the edges of my scanned documents?
Acrobat's built-in scanning interface can struggle to perfectly detect page boundaries when documents are fed through certain Automatic Document Feeders (ADFs). The scanner's native driver usually has better calibration for accurate edge detection.
What is the best resolution for scanning documents for OCR?
It is highly recommended to scan documents at a minimum of 300 ppi for reliable OCR performance. For documents with small text, low contrast, or faded ink, increasing the resolution to 600 ppi will yield significantly better results.
Can I use JPEG instead of TIFF for scanning documents?
While JPEG is supported, TIFF is highly recommended for scanning text documents because it uses lossless compression. This prevents compression artifacts around text characters, resulting in a cleaner image and much more accurate OCR text recognition.


