

How to Process Large PDF OCR Jobs in Acrobat Pro DC

Question details
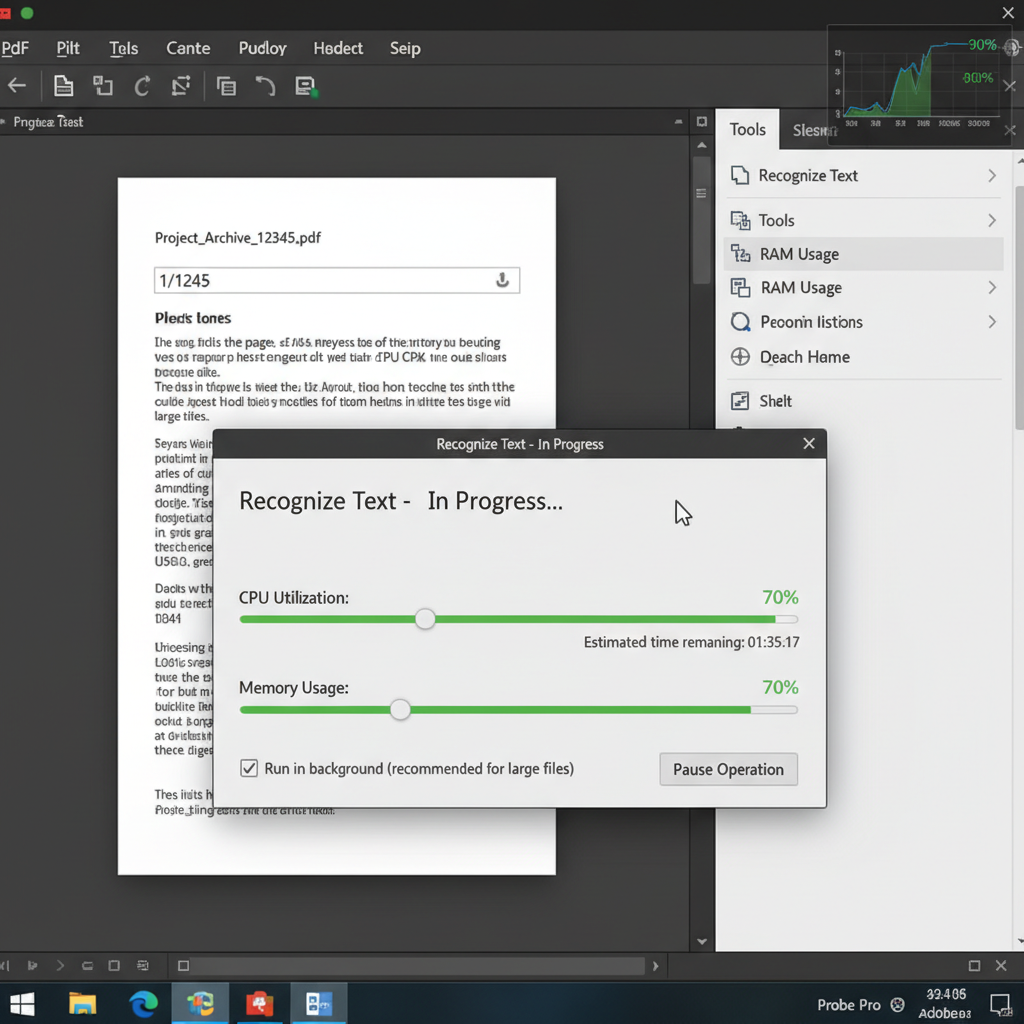
The user needs to perform OCR on massive PDF files (over 1,000 pages) in Adobe Acrobat Pro DC without freezing the workstation or consuming all system resources.
- Product
- Adobe Acrobat Pro DC
- Device & OS
- not provided
- Scenario
- Running OCR on large-scale PDF documents requiring significant CPU and memory overhead.
- Observed behavior
- Large OCR operations consume substantial workstation resources, making the computer unusable for other tasks while the job is running.
Ensure your computer has sufficient free RAM and storage space before initiating massive OCR tasks, and close any unnecessary background applications to maximize CPU availability.
Process OCR Jobs in Smaller Batches and Run Unattended
Splitting massive PDFs into smaller batches and scheduling them during off-hours prevents workstation lockups and manages memory efficiently.
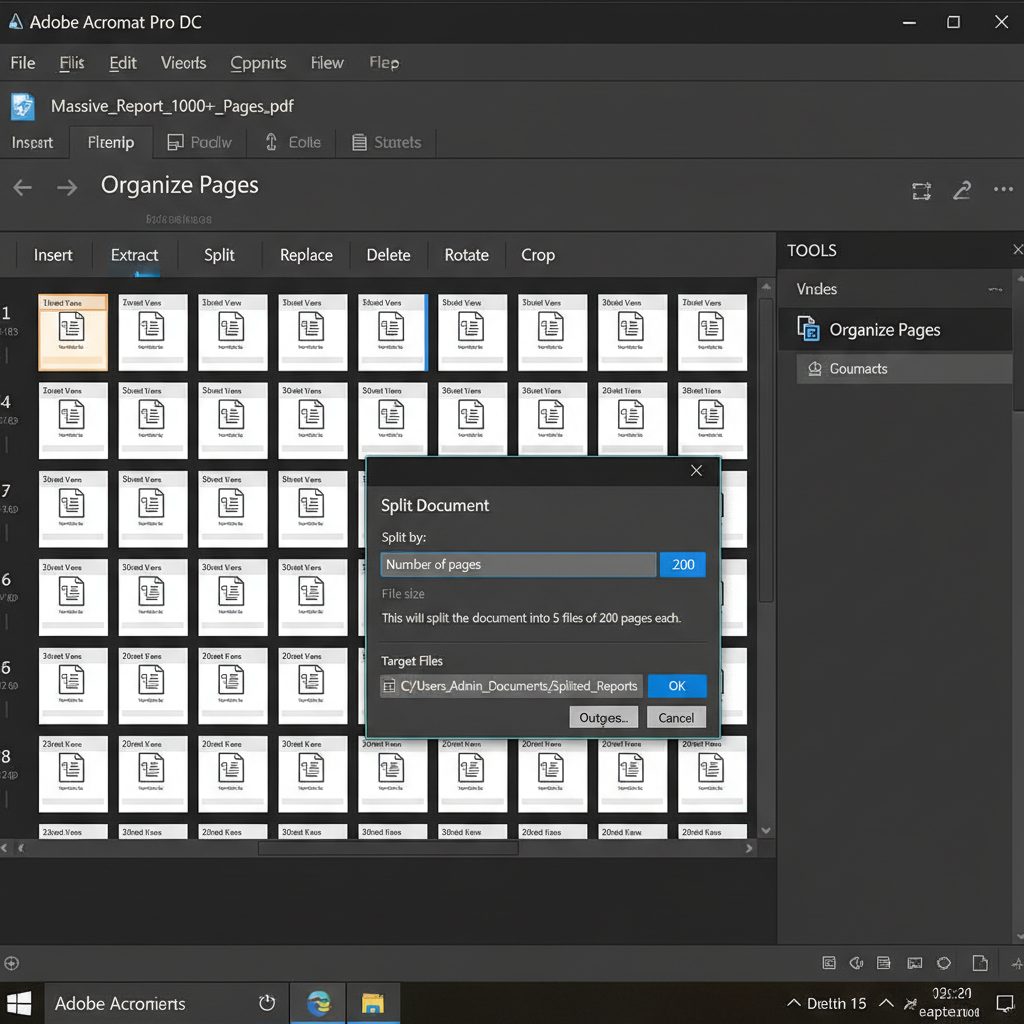
Processing a single file with more than 1,000 pages strains the memory limits of Acrobat and your operating system. Breaking the file into manageable chunks keeps resource consumption within safe thresholds.
In Acrobat Pro DC, use the 'Organize Pages' tool to extract or split the 1,000+ page document into smaller files (e.g., 200 pages each).
Schedule or manually start the OCR processing on these smaller batches at the end of your workday or during a lunch break so your workstation isn't tied up.
Once all batches are processed, use the 'Combine Files' tool in Acrobat to merge the searchable PDF segments back into a single document.
Optimize Initial Scan Quality and Resolution
Balancing scan resolution reduces the file size and the processing load placed on Acrobat Pro DC during the OCR process.
Automate OCR with the Action Wizard
Use Acrobat's Action Wizard to queue up multiple PDF files for OCR processing automatically, saving manual effort.
Try WPS Office for Lightweight PDF Editing and OCR
If heavy PDF processors are slowing down your workstation, WPS Office provides a lightweight, resource-friendly alternative. With built-in PDF tools, you can seamlessly read, edit, and perform OCR on documents without draining your system's memory.
- 1. Open WPS PDF: Download and launch WPS Office, then open your scanned PDF document within the WPS PDF module.
- 2. Access the OCR tool: Navigate to the 'Tools' tab and click on the 'OCR' button to initiate text recognition.
- 3. Extract or convert text: Choose whether to extract the text to a Word document or simply make the current PDF searchable, then let the lightweight engine process your file.
Frequently Asked Questions
Why does Acrobat freeze when performing OCR on a 1000-page PDF?
Acrobat requires significant RAM and CPU to analyze text patterns in high-resolution images. Massive files can exceed available system memory, leading to application freezes, crashes, or unresponsiveness.
What is the best scan resolution for PDF OCR?
A resolution of 300 DPI (dots per inch) is highly recommended. It provides clear enough text for accurate character recognition without creating an excessively large file that slows down processing times.
Can I use my computer for other tasks while Acrobat runs OCR?
It is not recommended when processing very large files. OCR is an extremely CPU-intensive task, and running other heavy applications simultaneously may lead to poor system performance or OCR failure.
Is there a way to extract only specific pages for OCR in Acrobat?
Yes, you can use the 'Extract' tool located in the 'Organize Pages' menu to pull out only the specific pages containing text that needs recognition, which drastically saves processing time and system resources.


