

How to Remove Hidden PDF Information Without Damaging Text

Question details
The user needs to remove hidden information and sensitive metadata, such as employee names, from a PDF document without causing the visible text to become choppy or structurally damaged.
- Product
- Adobe Acrobat and PDF Editors
- Device & OS
- not provided
- Scenario
- Sanitizing a PDF document for public distribution by removing hidden background data and sensitive metadata.
- Observed behavior
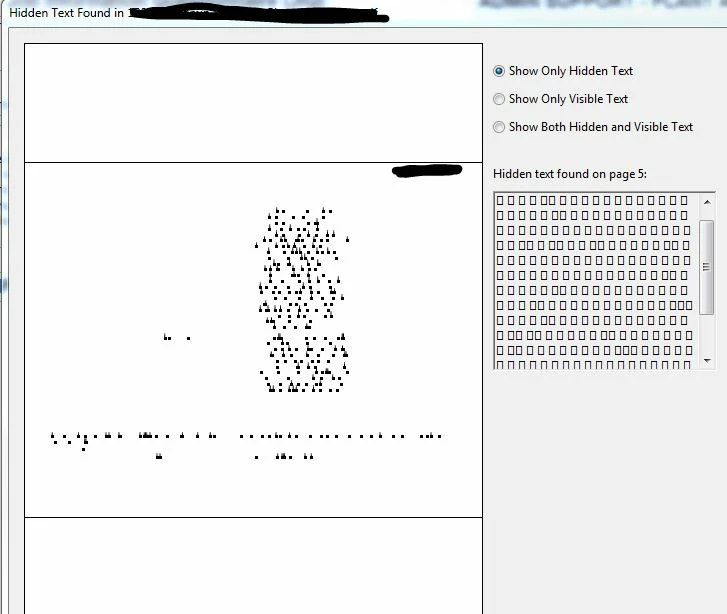
- Automated PDF hidden information removal tools incorrectly identify formatting spaces or visual elements as metadata, resulting in disjointed, choppy, or damaged text after cleanup.
Before sanitizing your PDF, identify exactly which hidden elements (such as metadata, embedded index data, or overlapping text) need to be removed, and verify if the source document was created using optical character recognition (OCR), which makes it more susceptible to text fragmentation.
Manually Inspect and Sanitize PDF Content Structure
Carefully review the PDF's underlying structure and selectively remove hidden information to ensure text spaces and visual formatting are not mistakenly deleted.
Batch cleanup tools often cannot differentiate between true hidden metadata and structural layout elements like kerning spaces. By manually inspecting the targeted redactions, you can prevent structural damage to the document's text.
Duplicate your original PDF document and open the copy in your preferred PDF editor, such as Adobe Acrobat, to ensure your original data remains intact during testing.
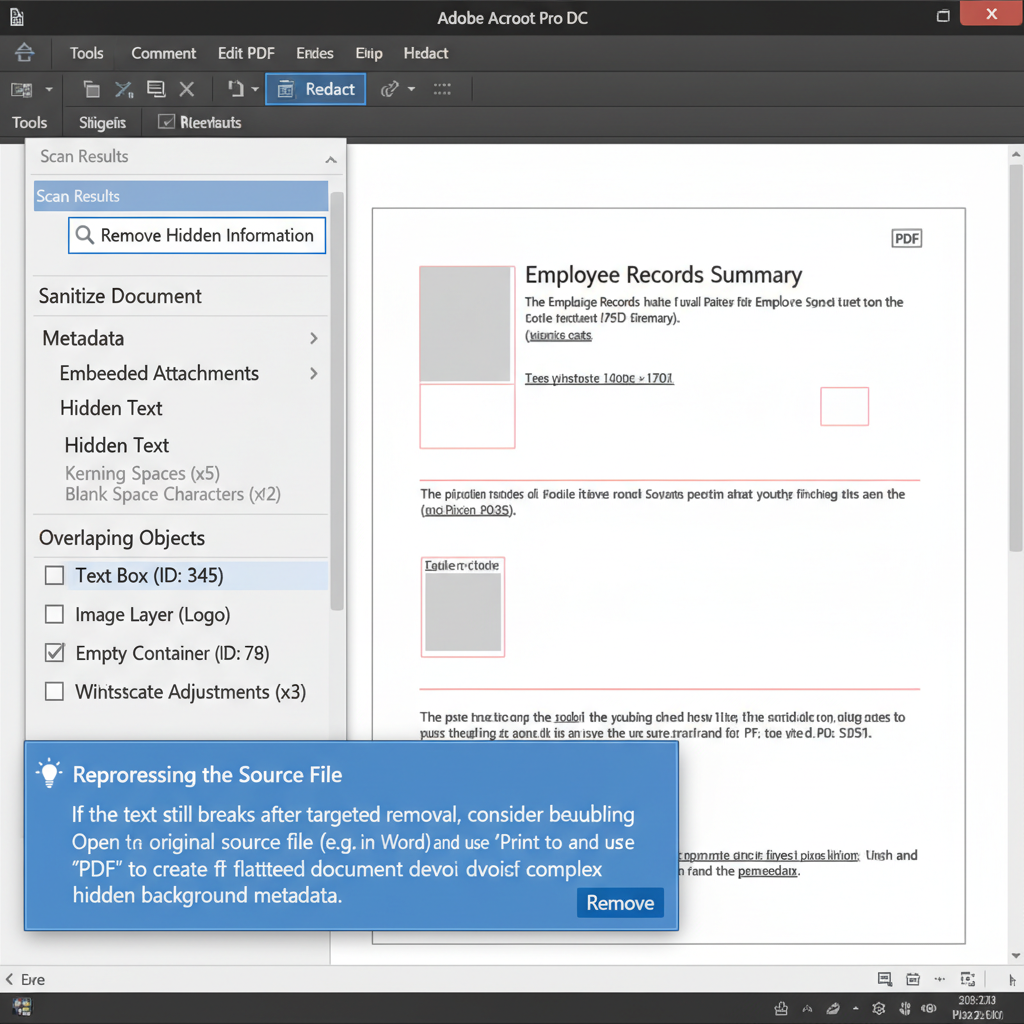
Navigate to the 'Tools' menu, select 'Redact', and click on 'Remove Hidden Information'. Wait for the software to scan the document for metadata, hidden text, and attachments.
Look at the left-hand panel displaying the discovered hidden elements. Expand the 'Hidden Text' and 'Overlapping Objects' categories to preview exactly what the tool plans to delete.
Uncheck any items that seem linked to visual formatting or spacing rather than the actual sensitive employee names you are trying to hide.
Click the 'Remove' button. Once the process is finished, scroll through the document to confirm the text layout has not become choppy or disjointed.
Safely Redact and Protect PDFs with WPS PDF
WPS Office provides precise PDF redaction and document security tools that allow you to permanently obscure sensitive information without corrupting your document's text layout or formatting.
- 1. Open the PDF in WPS Office: Launch WPS Office and open your PDF document containing the sensitive or hidden information.
- 2. Navigate to the Protect Tab: Click on the 'Protect' tab located on the top ribbon menu to access the security features.
- 3. Select the Redact Feature: Click on the 'Redact' button. Use your cursor to carefully highlight only the specific employee names or sensitive data you wish to remove.
- 4. Apply Redactions Permanently: Click 'Apply Redactions' to safely and permanently scrub the selected information from the document without affecting the surrounding text formatting.
Frequently Asked Questions
Why does my PDF text look choppy after removing hidden information?
This happens when automated document sanitization tools mistakenly identify structural text spaces, kerning elements, or visual formatting components as hidden metadata. Deleting these structural elements causes the remaining text to lose its proper spacing and layout.
Can I recover damaged text after saving a sanitized PDF?
No. Once hidden information is permanently removed and the PDF is saved (especially if saved over the original file), the lost structural data cannot be recovered. You must always apply sanitization tools to a separate copy of your original file.
What is the safest way to remove sensitive data without altering the PDF layout?
The safest method is to use targeted manual redaction tools to specifically obscure sensitive text rather than using batch metadata removal tools. Alternatively, you can recreate the PDF from the original source document without including the sensitive data.
Does WPS Office support removing sensitive information from PDFs?
Yes, WPS PDF includes robust document protection and redaction features. You can selectively obscure and remove sensitive content safely, ensuring the rest of the document's structure and formatting remains completely intact.


