

How to Split PDF Pages into Separate Files Based on Text

Question details
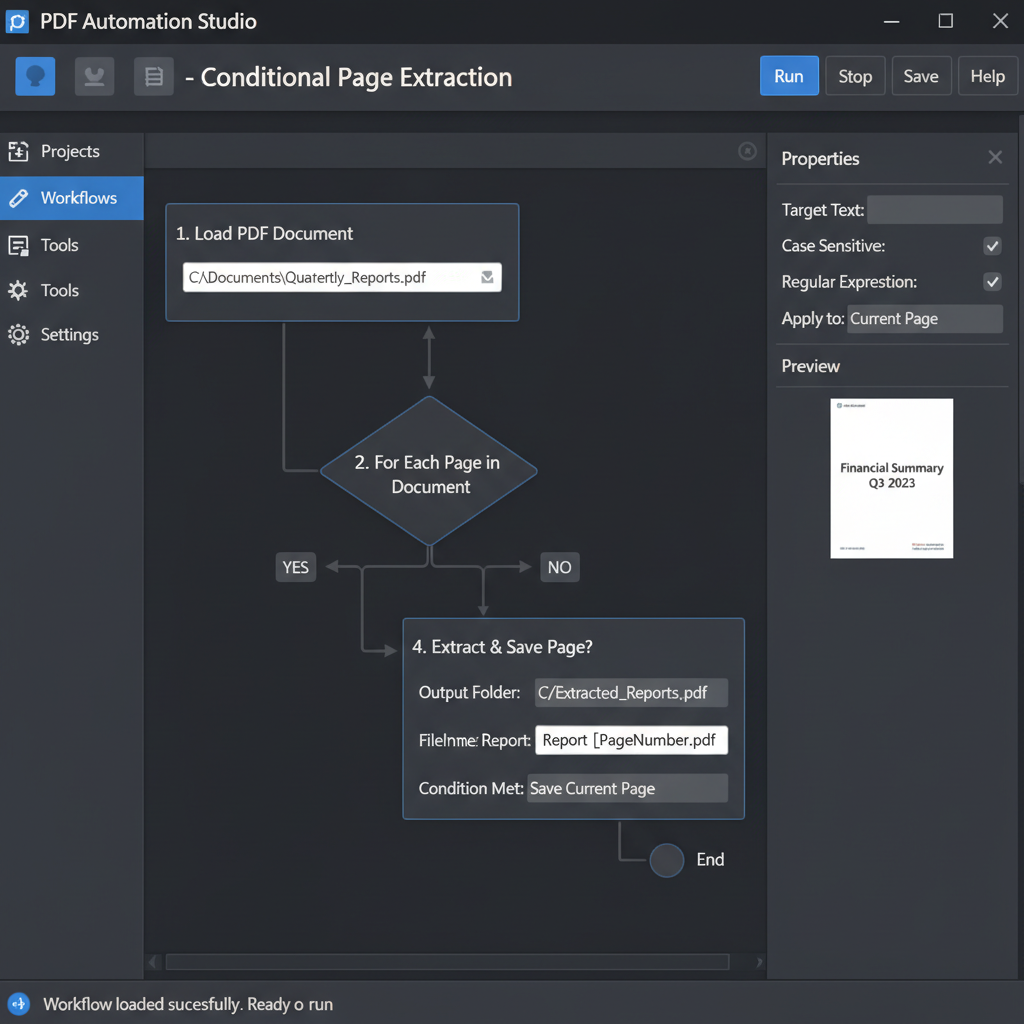
The user needs to separate a PDF document into individual files conditionally based on the presence of specific text within those pages.
- Product
- PDF Editing Software
- Device & OS
- not provided
- Scenario
- Automating the extraction and saving of specific PDF pages when predefined target text is found on them.
- Observed behavior
- Users often attempt to use Microsoft VBA to accomplish this, but VBA alone cannot parse PDF text natively, requiring instead a dedicated PDF script or automation tool.
Before proceeding, ensure you have a PDF editor that supports advanced scripting (such as Adobe Acrobat Pro) or a dedicated coding environment, as standard VBA macros cannot natively read internal PDF text.
Use Acrobat JavaScript to Extract Pages
Leverage Adobe Acrobat's built-in JavaScript engine to search for text and extract matching pages automatically.
Microsoft VBA cannot directly interact with the text elements inside a PDF document. Instead, Adobe Acrobat provides a specialized JavaScript API that allows you to iterate through pages, extract the text content, check for specific keywords, and save those matching pages as separate PDF files.
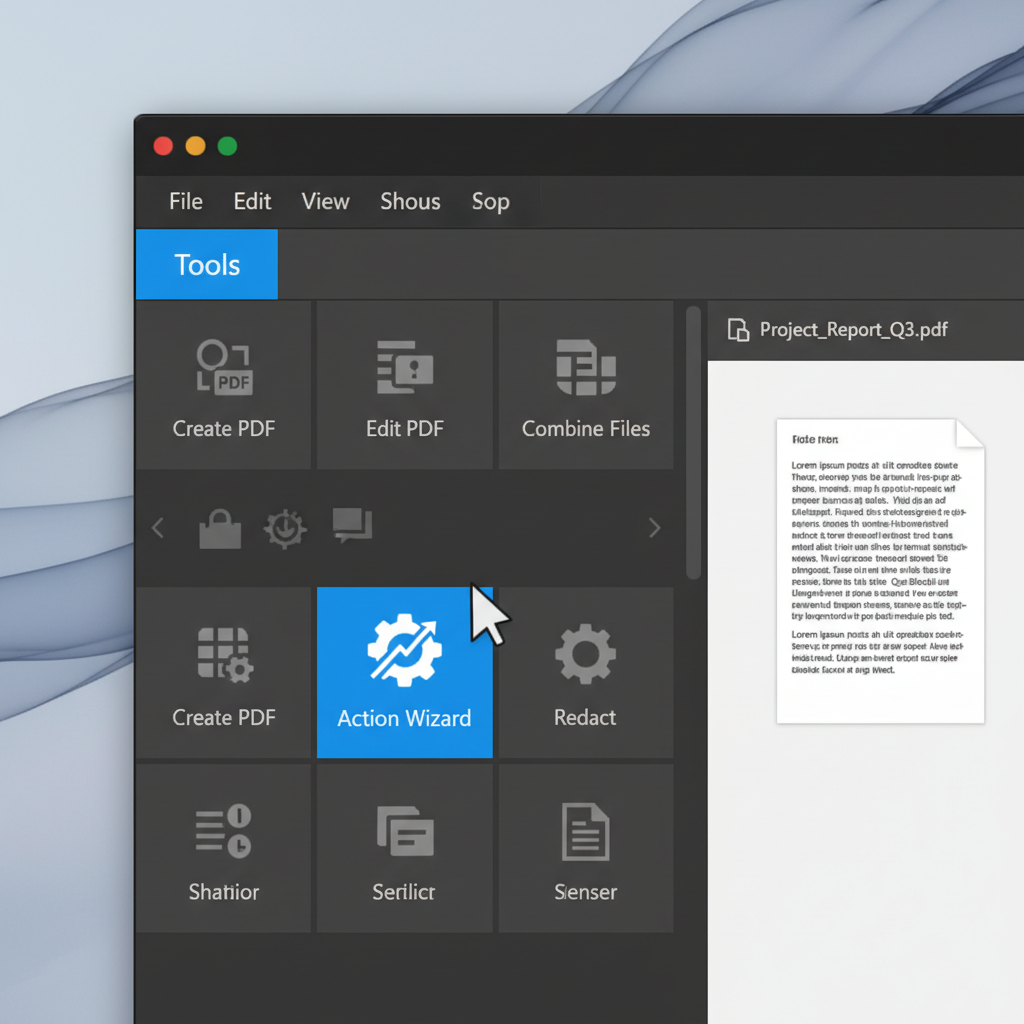
Launch Adobe Acrobat Pro, navigate to the 'Tools' tab, and select 'Action Wizard'.
Click on 'New Custom Command' in the toolbar and select 'Execute JavaScript' from the available action options.
Enter a JavaScript code snippet that loops through 'this.numPages', uses 'this.getPageNumWords()' to find your target text on each page, and triggers 'this.extractPages()' when a match is found.
Save the custom command and run it on your target PDF document to automatically split and save the required pages into your designated output folder.
Automate with Python and PyPDF2
Write a lightweight Python script to programmatically search and split PDFs if you do not have an Adobe Acrobat Pro subscription.
Easily Extract and Split PDF Pages in WPS Office
While scripting is required for fully automated text-based extraction, WPS Office provides an intuitive and highly efficient PDF editor that allows you to quickly search for content and split pages into separate files without any coding knowledge.
- 1. Open your PDF in WPS Office: Launch WPS Office and open the target PDF document you wish to split.
- 2. Locate Target Pages: Press 'Ctrl + F' to open the search bar, type in your specific text, and note down the page numbers where the text appears.
- 3. Access Page Extraction: Navigate to the 'Page' tab on the top ribbon menu and click on the 'Extract Page' tool.
- 4. Split and Save Files: Select 'Custom Extraction', enter the page numbers you noted, check the option to extract pages as separate files, and click 'Extract'.

Frequently Asked Questions
Can I use Microsoft Excel VBA to split a PDF based on text?
Standard Excel VBA cannot natively read or manipulate the internal text structure of a PDF file. To achieve this via VBA, you must link it with a third-party API (like Adobe Acrobat's API) or command-line PDF processing tools.
Is there a way to split PDFs by page ranges instead of text content?
Yes. Most modern PDF editors, including WPS Office, feature a dedicated 'Split PDF' tool where you can simply input the desired page ranges (e.g., 1-5, 8, 11-12) to instantly divide the document into smaller files.
Are there free tools available to automatically split PDFs by text?
If you have basic programming knowledge, open-source Python libraries such as PyPDF2 and pdfplumber are excellent free tools for writing scripts that can automatically search for text and split PDF pages accordingly.


