

How to Stop Adobe Acrobat from Automatically Converting Scanned PDFs to Text

Question details
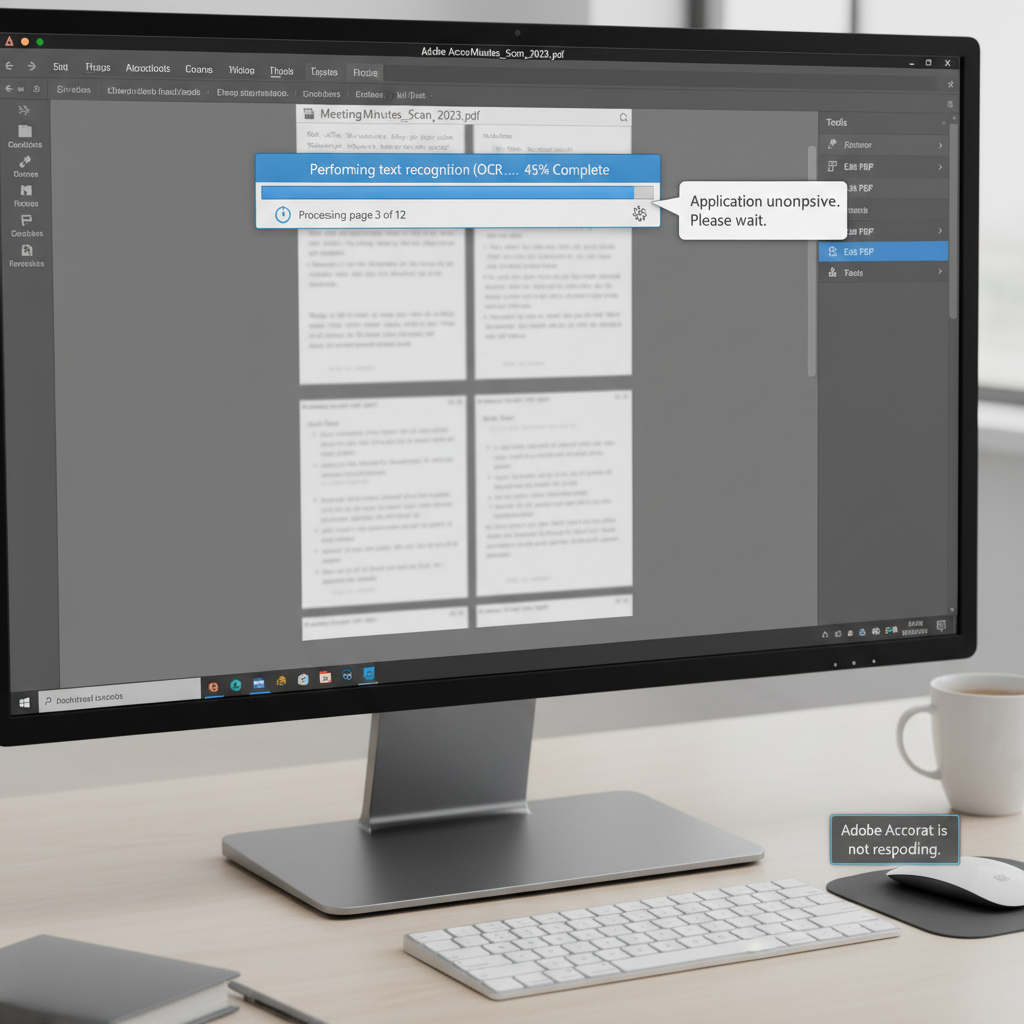
Users need to stop Adobe Acrobat from automatically performing text recognition (OCR) on scanned documents to avoid slow performance and freezing.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Opening or attempting to edit multi-page scanned PDF documents.
- Observed behavior
- Acrobat automatically initiates Optical Character Recognition (OCR) to convert scanned images into editable text, which causes significant processing delays and locks up the application for several minutes.
Before adjusting your Adobe Acrobat settings, ensure you save a backup copy of your original scanned PDF document to prevent accidental data loss or unwanted permanent text conversions.
Use the Standard Viewing Workflow Instead of the Edit Tool
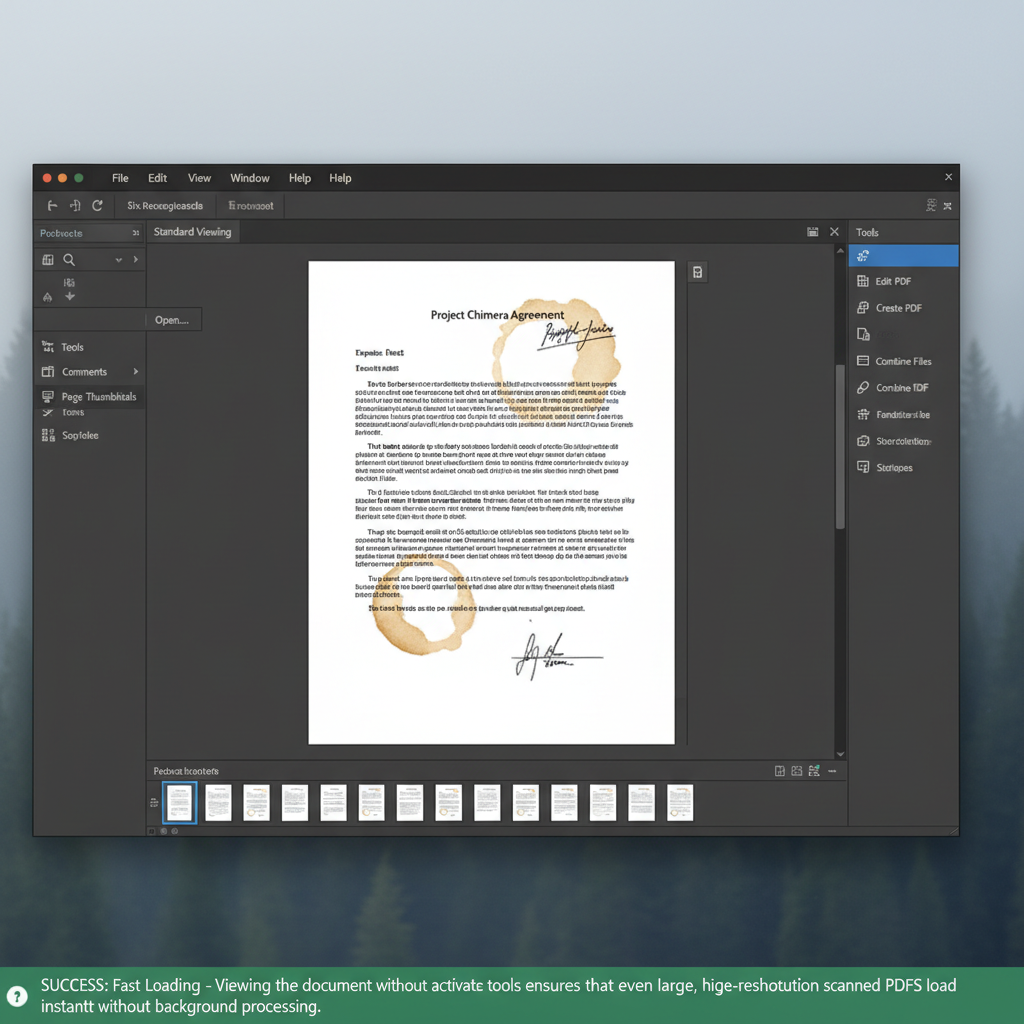
Adobe Acrobat triggers automatic OCR primarily when a scanned document is opened using the Edit PDF tool. Simply opening the file in standard viewing mode prevents this background process.
The most common reason Acrobat attempts to convert a scanned document to text is that the 'Edit PDF' panel is active. By changing how you open and view the document, you can bypass the automatic conversion entirely.
Launch Adobe Acrobat, go to File > Open, and select your multi-page scanned PDF document.
Do not click on 'Edit PDF' in the right-hand tools pane. If the right pane is open by default, collapse it to ensure the editing tools do not trigger.
Navigate through your document using the standard scrolling or page thumbnail tools. As long as the editing tools remain inactive, the automatic text recognition will not start.
Disable Automatic OCR in Acrobat Settings
Adjust the editing preferences within Adobe Acrobat to explicitly prevent the application from making scanned PDFs editable automatically.
Open Scanned PDFs Instantly with WPS PDF
Avoid the frustration of forced automatic text recognition. WPS Office includes a fast, lightweight PDF tool that lets you view, annotate, and manage large scanned documents without unexpected delays. You can trigger OCR only when you actually need it.
- 1. Download WPS Office: Download and install WPS Office Free from the official website.
- 2. Open WPS PDF: Launch the application and select the 'PDF' module from the home screen.
- 3. Open Your Document: Click 'Open' and select your multi-page scanned PDF document. It will load instantly in viewing mode.
- 4. Run OCR Manually (Optional): If you eventually need to extract or edit the text, navigate to the 'Tools' tab and click 'OCR' to initiate the process on your own terms.

Frequently Asked Questions
Why does Acrobat automatically convert my scanned PDFs to text?
Acrobat attempts to make scanned documents editable and searchable by default when you use the Edit PDF tool. This automatic Optical Character Recognition (OCR) process allows you to interact with the text but can cause significant delays on larger multi-page files.
Can I manually trigger OCR only when I need it?
Yes, you can manually run text recognition. Instead of using the Edit PDF tool, go to the Tools menu, select 'Scan & OCR', and choose 'Recognize Text' to selectively apply OCR to specific pages or documents without freezing your application.
Will turning off automatic OCR reduce my PDF file size?
Disabling automatic OCR prevents Acrobat from embedding recognized text data into your document. While this saves processing time and may prevent the file from growing larger, it doesn't compress or reduce the file size of the original high-resolution scanned images.
Why does my Acrobat freeze when opening a scanned document?
If the 'Edit PDF' tool is active or set as the default view, Acrobat immediately begins scanning the document for text to convert. On documents with dozens or hundreds of scanned pages, this intensive background process uses significant system resources, causing the application to temporarily freeze.


