

How to Use Predefined File Names When Extracting PDF Pages in Acrobat

Question details
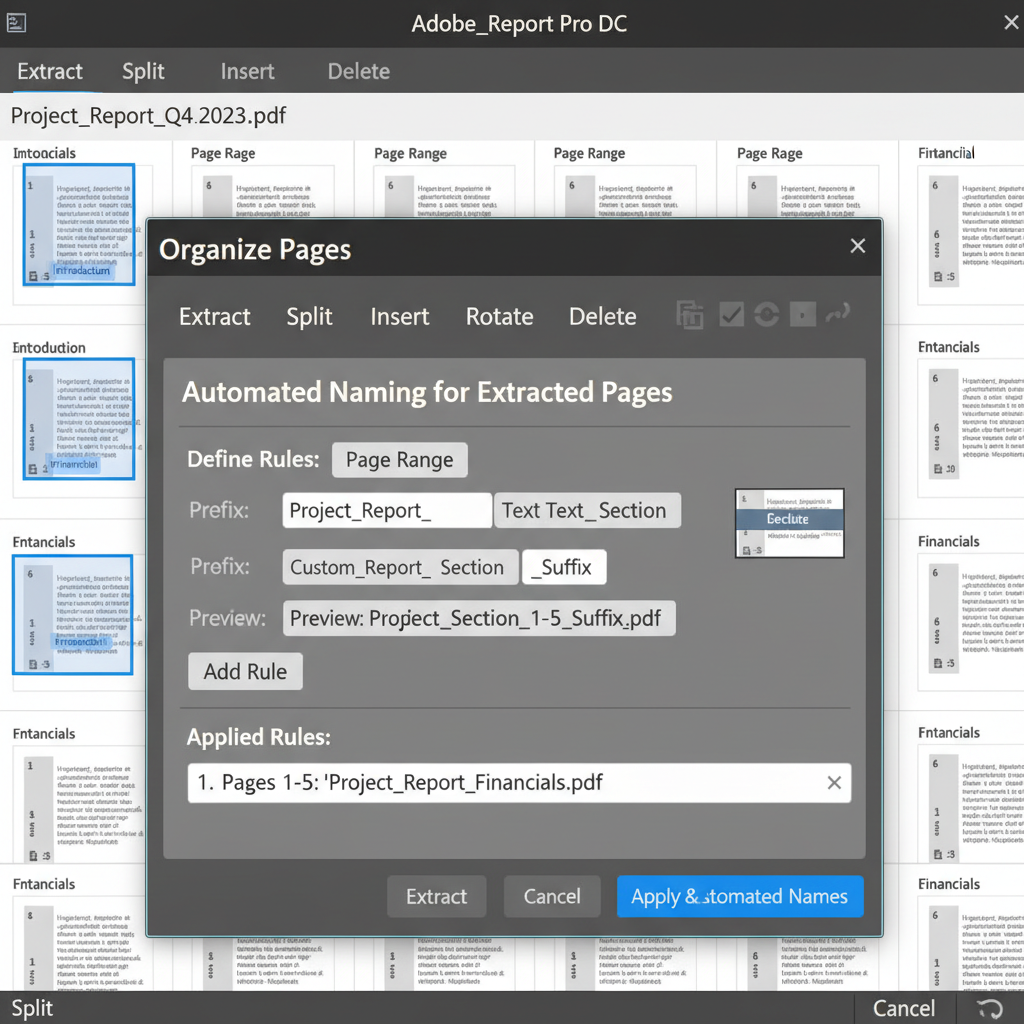
The user wants to automatically assign specific, predefined file names to extracted PDF pages or ranges instead of entering each file name manually.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Repeatedly splitting large, standardized PDF documents where consistent page ranges need to be extracted and saved with specific naming conventions.
- Observed behavior
- Acrobat's default Organize Pages tool requires manual intervention to name each extracted file, which slows down the workflow for recurring tasks.
Verify whether the page ranges you intend to extract are consistent across all your documents, or if they vary, as this will determine whether you should use a script or a bookmark-based splitting method.
Use an Acrobat JavaScript Workflow for Consistent Page Ranges
If your documents always follow the exact same page structure, you can automate the extraction and naming process using a custom JavaScript.
Acrobat supports running custom JavaScript to manipulate document pages. By writing a script that utilizes the extractPages method, you can map specific, unchanging page ranges directly to your predefined file names, bypassing the manual save prompts completely.
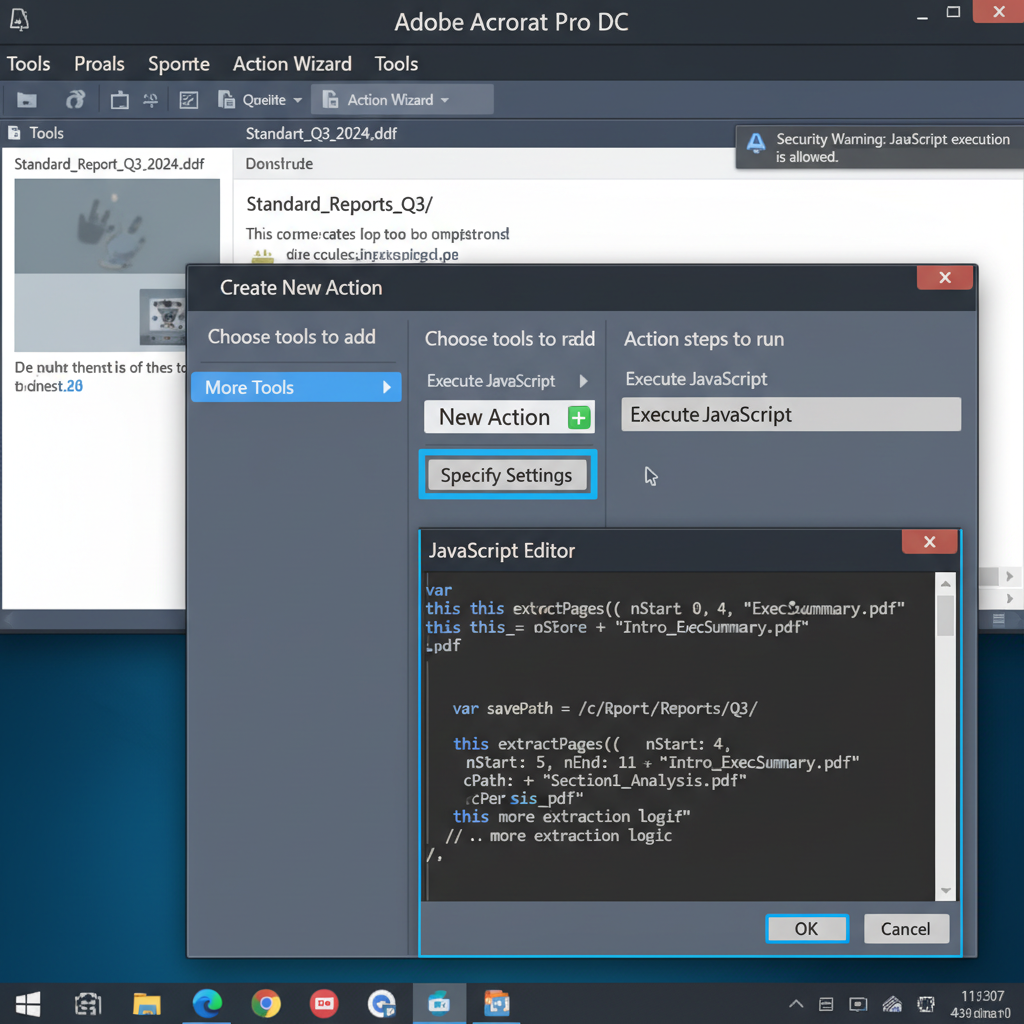
Open Adobe Acrobat, navigate to the 'Tools' menu, and select 'Action Wizard'.
Click on 'New Action'. Under the 'Choose tools to add' panel, expand 'More Tools' and select 'Execute JavaScript'.
Click 'Specify Settings' and enter your JavaScript code that defines the page ranges and assigns the predefined save paths and file names.
Save the Action. Whenever you open a standardized PDF document, run this Action from the Action Wizard list to automatically extract and name the pages.
Use Top-Level Bookmarks for Variable Page Ranges
If your page ranges change from document to document, set up bookmarks with your predefined file names to guide the extraction process.
Easily Split and Extract PDF Pages with WPS Office
If custom JavaScript coding in Acrobat seems too complex, WPS Office provides a highly intuitive PDF splitter. You can easily divide large documents, extract specific pages, and organize your files with a user-friendly interface that requires no programming knowledge.
- 1. Open the PDF File: Launch WPS Office and open the PDF document you need to split.
- 2. Access the Split PDF Tool: Navigate to the 'Page' tab on the top ribbon and click on 'Split PDF'.
- 3. Configure Splitting Options: Choose whether you want to split by specific page ranges, split evenly, or separate every page.
- 4. Extract and Save: Select your desired output folder and click 'Split' to instantly generate your extracted PDF files.

Frequently Asked Questions
Can I use form fields to name extracted PDF pages in Acrobat?
Yes. Advanced users can write an Acrobat JavaScript that locates specific form fields on a page, reads the text value within those fields, and uses that text string as the predefined file name when extracting the document.
Why does Acrobat's Organize Pages tool ask me to name files manually?
By default, when manually dragging or extracting custom pages via the Organize Pages interface, Acrobat doesn't know your naming convention and requires manual input to avoid overwriting existing files. Automating via scripts or splitting by top-level bookmarks bypasses this manual prompt.
What happens if a predefined file name already exists in the target folder?
If a script or extraction process attempts to save a file with a name that already exists in the target directory, it will typically either prompt you to overwrite, fail to save, or append a numerical suffix, depending on the exact script parameters or split output options selected.


