

How to View Metadata for Images Embedded in a PDF

Question details
The user wants to find out if images embedded within a PDF document retain their original metadata, such as owner, creation date, or capture date, and how to view this information.
- Product
- Device & OS
- not provided
- Scenario
- Inspecting the properties and hidden data of images embedded inside a PDF file.
- Observed behavior
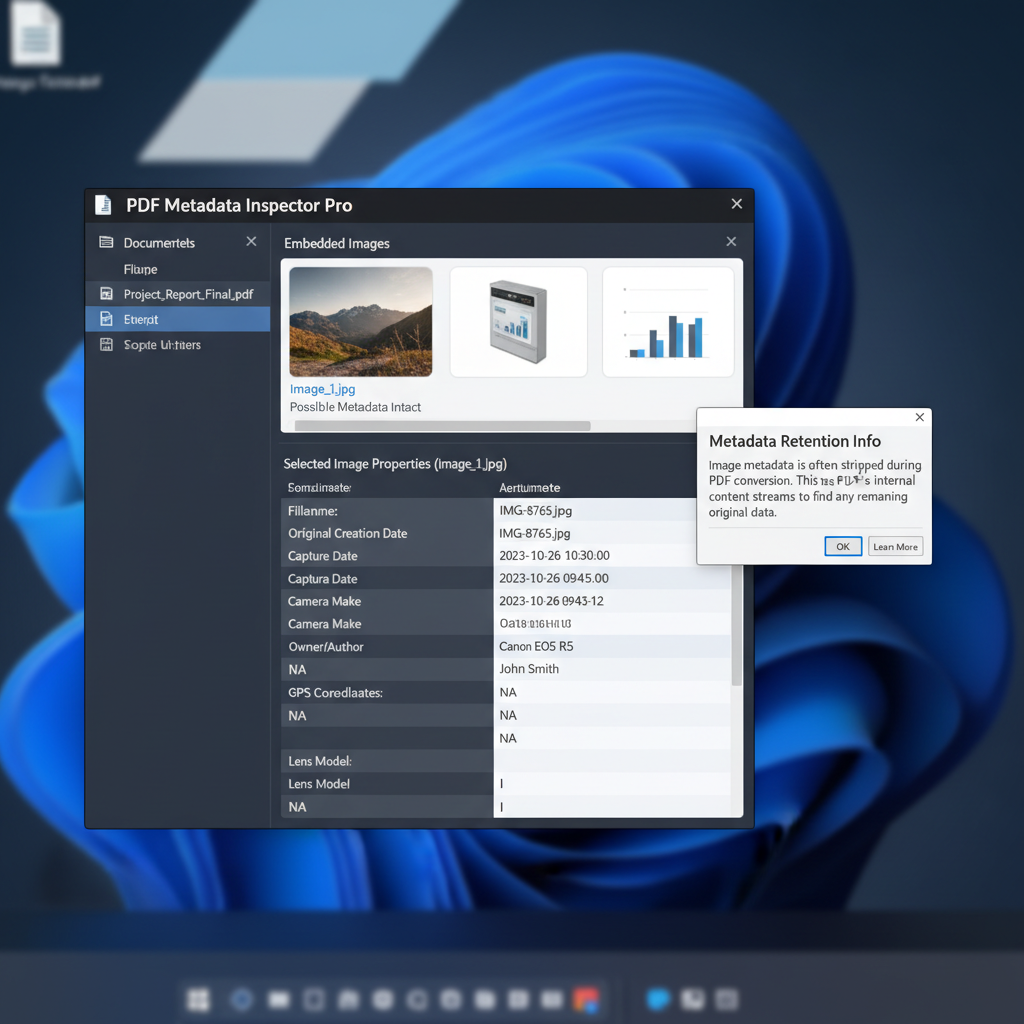
- Image metadata is often stripped during PDF conversion, requiring users to inspect the PDF's internal content stream to see if any original data remains.
Keep in mind that converting images into a PDF format usually strips their original EXIF data to compress the file size. You will be checking if any residual data was preserved in the document's internal dictionary.
Inspect Image Properties using Adobe Acrobat Content Panel
You can inspect the dictionary attributes of the image object in advanced PDF editors to see if any original metadata was preserved during the PDF creation.
When an image is inserted into a PDF, it is usually converted into a content stream, meaning most of the original EXIF data (like capture date or camera model) is removed. However, you can check the internal dictionary of the image object to be sure.
Launch Adobe Acrobat and open the PDF file containing the image you want to inspect.
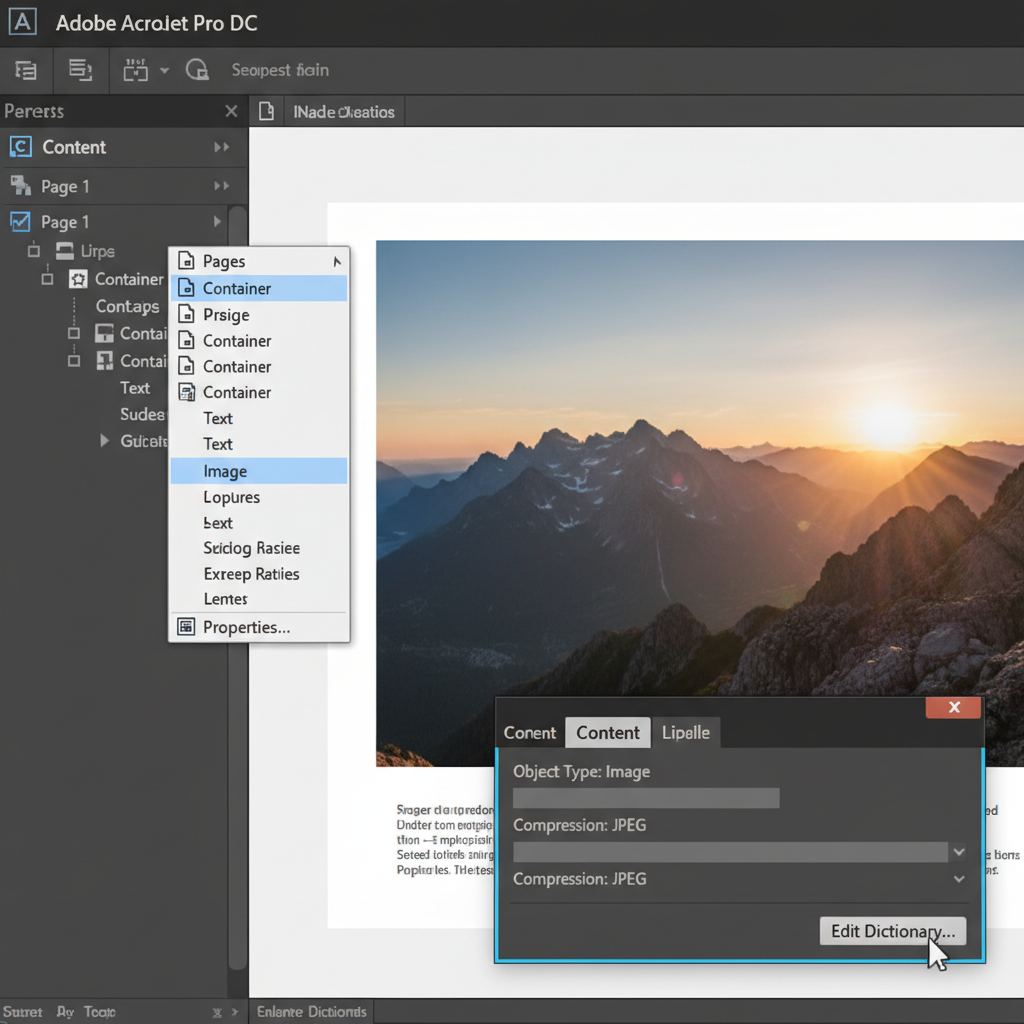
Navigate to the side navigation pane and open the 'Content' panel to view the internal structure of the document.
Expand the page tree within the Content panel and locate the specific 'Image' object that corresponds to your embedded picture.
Right-click the Image object and select 'Properties' from the context menu.
Go to the 'Content' tab in the Properties window and click 'Edit Dictionary' to review any remaining metadata tags.
Extract the Image to View Metadata Separately
If you cannot view the metadata within the PDF viewer's structure tree, extracting the image and using a standard OS image viewer might reveal hidden EXIF data.
Easily Extract and Inspect PDF Images Using WPS Office
WPS PDF provides user-friendly tools to edit PDF content, manage embedded images, and extract them for detailed inspection without losing quality. It is an excellent alternative for handling complex PDF tasks.
- 1. Install WPS Office: Download and install WPS Office for free, then open your PDF document in WPS PDF.
- 2. Enable Editing Mode: Go to the 'Edit' tab and click on 'Edit Content' to make the images and text blocks selectable.
- 3. Select the Image: Click or right-click the embedded image you want to investigate.
- 4. Extract Image: Select 'Extract Image' from the floating menu to save the picture to your local drive.
- 5. Inspect Metadata: Right-click the extracted image on your computer and check its properties for any retained data.

Frequently Asked Questions
Why does an image lose its metadata when saved as a PDF?
When documents are converted to PDF, images are often re-encoded into data streams to optimize file size and layout. This process inherently strips external metadata like EXIF camera settings, copyright info, or GPS coordinates.
Can I retain image metadata when creating a PDF?
Generally, standard PDF printers and converters remove metadata. To guarantee this information is kept, you would need to attach the original image file as a separate file attachment within the PDF rather than embedding it directly on the document page.
Are there third-party tools specifically for reading PDF image metadata?
Yes, advanced preflight tools or specialized metadata viewers (like ExifTool) can parse a PDF's internal structure to find hidden XMP metadata, though this requires technical knowledge to use via command line.


