

Why Acrobat OCR Does Not Delete Original Files & How to Manage Outputs

Question details
The user is asking why Adobe Acrobat does not automatically delete original files after completing a batch OCR process, even when certain deletion settings appear to be enabled.
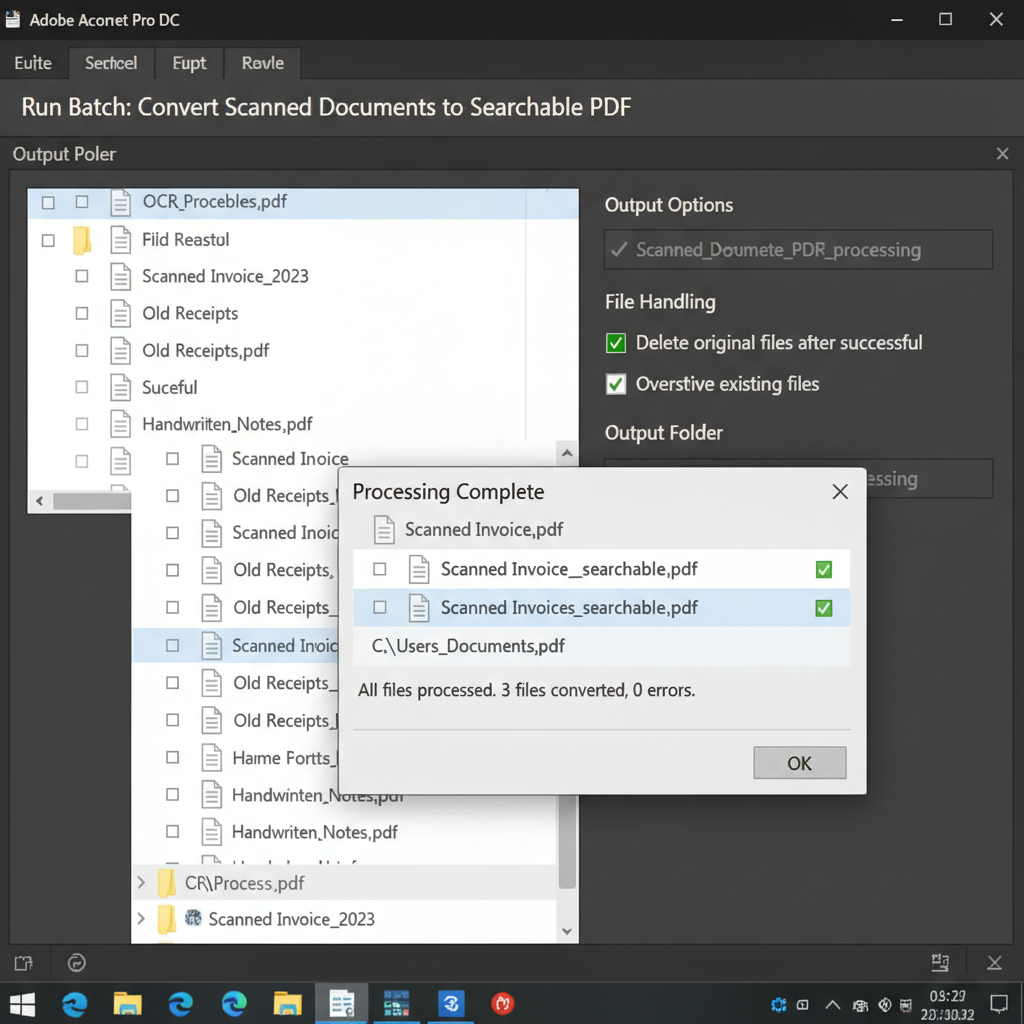
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Running batch OCR processing to convert scanned documents into searchable PDFs.
- Observed behavior
- The application generates searchable PDFs but leaves the original files intact in the folder instead of replacing or deleting them.
Before modifying your OCR output settings or manually deleting files, make sure your original PDF archive is fully backed up to prevent accidental data loss if the OCR process is incomplete.
Verify Action Wizard Output Settings
Check your specific Acrobat Action Wizard configuration to ensure the batch process is instructed to overwrite files rather than creating copies.
By design, Adobe Acrobat avoids automatically deleting original source files during batch processing. This is a built-in safety measure to ensure that if the OCR process fails or degrades document quality, the original unedited file is preserved.
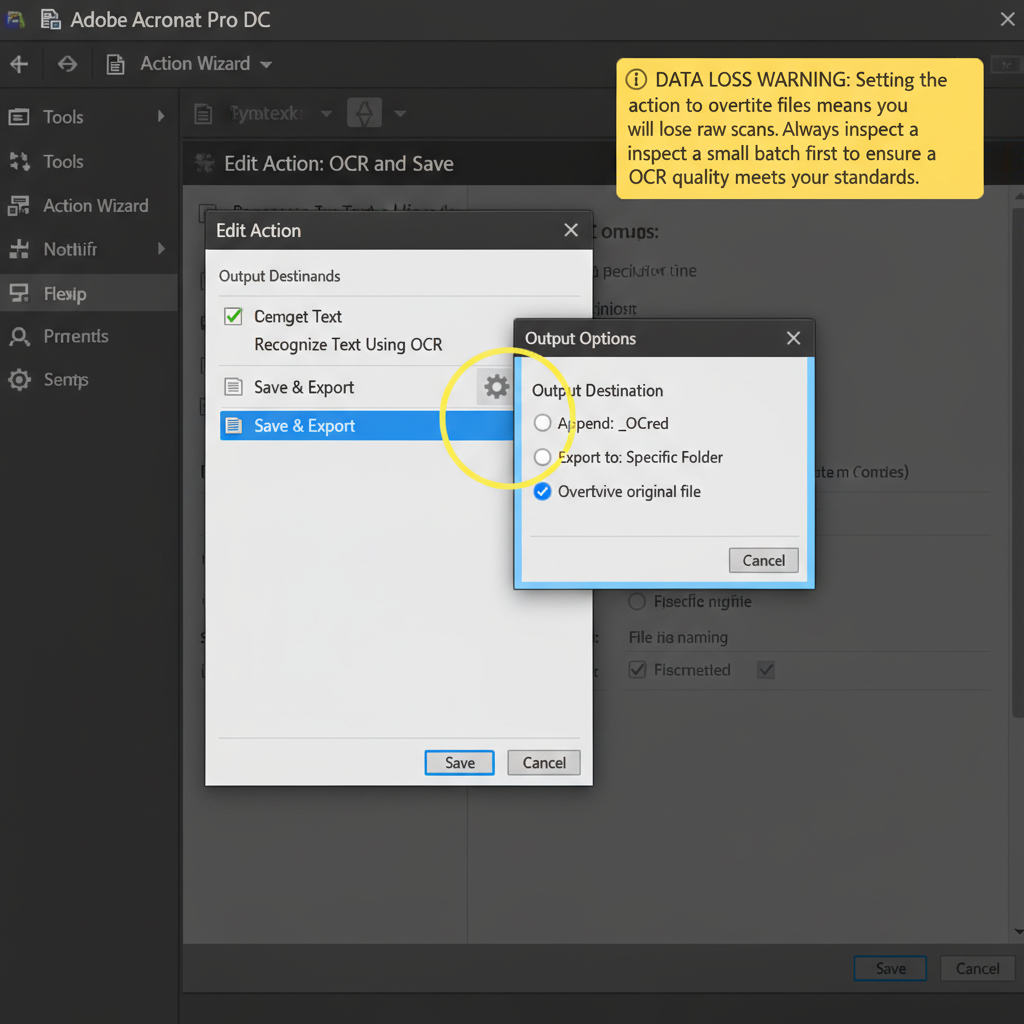
However, you can adjust your Action Wizard settings to overwrite the original files upon saving, which achieves the same result as deleting the original.
Launch Adobe Acrobat, navigate to the 'Tools' tab, and select 'Action Wizard'.
Select the specific OCR batch action you are running and click 'Edit' from the action panel.
Under the 'Save & Export' section, click the settings icon next to 'Save'. Change the output option to overwrite the original file instead of appending a suffix or saving to a new folder.
Click 'Save' to apply the changes to your workflow. The next time you run this batch process, it will replace the originals with the newly OCR-processed PDFs.
Perform a Manual Cleanup After Verification
Keep the default safety settings and manually remove the original files only after verifying the searchable PDFs are complete.
Use WPS Office to Extract Text from PDFs Seamlessly
If managing batch OCR outputs in Adobe Acrobat is confusing, WPS PDF offers a highly intuitive, built-in OCR tool. It quickly converts scanned documents into editable text or searchable PDFs with straightforward saving options, giving you full control over your files.
- 1. Open Document in WPS PDF: Launch WPS Office and open your scanned PDF or image document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Select Output Mode: Choose your desired extraction mode, such as 'Extract Text' for raw text or 'Searchable PDF' to maintain the document's original formatting.
- 4. Save and Replace: Once the OCR process finishes, click 'Save As' to explicitly choose your destination. You can select the same file name to effortlessly overwrite the original file.

Frequently Asked Questions
Does Acrobat have a setting to automatically delete original files after OCR?
No, Acrobat's default workflows do not automatically delete original source files. This is a built-in safeguard to prevent accidental data loss in case the OCR conversion fails or is interrupted.
Can I overwrite the original file instead of creating a new copy?
Yes. If you process a single file using the 'Recognize Text' tool and hit 'Save', it overwrites the original file. For batch processing, you must edit the Action Wizard settings to explicitly instruct the application to overwrite existing files rather than appending a suffix.
Why is the delete-old-file option not working in my batch process?
The Action Wizard might be configured to save processed files into a different directory or add text to the filename (e.g., 'Document_OCR.pdf'). When the output path or filename differs, the original file is never overwritten, rendering any assumed deletion step ineffective.
How can I easily separate processed PDFs from original files for manual deletion?
When setting up your batch OCR process, configure the output to save the searchable PDFs into a completely separate folder. Once the process is finished and you have verified the new folder, you can safely delete the entire contents of the original folder.


