

Why Acrobat Runs OCR When Exporting PDF to Word and How to Fix It

Question details
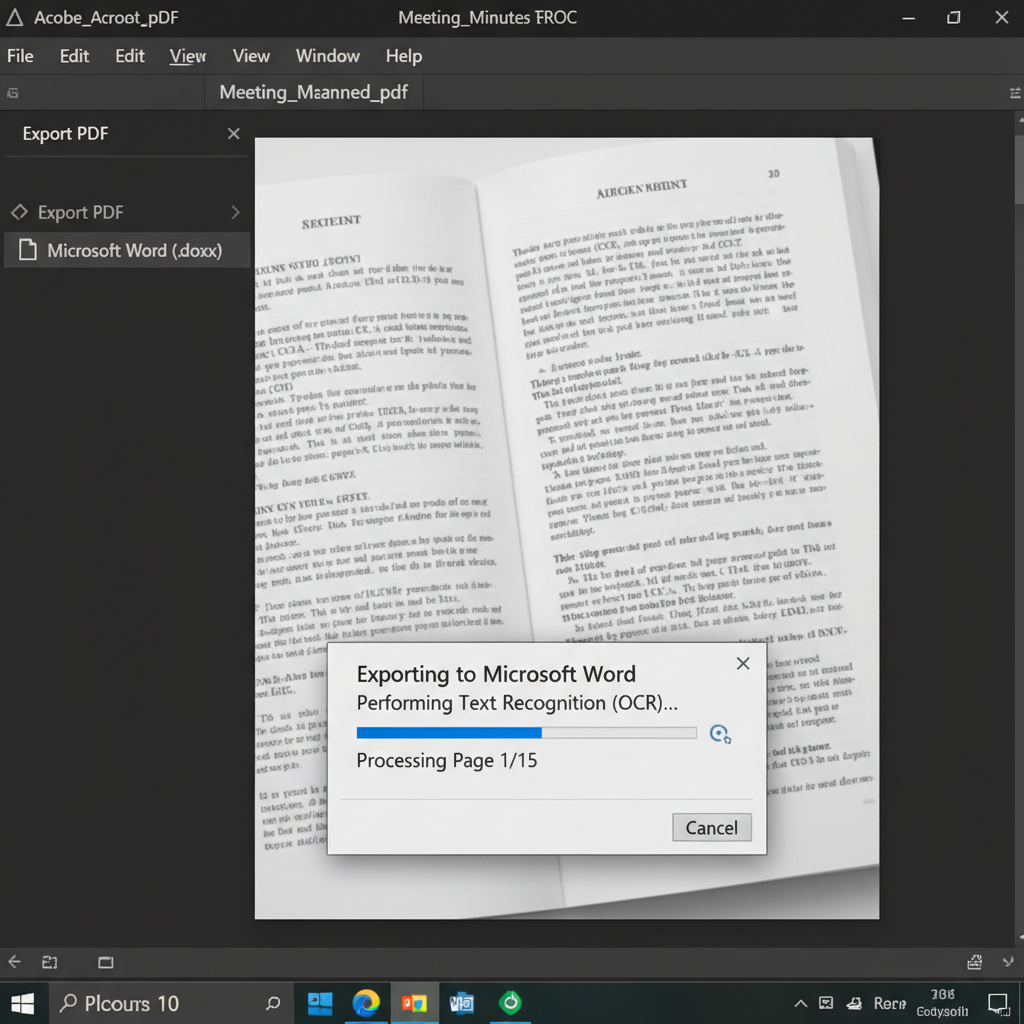
Users experience Adobe Acrobat automatically initiating an Optical Character Recognition (OCR) process when exporting a PDF to Word, even if auto-scanning settings appear disabled.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Exporting a PDF file into an editable Microsoft Word document.
- Observed behavior
- Acrobat forces the OCR process during export, usually because the source PDF lacks a reliable text layer, is flattened, or was created from a scanned image.
Verify if your PDF contains a selectable text layer by trying to highlight a few sentences with your cursor. If you cannot select individual words, the document is an image-based PDF and will mandate OCR for Word conversion.
Adjust Export Settings and Check Document Text Layers
Verify the properties of your PDF file and modify Acrobat's export preferences to prevent unwanted OCR on files that might already contain a text layer.
Acrobat is designed to automatically detect whether a PDF document contains a reliable text layer. If it determines the text is rendered as an image or flattened, it runs OCR to ensure the resulting Word document has editable text.
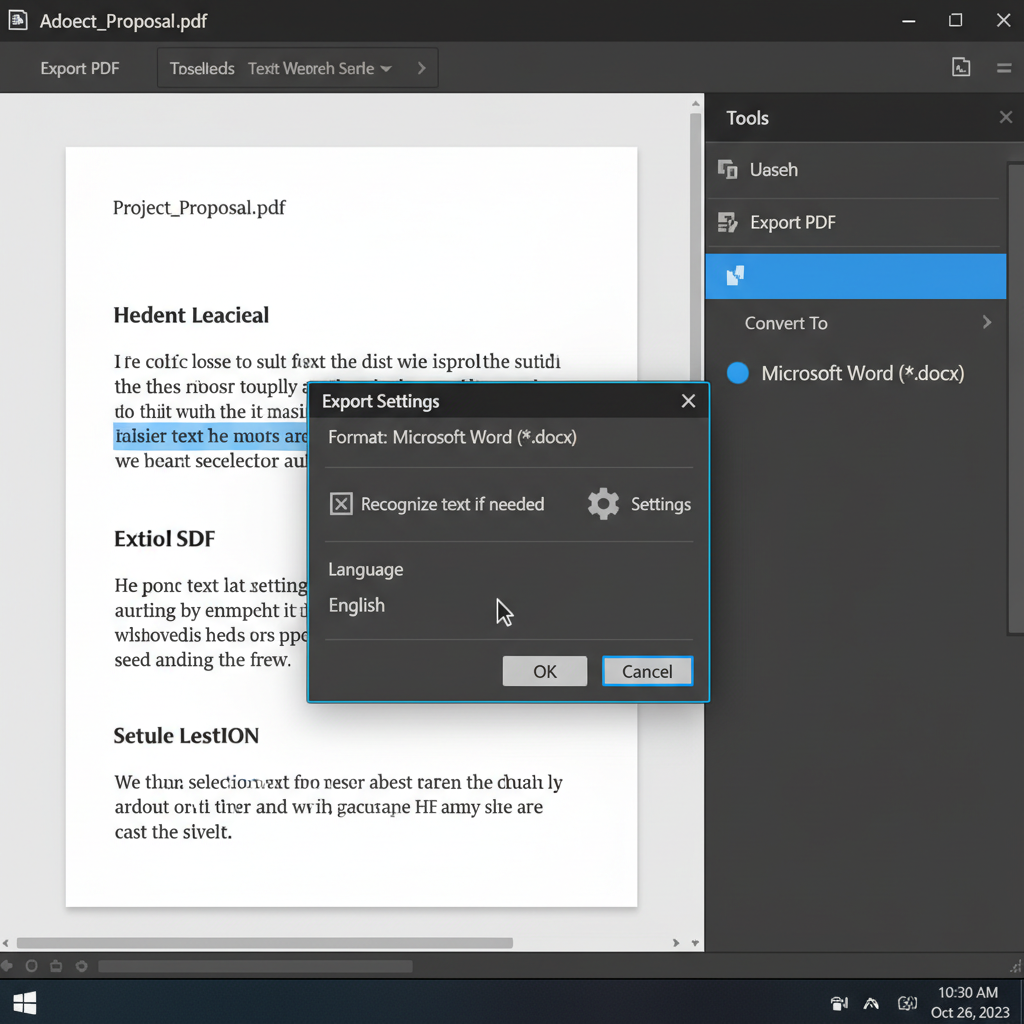
If you believe your document already has real text, manually turning off the 'Recognize text if needed' setting in the export options may resolve the issue.
Open your PDF document in Acrobat and drag your cursor over a paragraph. If the text highlights, it has a text layer; if not, OCR is strictly required.
Navigate to the right-hand panel and click on 'Export PDF'.
Choose 'Microsoft Word' as the desired export format, then click on the gear icon (Settings) located next to it.
Look for the 'Recognize text if needed' option under the settings menu. Uncheck this box, click 'OK', and then proceed to export the document.
Update Adobe Acrobat to the Latest Version
Ensure your software is up to date, as bugs in older versions can sometimes cause Acrobat to ignore export preferences and run OCR unnecessarily.
Convert PDFs to Word Effortlessly with WPS Office
If you want precise control over how your PDFs are converted to editable Word documents without wrestling with unwanted background processes, WPS PDF offers a highly accurate and user-friendly solution.
- 1. Open your PDF: Launch WPS Office and open the PDF file you wish to convert.
- 2. Access PDF to Word: Navigate to the 'Tools' tab on the top ribbon and click on the 'PDF to Word' button.
- 3. Configure conversion settings: Select your desired page range and choose whether to apply OCR based on your document's needs.
- 4. Start the conversion: Click 'Start' to convert your PDF into a perfectly formatted, editable Microsoft Word document.

Frequently Asked Questions
Can I permanently disable OCR in Acrobat during export?
While you can adjust OCR settings by clicking the gear icon in the Export PDF menu and disabling 'Recognize text if needed', Acrobat may still force the OCR process if it detects the PDF is entirely image-based and completely lacks a native text layer.
How do I know if my PDF is an image or contains real text?
Try using your mouse cursor to highlight a specific word or sentence in the document. If you can select and copy individual characters, the document contains a real text layer. If the entire page highlights as a single box or cannot be highlighted at all, it is an image-based PDF.
Does OCR change the formatting of my exported Word document?
Yes, OCR interprets shapes as text and attempts to visually recreate the original layout. This can sometimes result in minor formatting shifts, font substitutions, or incorrect character recognition compared to exporting a digital PDF that already contains real text.
Why is the OCR process taking so long to finish?
OCR requires significant processing power to analyze complex images, high-resolution scans, or documents with multiple columns and embedded graphics. Large files with dozens of scanned pages will naturally take longer to process than short, text-based documents.


