

Why Adobe Acrobat Shows Both Page Images and OCR Text in PDFs

Question details
Users are observing both the original scanned page images and recognized OCR text layers simultaneously or inconsistently when viewing an OCR-processed PDF.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Opening and viewing scanned PDF documents that have been processed with Optical Character Recognition (OCR).
- Observed behavior
- The PDF displays the scanned image and the recognized OCR text differently or overlapping, causing visual inconsistencies depending on document construction and display settings.
Verify whether your PDF was created using a 'Searchable Image' setting (which overlays invisible text on a scan) or an 'Editable Text/ClearScan' setting, as this determines how Acrobat renders the document.
Adjust Acrobat Page Display Preferences
Modify Acrobat's page display settings to prioritize the original scanned image while keeping the hidden OCR text layer active for searching and selecting.
In a 'Searchable Image' PDF, the original scan is kept as the visible background layer, while the recognized text is placed in an invisible layer on top. Display inconsistencies usually occur if the PDF reader struggles to render large scanned images properly or if specific rendering settings are disabled.
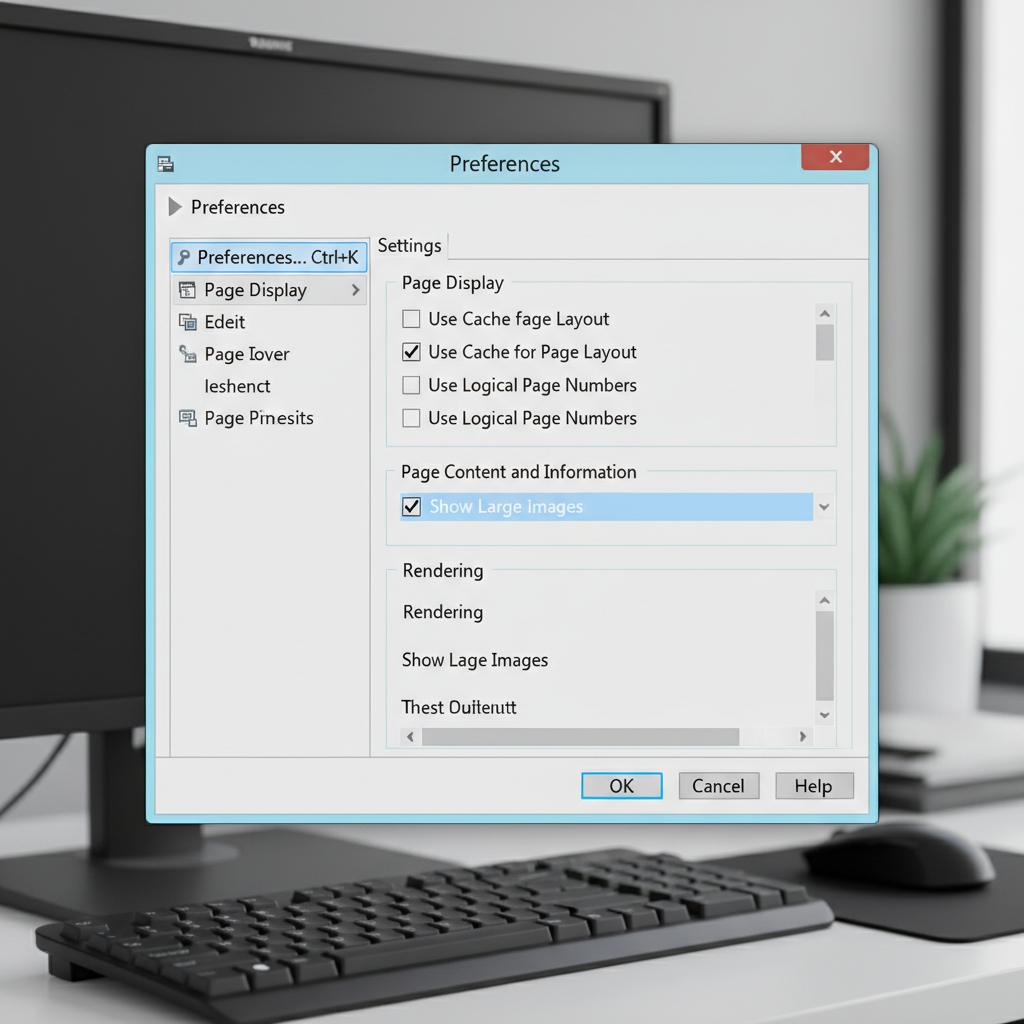
Launch Adobe Acrobat. Click on 'Edit' in the top menu and select 'Preferences' (or press Ctrl+K). On Mac, click 'Acrobat' in the top menu bar and select 'Preferences'.
In the Preferences dialog box, select 'Page Display' from the Categories list on the left-hand side.
Scroll down to the 'Page Content and Information' section and check the box next to 'Show Large Images'. This ensures high-resolution scans render correctly.
Click 'OK' at the bottom of the window to apply your changes. Close and reopen the PDF to see the correct visual rendering.
View and Manage OCR PDFs Seamlessly with WPS Office
WPS Office offers a built-in, lightweight PDF reader and editor that smoothly renders OCR-processed documents. It seamlessly integrates scanned images and searchable text layers without the visual clutter or rendering glitches sometimes found in other software.
- 1. Open your PDF: Launch WPS Office and open your OCR-processed PDF document using the built-in PDF viewer.
- 2. Select Text Seamlessly: Use your cursor to effortlessly highlight, copy, or search the invisible OCR text layer situated perfectly over the scanned image.
- 3. Perform New OCR (Optional): If the existing document is poorly processed, navigate to the 'Tools' tab and select 'OCR' to re-recognize the text clearly and accurately.

Frequently Asked Questions
What exactly is an OCR text layer in a PDF?
An OCR (Optical Character Recognition) text layer is a digital layer of text generated by software and placed over or under a scanned image. It makes the text in a picture searchable, selectable, and copyable without altering the original look of the scanned page.
Can I remove the scanned image background and keep only the text?
Yes. If you run OCR using a setting like 'Editable Text and Images' or 'ClearScan' instead of 'Searchable Image', the software replaces the scanned picture of the text with actual system fonts, effectively removing the image background and reducing file size.
Why does the text I copy from my OCR PDF look like gibberish?
This happens when the OCR engine misinterprets the characters due to low scan quality, handwriting, unusual fonts, or complex layouts. Re-running the OCR process on a higher-resolution scan usually improves text accuracy.
Does WPS Office support reading and creating OCR PDFs?
Yes, WPS PDF fully supports reading standard OCR-processed PDFs. It also includes a robust, premium OCR feature that allows you to convert standard image-based PDFs into fully searchable and editable documents.


