

Why Does OCR Increase PDF File Size and How to Fix It
Question details
The user wants to know why running OCR on a multi-page scanned document dramatically increases the file size and introduces visual artifacts, and seeks the best way to create searchable PDFs efficiently.
- Product
- PDF Editor
- Device & OS
- not provided
- Scenario
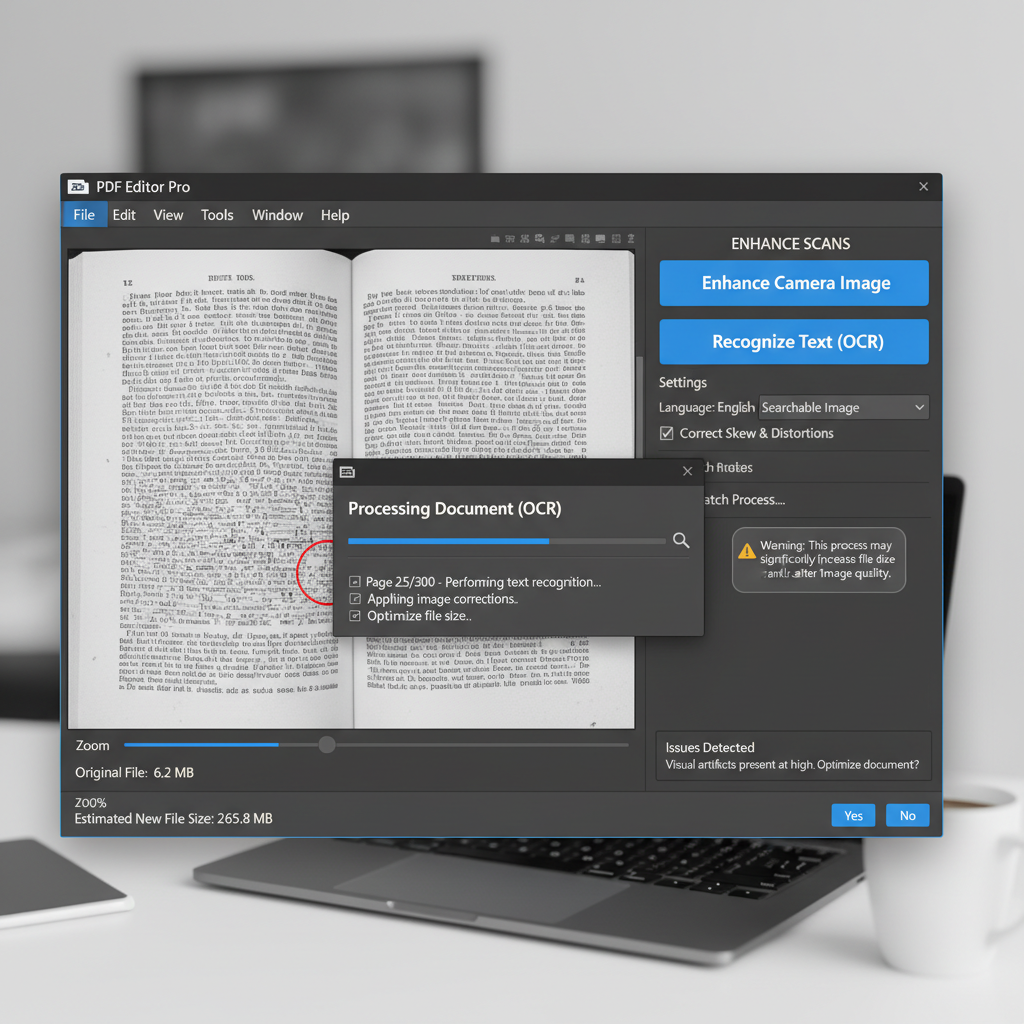
- Running Enhance Scans and Optical Character Recognition (OCR) on a scanned book to make the text searchable.
- Observed behavior
- The file size increases massively (e.g., from 6 MB to over 260 MB), and the document exhibits visible visual artifacts when viewed at high magnification.
Always keep an unmodified backup of your original scanned PDF before running OCR or compression tools, as image recompression and enhancement alters the document permanently.
Adjust OCR Settings and Compress the PDF Output
Modify the OCR output style to prevent the software from unnecessarily altering and upscaling background images, then use a PDF optimizer to reduce the final file size.
OCR tools often increase file size because the software doesn't just add a tiny text layer; it may attempt to 'enhance' the scan, thereby recompressing the background images at higher qualities or saving them in unoptimized formats. Adjusting the recognition settings and compressing the file afterward is the most effective workaround.
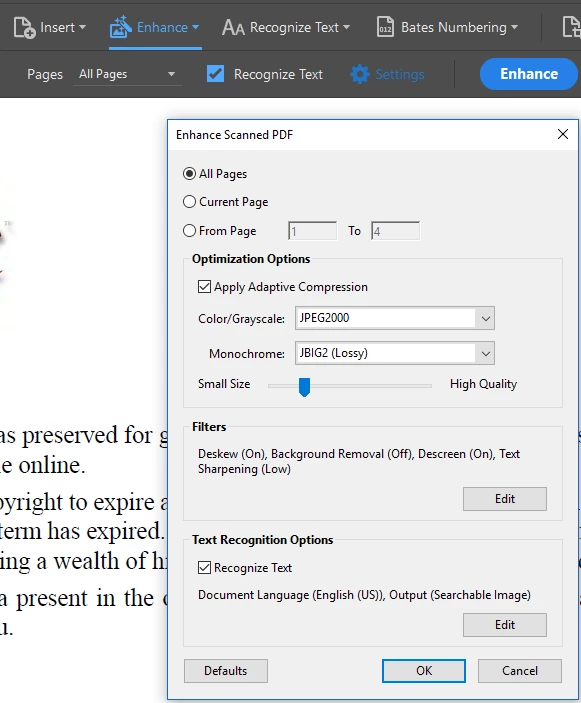
Open your PDF editor and navigate to the 'Scan & OCR' or 'Enhance Scans' tool. Before clicking recognize, click on the Settings (gear icon) or Options menu.
Locate the 'Output Style' or 'PDF Output Style' dropdown. Change it to 'Searchable Image' rather than 'ClearScan' or 'Searchable Image (Exact)'. This prevents the engine from converting fonts into vector outlines or drastically altering the underlying image pixels.
Click 'OK' to save the settings and run the OCR process on your scanned document.
Once OCR is complete, navigate to 'File' > 'Save as Other' > 'Reduced Size PDF' (or use the 'Optimize PDF' tool). Select standard compression settings to downsample images and discard hidden metadata, significantly shrinking the file size.
Use WPS Office to Perform OCR and Compress PDFs
WPS Office offers an advanced PDF editor with built-in OCR and smart compression tools. You can easily make scanned documents searchable with high accuracy while keeping the final file size perfectly optimized.
- 1. Open your scanned PDF: Launch WPS Office and open your scanned PDF document in the WPS PDF tool.
- 2. Run OCR recognition: Navigate to the 'Tools' tab and select 'OCR'. Choose your output mode to convert the document into a searchable PDF.
- 3. Compress the document: Once the OCR process is complete, return to the 'Tools' tab and click on 'Compress'.
- 4. Select compression level: Choose your desired compression level (e.g., HD, Normal, or Standard) and click 'Compress' to dramatically reduce the file size.
Frequently Asked Questions
Why does my PDF look blurry or have artifacts after running OCR?
Some OCR settings automatically attempt to enhance, deskew, or smooth the scanned images (such as 'ClearScan' or 'Enhance Scans'). While this can make text look cleaner at normal zoom levels, it often introduces visible artifacts when zoomed in. Disabling automatic image enhancement in your OCR settings usually resolves this.
Does adding a searchable text layer cause the file bloat?
No, the hidden text layer itself takes up very little space (typically just a few kilobytes per page). The massive file size increase is caused by the OCR engine recompressing, uncompressing, or altering the background images during the recognition process.
Can I reduce the size of a PDF that has already been processed with OCR?
Yes. You can use a standard PDF compression tool to downsample the images and remove unnecessary data. However, if the images were permanently altered or degraded by the initial OCR process, it is best to apply compression to a freshly OCR'd file using the correct non-altering settings.


