

Fix Excel Power Query 'This Table is Empty' Error When Importing PDF

Question details
Users encounter an empty table error when trying to extract data from a PDF file using Excel's Get Data feature.
- Product
- Microsoft Excel
- Device & OS
- not provided
- Scenario
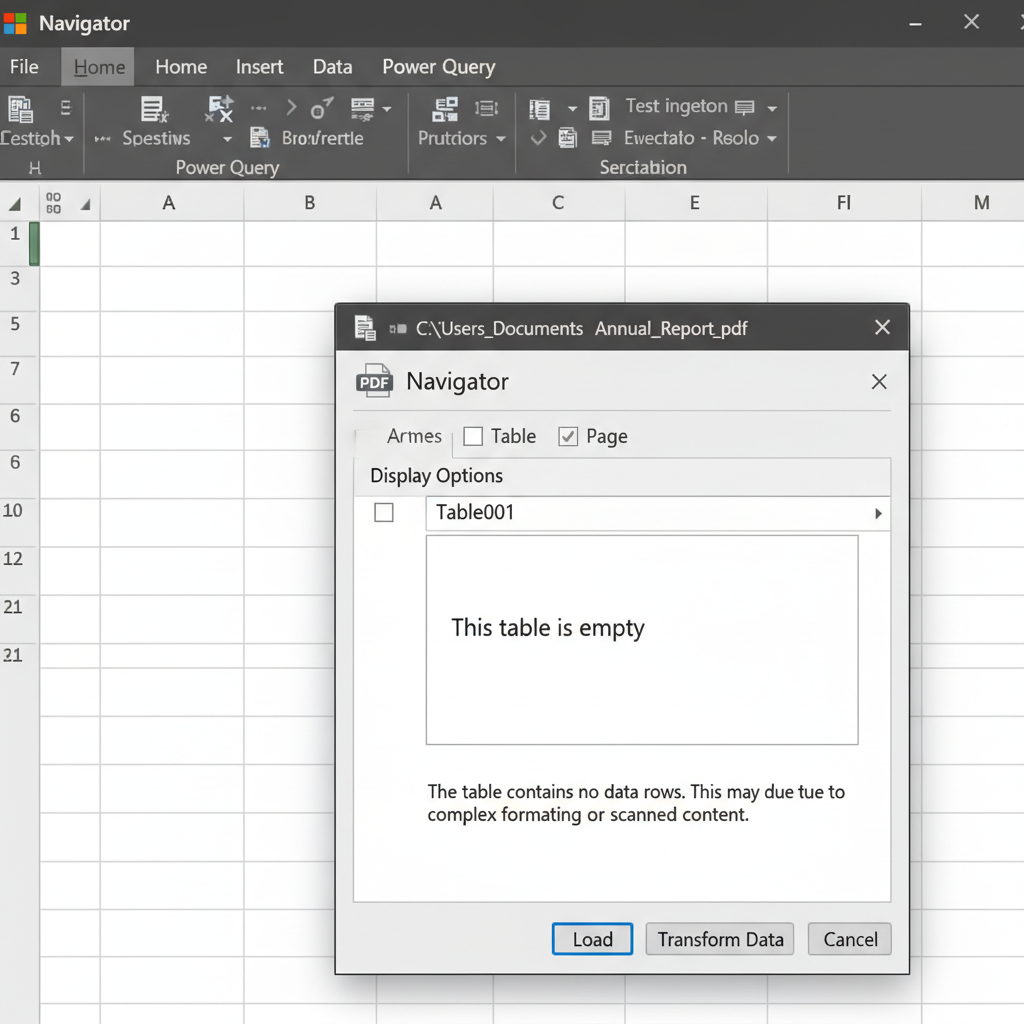
- Attempting to import tabular data from a PDF document into an Excel spreadsheet using the Power Query 'From PDF' connector.
- Observed behavior
- Excel successfully connects to the PDF file but displays a 'This table is empty' message instead of extracting the expected data rows, often due to complex formatting or scanned content.
Ensure that your PDF file is not password-protected and verify whether the document contains actual selectable text or is simply a scanned image.
Convert the PDF to Excel Using a Dedicated PDF Tool
Using a dedicated PDF to Excel converter bypasses Power Query's structural limitations and easily captures complex formatting.
Excel's built-in PDF connector struggles with unusual encoding or heavily formatted documents. Converting the document directly to an Excel file using advanced PDF software is often the fastest and most accurate workaround.
Launch a dedicated PDF management application such as WPS Office or Adobe Acrobat.
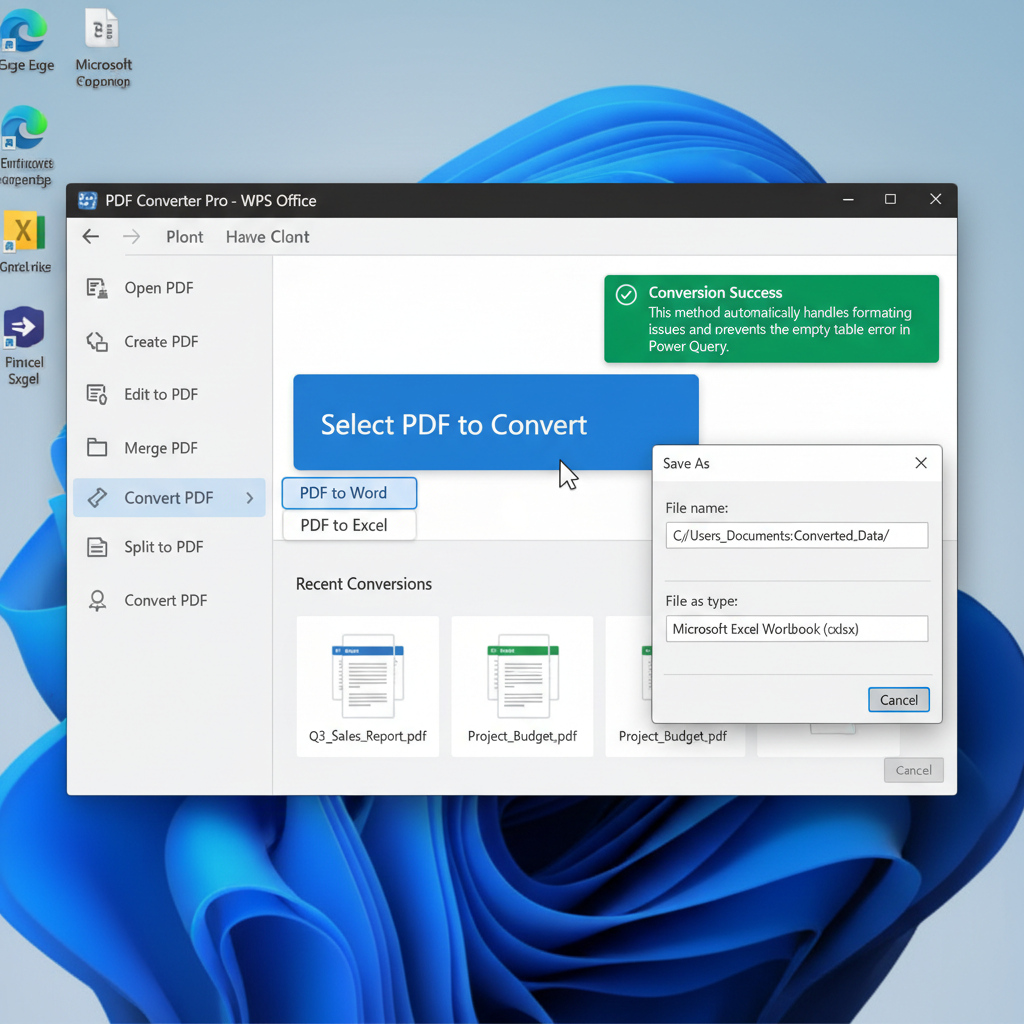
Navigate to the conversion tools menu and click on the 'PDF to Excel' option.
Select your target PDF, save the converted output to your computer, and open the new .xlsx file directly in Excel to access your data.
Inspect Individual Page Elements or Flatten the PDF
Power Query might misinterpret layered PDFs. Checking specific page elements or re-saving the PDF as a flattened file can resolve the issue.
Extract Data Manually or Use OCR for Scanned PDFs
If the PDF is a scanned image, Power Query cannot extract text natively. You must use OCR or manual copy-pasting combined with Text to Columns.
Easily Convert PDFs to Excel with WPS Office
Skip complex Power Query errors. WPS Office features a powerful built-in PDF converter that accurately extracts tables from PDFs into perfectly formatted spreadsheets in seconds, effortlessly handling complex formatting and scanned documents.
- 1. Open WPS Office: Launch WPS Office and click on the 'PDF' tab to open your document.
- 2. Select PDF to Excel: Navigate to the 'Tools' menu and click on 'PDF to Excel' in the conversion options.
- 3. Convert and Save: Adjust the page range if needed, click 'Convert', and save your extracted table as a fully compatible .xlsx spreadsheet.

Frequently Asked Questions
Why does Power Query say my PDF table is empty?
This usually happens when the PDF contains complex formatting, layered content, unusual text encoding, or is a scanned image without a recognizable text layer, causing Excel's detector to fail.
Can Excel Power Query extract data from a scanned PDF?
No, Power Query does not have built-in OCR (Optical Character Recognition) capabilities. To extract data from a scanned PDF, you must first convert it to searchable text using an external OCR tool before importing it into Excel.
How does flattening a PDF help with Power Query extraction?
Flattening a PDF removes complex layers, embedded fonts, and interactive elements, turning the document into a standardized visual layout. This simplified file structure makes it much easier for Power Query to recognize and extract embedded tables.


