

Fix Power Query Fixed-Width Text Imports That Split Rows Incorrectly

Question details
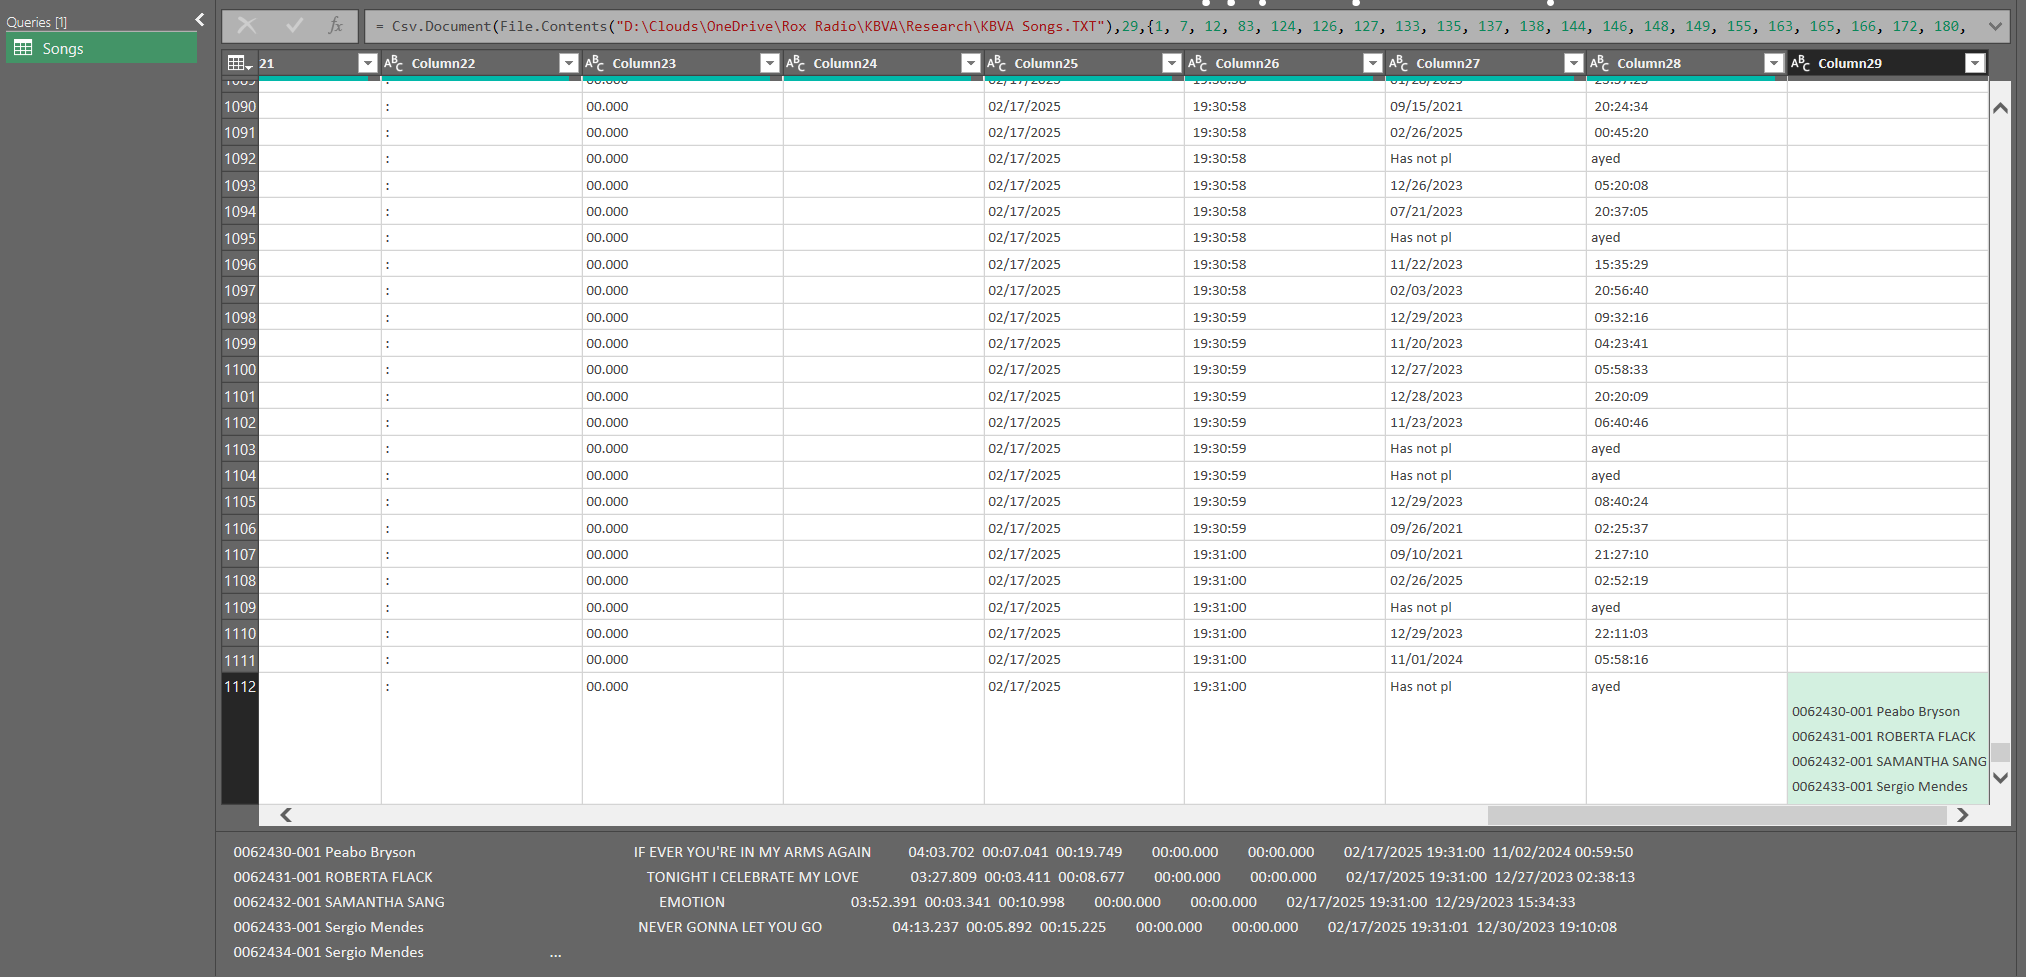
The user needs to properly import a fixed-width text file into a spreadsheet without the data breaking alignment or spilling into unintended columns after a certain number of rows.
- Product
- Microsoft Excel
- Device & OS
- not provided
- Scenario
- Importing a large fixed-width text file into Excel via Power Query.
- Observed behavior
- After approximately 1,100 rows, the fixed-width text stops aligning correctly and shifts the remaining data into a new column unexpectedly.
Verify your text file's encoding format and use a text editor to visually inspect the data around the specific row where the error begins for any hidden control characters or unexpected line breaks.
Import as Individual Lines and Split by Character Position
Bypass the default parser by importing the entire text file into a single column without delimiters, then apply a fixed-width split using exact character positions.
By treating the source text file as binary line data rather than relying on Power Query's default text parsing, you prevent unexpected row breaks. You can then define the exact numerical character breakpoints to maintain strict column boundaries.
Open Power Query, navigate to the Home tab, select 'Advanced Editor', and replace the source step to import the file as lines. Use the M-code: Source = Table.FromColumns({Lines.FromBinary(File.Contents("C:\your_file.txt"), null, null, 65001)}).
You will now see a single column (usually named Column1) containing all the rows of your text file. Click the column header to select it.
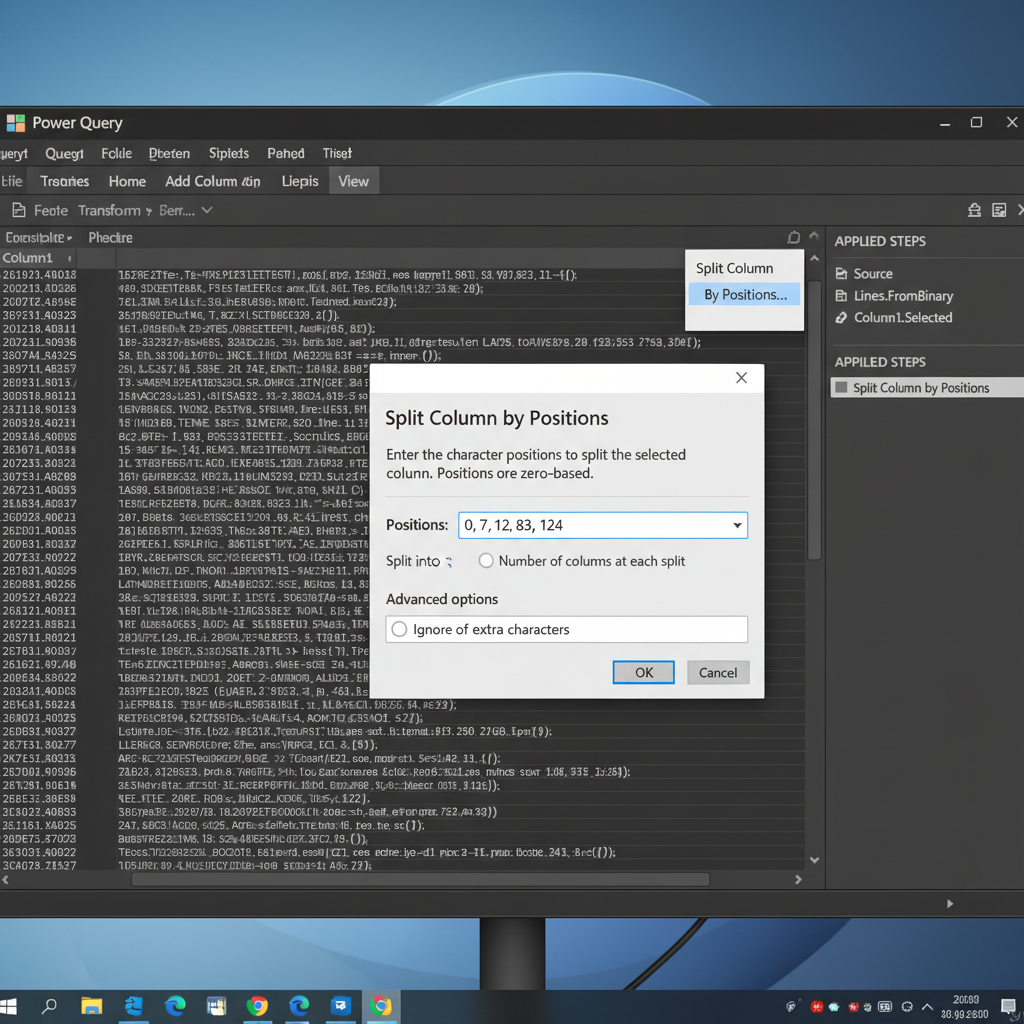
Navigate to the 'Transform' tab, click on 'Split Column', and choose 'By Positions'.
In the dialog box, enter the exact comma-separated character positions corresponding to your data columns (for example: 0, 7, 12, 83, 124). Click 'OK' to apply the split.
Inspect File Encoding and Remove Invisible Characters
Check the source text file for data corruption, invisible control characters, or encoding shifts that confuse the Power Query import engine.
Looking for a simpler way to import data? Try WPS Office
If troubleshooting complex Power Query M-code is too cumbersome, WPS Office provides a free, lightweight alternative. WPS Spreadsheet features an intuitive Text Import Wizard to easily handle fixed-width data without requiring advanced coding. It is fully compatible with Microsoft Excel file formats.
- 1. Download and Install: Download WPS Office for free from the official website and open WPS Spreadsheet.
- 2. Open Your Text File: Go to 'Data' > 'Import Data' and select your fixed-width text file.
- 3. Use the Import Wizard: Select 'Fixed width' in the Text Import Wizard and follow the visual guide to place column breaks exactly where you need them.

Frequently Asked Questions
Why does Power Query split my fixed-width text incorrectly halfway through the file?
This usually happens due to unexpected hidden control characters, a shift in file encoding, or irregular line breaks located around the affected row that confuse the default parsing engine.
Can I manually adjust the fixed-width column boundaries during import?
Yes. When using the 'Split Column by Positions' feature in Power Query, you can manually type in the exact character breakpoints as a comma-separated list to force strict column boundaries regardless of row content.
What does the encoding number 65001 mean in my Power Query script?
In Power Query M-code, 65001 is the code page identifier for standard UTF-8 encoding. Setting this ensures that special characters and formatting are read accurately during the import.


