

How to Find the 4th, 5th, and 6th Most Frequent Text Values in Excel

Question details
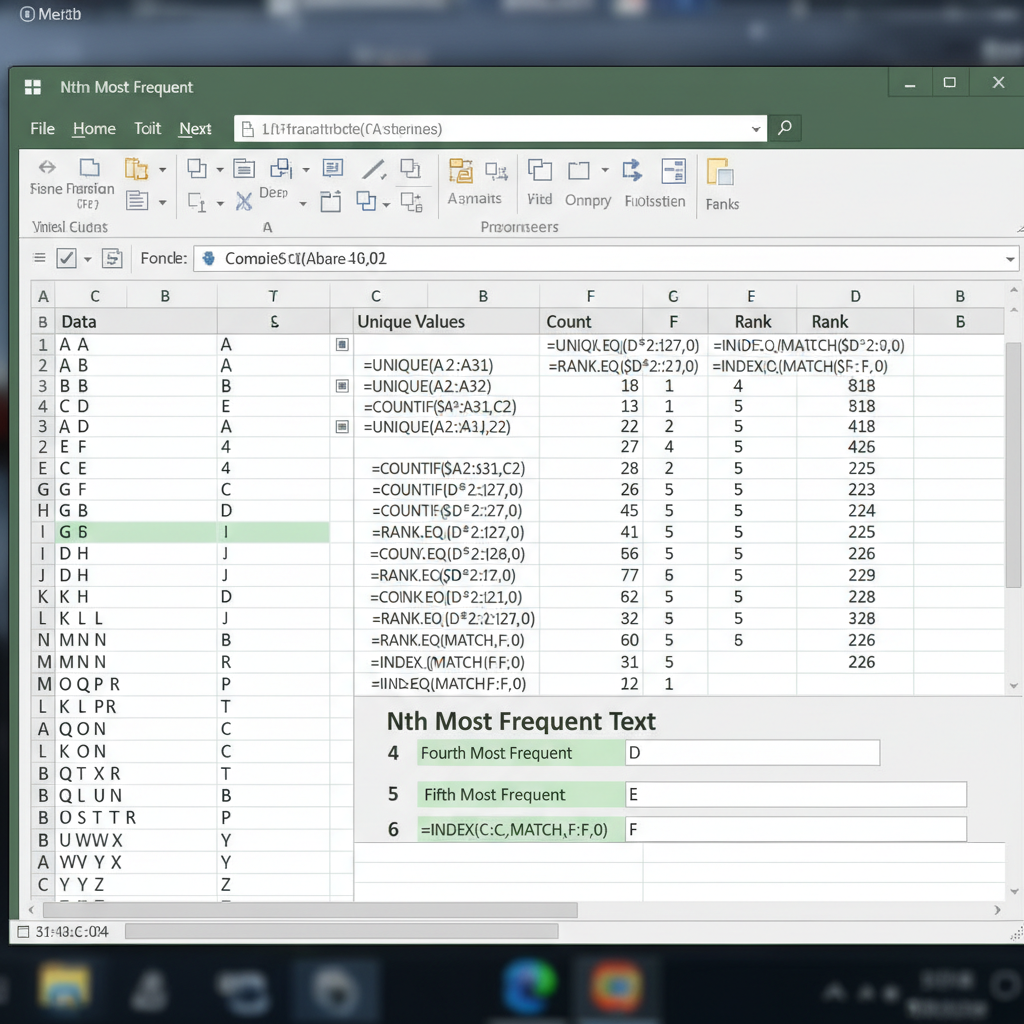
The user wants to identify the fourth, fifth, and sixth most frequently occurring text values (such as English letters) within a dataset without using overly complex array formulas.
- Product
- Excel
- Device & OS
- not provided
- Scenario
- Analyzing non-numeric data to extract and rank text frequencies beyond the top three most frequent items.
- Observed behavior
- Standard functions like MODE only return the single most frequent number, making it difficult to extract the Nth most frequent text values natively.
Ensure your text dataset does not contain unintended blank cells, trailing spaces, or inconsistent capitalization, as these can cause identical letters or words to be counted as separate unique values.
Create a Summary Table Using COUNTIF and RANK.EQ
This lightweight approach creates a simple summary table to count the occurrences of each text value and ranks them, allowing you to easily filter for the 4th, 5th, and 6th most frequent items.
While complex array formulas can extract the Nth most frequent text directly, they are often resource-intensive and difficult to maintain. Using a helper table with COUNTIF and RANK.EQ is a much simpler, cleaner, and faster solution for non-numeric data.
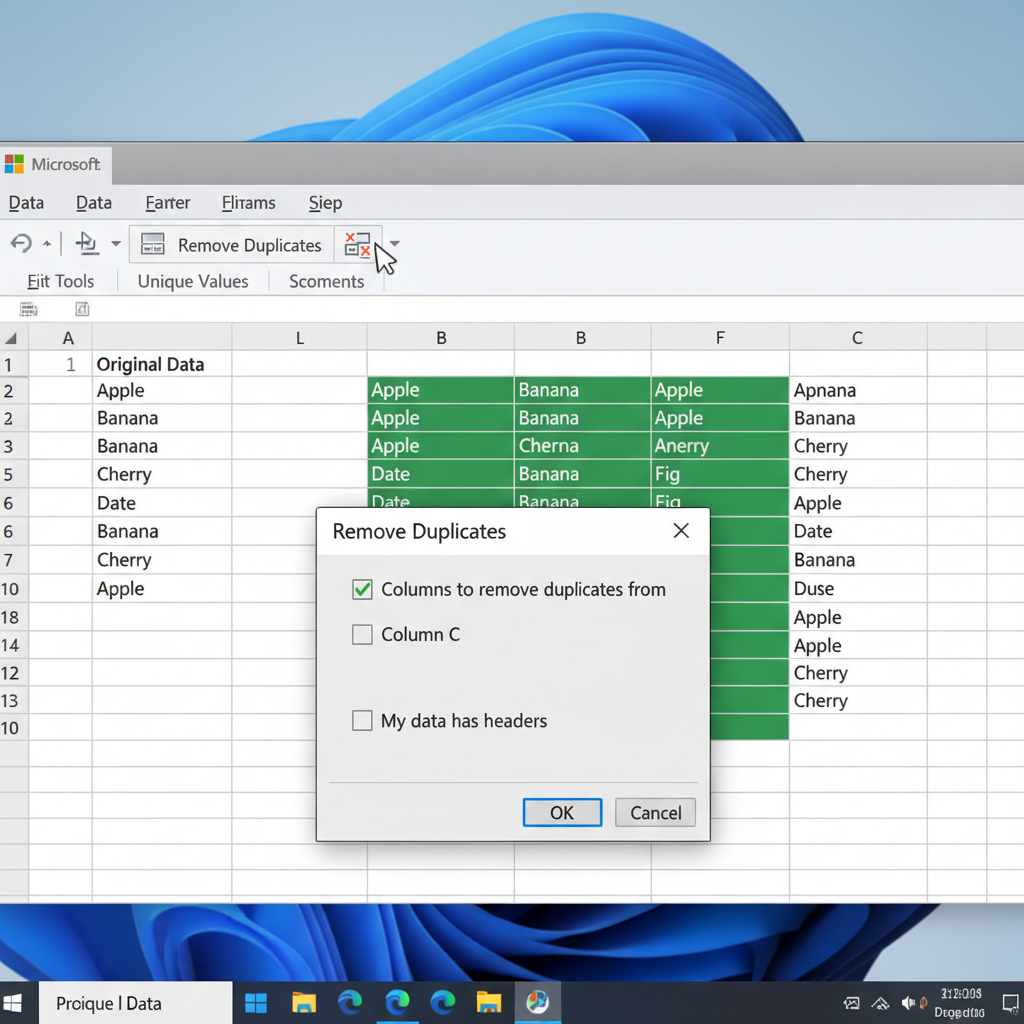
Copy your entire column of text data and paste it into a new, empty column. Keep this new column selected, navigate to the Data tab on the ribbon, and click 'Remove Duplicates' to leave only a list of unique text entries.
In the cell directly next to your first unique value, type the formula =COUNTIF(A:A, C2) (assuming your original data is in column A and your unique value is in C2). Drag this formula down to calculate the frequency for every unique text value.
In the next adjacent column, type the formula =RANK.EQ(D2, D:D) (assuming your counts are in column D). Drag this formula down. This assigns a numerical rank based on how high the count is.
Select your new summary table headers, go to the Data tab, and click 'Filter'. Click the filter drop-down arrow on the Rank column and select only the numbers 4, 5, and 6 to display your desired results.
Use a Pivot Table to Sort and Filter
A Pivot Table automatically aggregates identical text values and counts them, allowing you to visually identify or filter for the Nth most frequent items without writing any formulas.
Find Most Frequent Values Easily with WPS Spreadsheet
WPS Spreadsheet provides intuitive data analysis tools, including advanced PivotTables, instant Duplicate Removal, and over 400 built-in functions. It makes counting, ranking, and extracting the most frequent text values incredibly easy without slowing down your computer.
- 1. Open your data in WPS Spreadsheet: Launch WPS Office and open your spreadsheet containing the text data.
- 2. Create a Pivot Table: Select your data column, click 'Insert' from the top ribbon, and choose 'PivotTable'.
- 3. Drag and drop fields: Drag your text field into both the 'Rows' box and the 'Values' box to instantly calculate the frequency of each unique entry.
- 4. Sort to find Nth values: Right-click the values column, choose 'Sort' > 'Descending', and easily view your 4th, 5th, and 6th most frequent text values.

Frequently Asked Questions
Can I use the MODE function to find the most frequent text in Excel?
No, the MODE, MODE.SNGL, and MODE.MULT functions only work with numeric values. They will return an error if you attempt to use them on text data like English letters or names. You must use COUNTIF or a Pivot Table for text.
Is there a single formula to find the 4th most frequent text value?
Yes, but it requires a complex array formula using INDEX, MATCH, COUNTIF, and LARGE functions. For example: =INDEX(A:A, MATCH(LARGE(COUNTIF(A:A, A:A), N), COUNTIF(A:A, A:A), 0)). However, this is highly resource-intensive and not recommended for large datasets.
How do I break ties when ranking the most frequent text values?
If using the RANK.EQ method, you can break ties by adding a tiny sequential fraction to your counts. For example, instead of ranking the raw count, rank the result of =COUNTIF(A:A, C2) + (ROW()/100000). This ensures every count is technically unique, preventing duplicate ranks.


