

How to Fix #NUM! Errors in Excel Regression P-Values

Question details
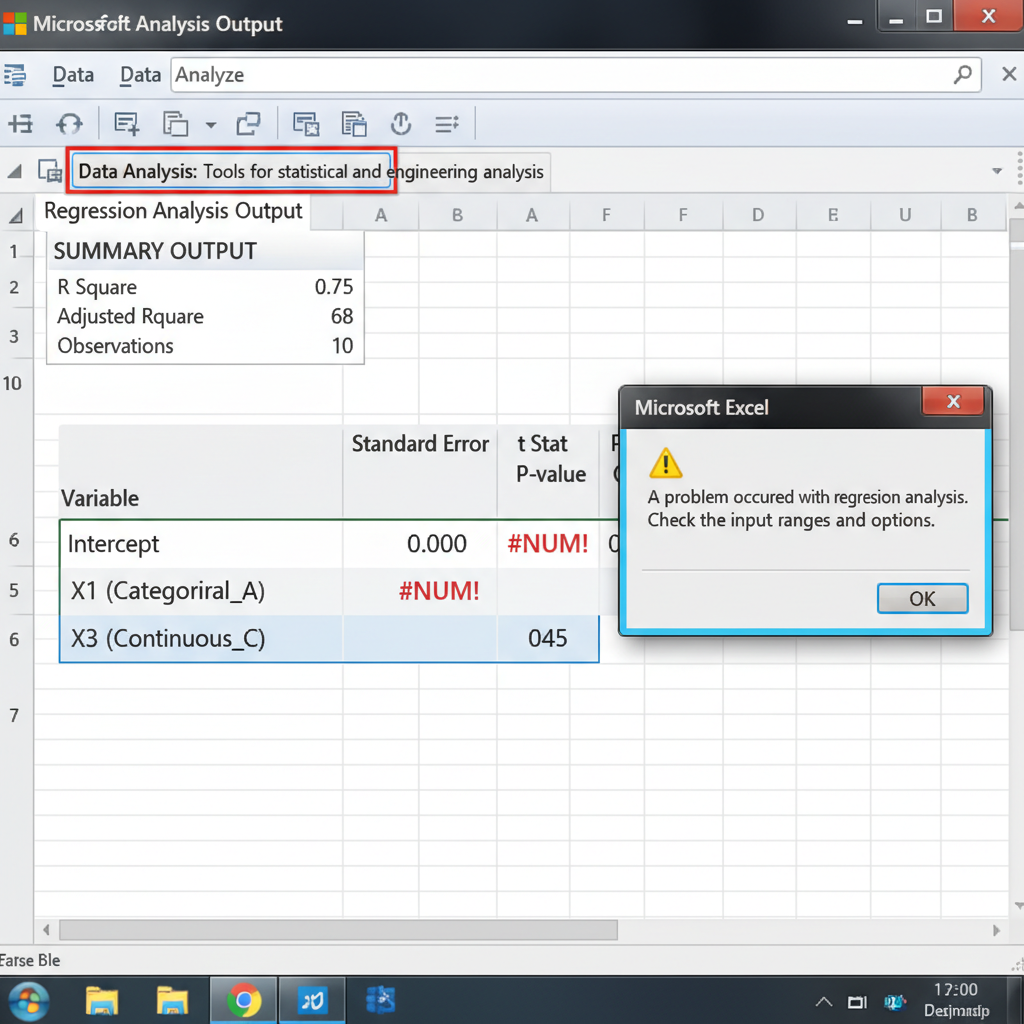
The user is encountering a #NUM! error in the p-value results when running a regression analysis in Excel.
- Product
- Microsoft Excel
- Device & OS
- not provided
- Scenario
- Running regression analysis with categorical variables or small sample sizes.
- Observed behavior
- Excel returns #NUM! errors for p-values instead of numeric probabilities, often due to statistical issues like multicollinearity or insufficient variation.
Before troubleshooting, ensure your dataset does not contain completely empty rows and verify that you have more observations (rows) than predictor variables (columns).
Resolve Multicollinearity and Redundant Predictors
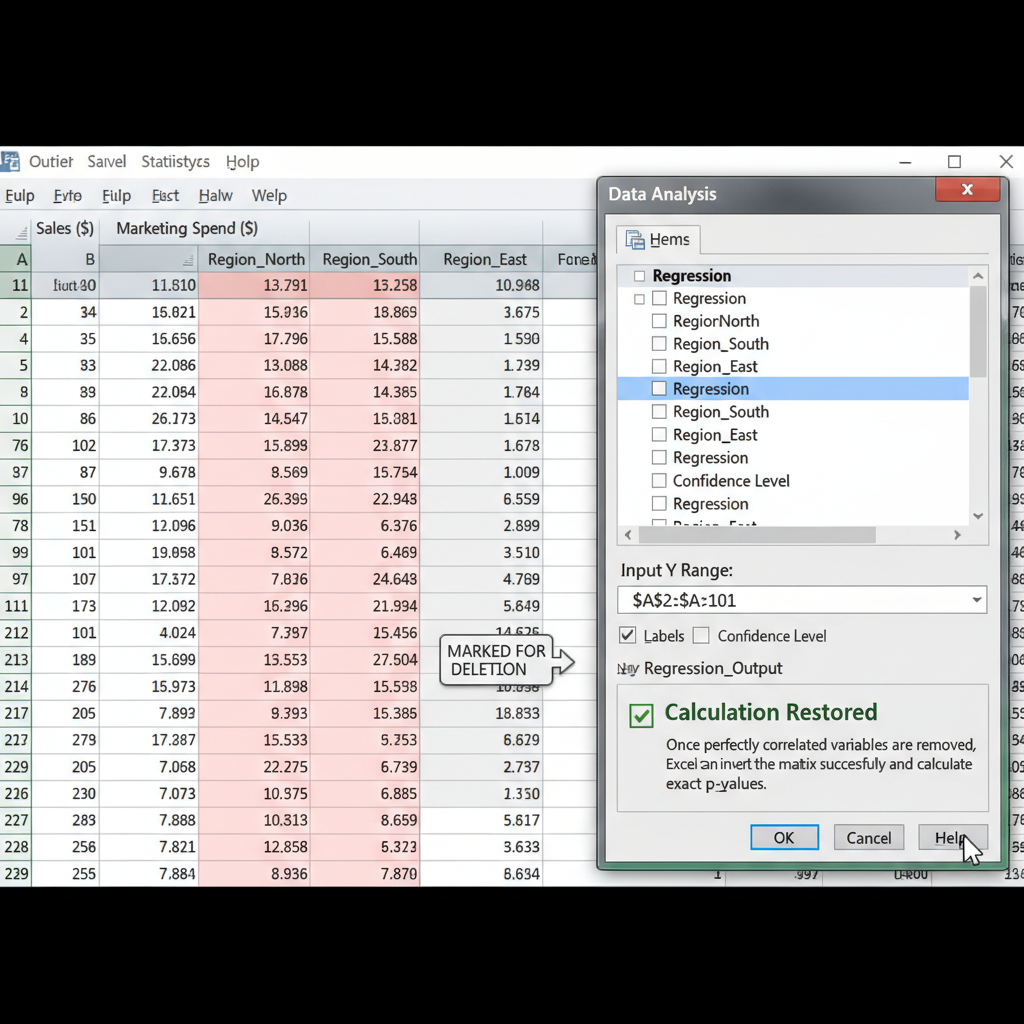
Identify and remove duplicate or highly correlated independent variables that cause perfect separation in your regression model.
The #NUM! error in regression p-values usually indicates a mathematical impossibility, such as dividing by zero during matrix inversion. This happens when variables are perfectly collinear or completely redundant.
Check your independent variables (X range) for any duplicate columns or variables that represent the exact same data.
Check for categorical variables that are over-encoded. Ensure you exclude one baseline category when using binary indicator (dummy) variables so they do not sum to 1 across all rows.
Delete the redundant columns from your spreadsheet. Then, re-run the regression analysis by navigating to Data > Data Analysis > Regression.
Fix Constant Categories and Increase Sample Size
Ensure your dataset has enough variation and a sufficient number of observations per category.
Perform Accurate Regression Analysis with WPS Spreadsheets
WPS Spreadsheets provides a built-in Data Analysis toolkit that makes it easy to run regression models. With intuitive dialog boxes and robust formatting, you can efficiently analyze your data, manage categorical variables, and generate reliable statistics without compatibility issues.
- 1. Prepare your dataset: Open your dataset in WPS Spreadsheets and ensure your independent variables are clean, distinct, and free of perfect multicollinearity.
- 2. Access Data Analysis: Go to the Data tab on the top ribbon and click on Data Analysis. (If not visible, enable it in Menu > Options > Add-ins).
- 3. Select Regression: Select 'Regression' from the analysis tools list and click OK.
- 4. Input variable ranges: Input your Y Range (dependent variable) and X Range (independent variables), then select your preferred output location.
- 5. Generate output: Click OK to generate your summary output, complete with accurate R-square values, coefficients, and P-values.

Frequently Asked Questions
Why do I only get #NUM! for some variables but not others?
This typically occurs when specific variables in your model exhibit perfect collinearity or have zero variance, while other variables are independent. The statistical software can calculate metrics for the independent ones but fails mathematically on the collinear ones.
Can formatting the cells as numbers fix the #NUM! error in p-values?
No. In the context of regression analysis, the #NUM! error is a statistical and mathematical calculation failure (such as dividing by zero), not a display or formatting issue. You must fix the underlying data structure.
What does 'perfect separation' mean in regression?
Perfect separation happens when a predictor variable perfectly predicts the outcome variable without any overlap or variation (often in logistic regression or heavily skewed data). This causes the calculation matrix to fail, resulting in a #NUM! error.


