



How to Remove Duplicate Excel Rows While Keeping the Complete Record

Question details
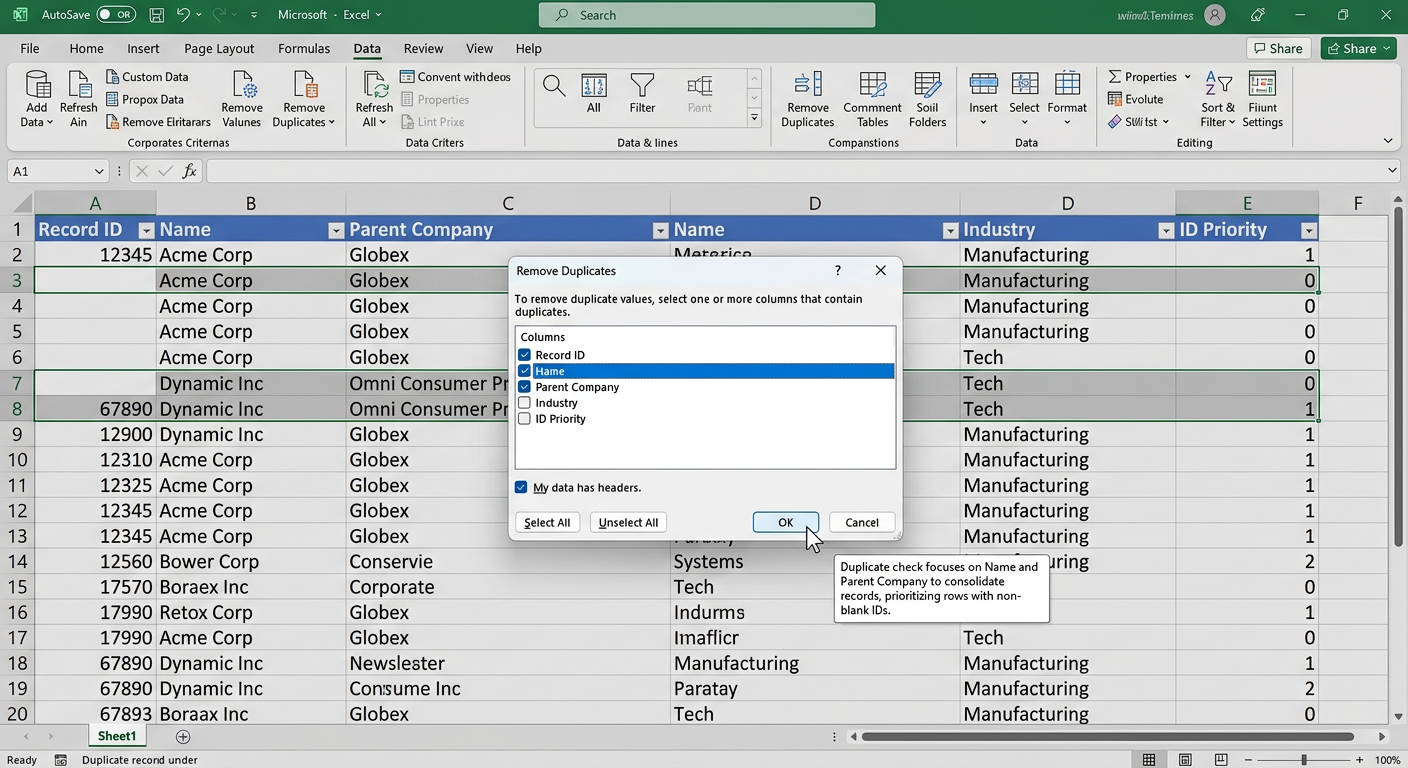
The user needs to remove duplicate records based on specific columns like Name and Parent Company, but must ensure the remaining row is the one that contains a populated ID rather than a blank one.
- Product
- Excel
- Device & OS
- not provided
- Scenario
- Cleaning up a dataset containing duplicate entries where some rows lack essential ID information, making standard deduplication unreliable.
- Observed behavior
- Using the standard deduplication tool might randomly keep the first occurrence of a duplicate, which could be a row with missing data instead of the complete record.
Before removing duplicates, review your data columns to identify which fields determine a duplicate and temporarily create a copy of your worksheet to prevent accidental data loss.
Sort Data and Use the Remove Duplicates Feature
Sorting your dataset ensures the complete row (with the populated ID) appears first, prompting Excel to retain it when processing duplicates.
The standard 'Remove Duplicates' feature in Excel keeps the first occurrence of a duplicate row and deletes the rest. By sorting the complete records to the top of each duplicate group, you can control which row is kept.
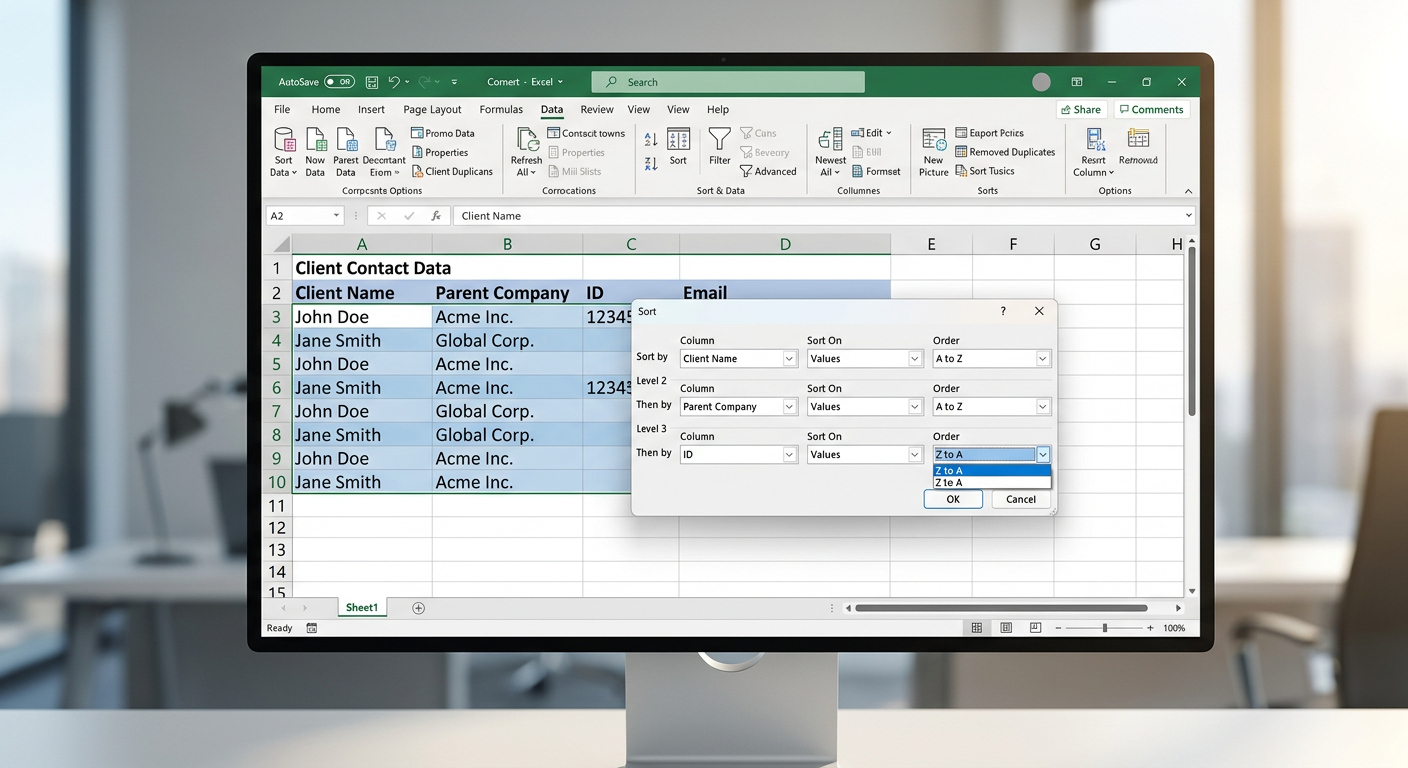
Select your entire dataset, navigate to the 'Data' tab, and click the 'Sort' button.
In the Sort dialog box, add levels to sort by 'Name', then by 'Parent Company', and finally by 'ID'.
For the 'ID' sort order, choose 'Z to A' or 'Largest to Smallest' so that rows with populated IDs appear before the blank ones. Click 'OK'.
With the sorted data still selected, click 'Remove Duplicates' under the 'Data' tab.
In the dialog box, check only the 'Name' and 'Parent Company' columns to evaluate duplicates based on those fields, then click 'OK'.
Use Power Query for Larger Datasets
Power Query is ideal for large datasets, allowing you to group data and specifically extract the maximum or non-blank ID without altering the original raw data.
Extract Complete Rows Using the FILTER Formula
If you want to dynamically extract only the rows that have no blank cells across all columns without permanently deleting original data.
Easily Remove Duplicates and Organize Data in WPS Spreadsheet
WPS Spreadsheet provides powerful, intuitive tools for data sorting and deduplication. You can seamlessly process large datasets, reliably remove duplicates based on specific criteria, and ensure your most complete records remain intact.
- 1. Open Your Data: Launch WPS Spreadsheet and open the dataset containing your duplicate records.
- 2. Sort by ID: Navigate to the 'Data' tab and use the 'Sort' function to arrange rows, setting the ID column to descend so populated IDs appear first.
- 3. Initiate Deduplication: Click 'Remove Duplicates' located in the 'Data' ribbon.
- 4. Confirm and Clean: Select the target identifier columns (e.g., Name and Parent Company) and click OK to effortlessly retain your complete records.
Frequently Asked Questions
Why does Excel keep the blank row when removing duplicates?
By default, the 'Remove Duplicates' feature keeps the very first occurrence of a duplicate value from top to bottom and deletes all subsequent ones. If the first occurrence has a blank ID, Excel will keep that incomplete row. Sorting the data beforehand fixes this.
Can I use Conditional Formatting to highlight duplicates instead of deleting them?
Yes. Select your data, go to the 'Home' tab, click 'Conditional Formatting', choose 'Highlight Cells Rules', and select 'Duplicate Values'. This is a great way to visually review the data before permanently removing rows.
Is there a way to merge data from duplicate rows rather than deleting them?
The standard Remove Duplicates tool only deletes rows. To merge data, you would need to use Power Query's 'Group By' feature or Pivot Tables to aggregate data, such as summing numerical values or concatenating text from multiple duplicate records.


