

Identify Similar Duplicate File Names in Excel Power Query

Question details
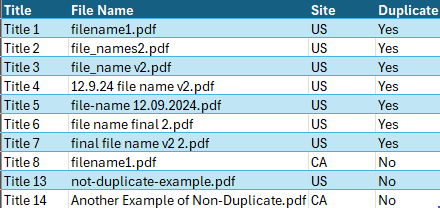
The user needs a method to identify similar, but not exactly identical, file names within specific sites in a large Excel dataset.
- Product
- Microsoft Excel
- Device & OS
- not provided
- Scenario
- Cleaning a large dataset where duplicate file names might have slight variations, such as underscores, dates, version numbers, or words like 'Final'.
- Observed behavior
- Standard duplicate detection tools fail because they require exact character-by-character text matches, missing files that are functional duplicates but have minor naming variations.
Before beginning, establish clear normalization rules for your file names (e.g., deciding whether 'v1' and 'v2' count as duplicates) to prevent false positives during the matching process.
Use Power Query Fuzzy Matching
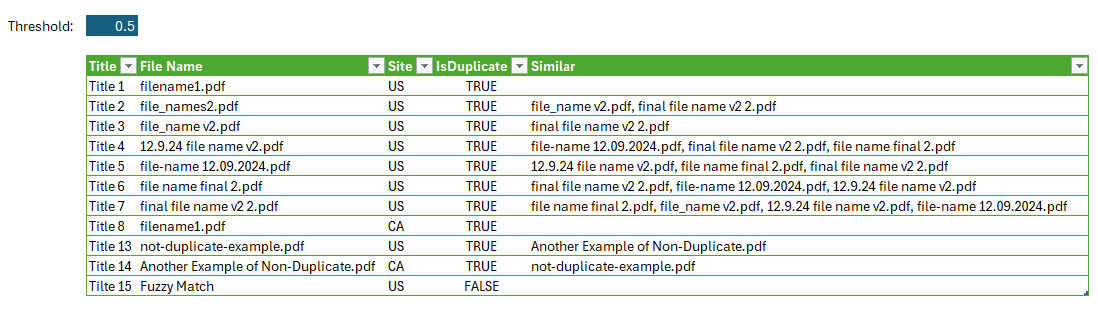
Leverage Power Query's FuzzyNestedJoin feature to find non-exact matches based on similarity thresholds.
Fuzzy matching allows you to join tables based on approximate matches rather than exact matches. This is the most efficient way to catch file names that differ only by minor typos, underscores, or missing spaces without writing incredibly complex nested formulas.
Select your data range in Excel, go to the 'Data' tab, and click 'From Table/Range' to open the Power Query Editor.
In the Home tab of the Power Query Editor, click 'Merge Queries'. In the dialog box, select the same table from the dropdown menu to merge the table with itself.
Select the 'Site' and 'File Name' columns for both tables. Check the box labeled 'Use fuzzy matching to perform the merge'.
Expand the Fuzzy matching options. Set 'Ignore case' and 'Ignore spaces' to true. Adjust the 'Similarity Threshold' (e.g., 0.8) to balance precision and recall.
Click 'OK', then expand the merged column to count the matched rows. Any row with a match count greater than 1 has similar duplicates.
Use Advanced Excel Formulas for Text Normalization
Strip out unwanted suffixes, dates, and version numbers using Excel functions before performing standard duplicate checks.
Discover WPS Office for Your Data Management
If you are managing large datasets and looking for a lightweight, free alternative to Microsoft Office, WPS Office provides excellent spreadsheet functionalities. It offers seamless format compatibility, a familiar user interface, and powerful data processing capabilities without the heavy subscription fees.

Frequently Asked Questions
Why doesn't Excel's built-in Remove Duplicates feature work for this?
Excel's standard 'Remove Duplicates' tool requires exact character-by-character matches. It cannot recognize that 'File_v1.pdf' and 'File_final.pdf' are conceptually the same file, which is why fuzzy matching or text normalization is required.
What is a good similarity threshold for fuzzy matching file names?
A threshold between 0.75 and 0.85 is typically a good starting point. You may need to lower it if your file names have drastic variations, or raise it closer to 1.0 to prevent false positives where distinct files are wrongly grouped together.
Should I ignore file extensions when comparing duplicates?
Yes. It is highly recommended to strip the file extension (e.g., .pdf or .xlsx) using functions like TEXTBEFORE or Power Query delimiters before running any comparison, as variations in extensions can skew similarity scores.


