

Split Employee Benefits into Dynamic Columns with Excel Power Query

Question details
Create one row per employee with a dynamic set of columns for each benefit record.
- Product
- Microsoft Excel Power Query
- Device & OS
- not provided
- Scenario
- An employee benefits table contains multiple rows per employee, and the number of benefits may change over time.
- Observed behavior
- The desired output has one row per employee, with indexed columns for each benefit's date, plan, coverage level, employee cost, and employer cost.
Confirm that each benefit is on a separate row and that every row has an employee ID. The example uses an Excel table named Benefits with columns named Employee ID, Benefit Date, Plan, Coverage Level, Employee Cost, and Employer Cost.
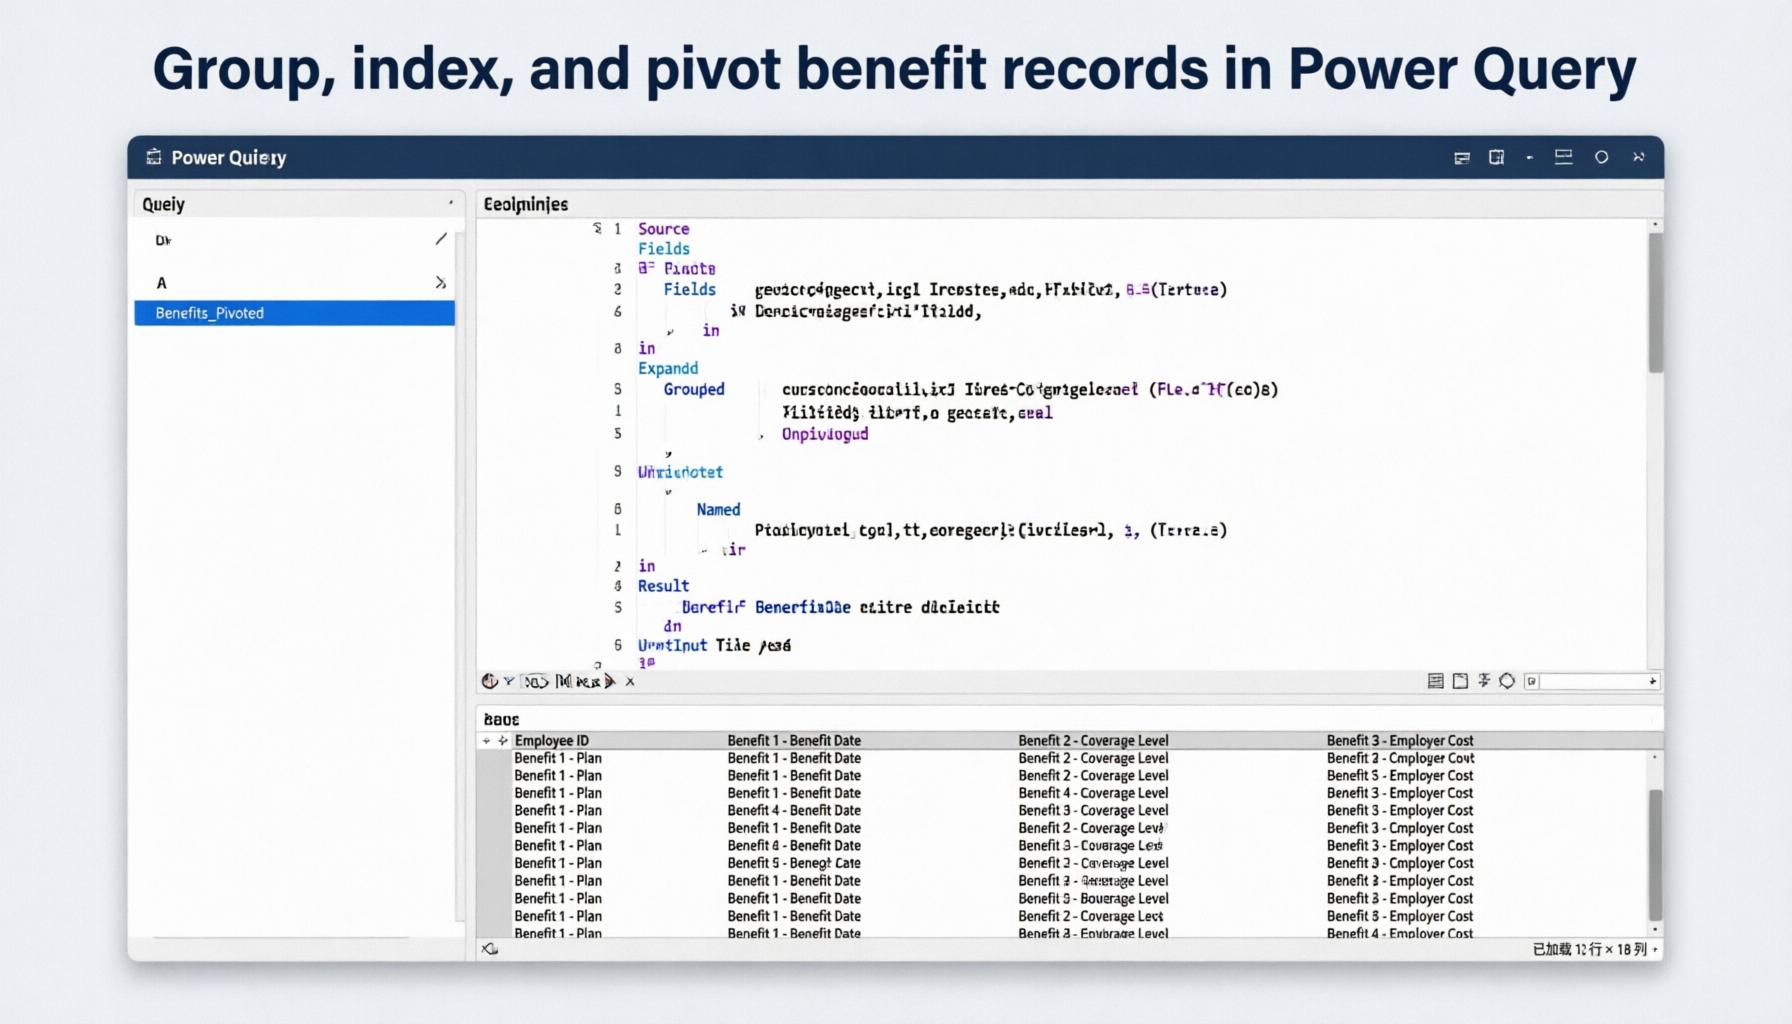
Group, index, and pivot benefit records in Power Query
Use this query to create numbered benefit columns that expand when employees have more benefit records.
The query groups records by employee ID, numbers the records within each group, and pivots each indexed field into a separate column. Column names combine the benefit number and field name, such as Benefit 1 - Plan.
Benefit numbering depends on the order of records within each group. If a benefit must retain the same number across refreshes, sort each group by a stable, unique benefit identifier before adding the index.
In Excel, select the benefit data and choose Insert > Table. On the Table Design tab, set the table name to Benefits. Match the six column names listed above or adjust them in the query.
Select a cell in the Benefits table and choose Data > From Table/Range. In Power Query Editor, choose Home > Advanced Editor.
Replace the Advanced Editor contents with the following code, then select Done: let Source = Excel.CurrentWorkbook(){[Name="Benefits"]}[Content], Fields = {"Benefit Date", "Plan", "Coverage Level", "Employee Cost", "Employer Cost"}, Grouped = Table.Group(Source, {"Employee ID"}, { {"Rows", each Table.AddIndexColumn(Table.SelectColumns(_, Fields), "BenefitIndex", 1, 1, Int64.Type), type table} }), Expanded = Table.ExpandTableColumn(Grouped, "Rows", List.Combine({Fields, {"BenefitIndex"}})), Unpivoted = Table.UnpivotOtherColumns(Expanded, {"Employee ID", "BenefitIndex"}, "Field", "Value"), Named = Table.AddColumn(Unpivoted, "ColumnName", each "Benefit " & Text.From([BenefitIndex]) & " - " & [Field], type text), PivotInput = Table.SelectColumns(Named, {"Employee ID", "ColumnName", "Value"}), Result = Table.Pivot(PivotInput, List.Distinct(PivotInput[ColumnName]), "ColumnName", "Value", List.First) in Result
Choose Home > Close & Load to place the result in Excel. After changing the source table, use Data > Refresh All and check the resulting columns and data types.
Review Employee Benefit Tables in WPS Spreadsheet
WPS Office is a free, lightweight alternative with a familiar spreadsheet interface. Open compatible Excel workbooks to review and edit benefit tables; WPS does not replace the Microsoft Power Query workflow described above.

Frequently Asked Questions
Will new benefit records create additional columns?
Yes. Add the records to the Benefits table and select Data > Refresh All. If an employee has more indexed benefit records than before, the query can create additional columns.
Why is a benefit field missing from the output?
Power Query's unpivot operation omits null values. If a particular indexed field is blank for every employee, its column may not be created. Check the source table and account for optional columns in downstream queries.
Can I keep benefit numbers consistent after a refresh?
Sort records within each employee group by a stable, unique benefit identifier before the AddIndexColumn operation. Without a stable sort, the same benefit may receive a different number after a refresh.
Will downstream queries continue to work when columns change?
Not necessarily. Queries and formulas that explicitly reference a missing or renamed benefit column can fail. Review those references after using Data > Refresh All and design downstream steps to handle optional columns.


