



How to Extract Text from PDFs in a SharePoint Folder using Power Automate

Question details
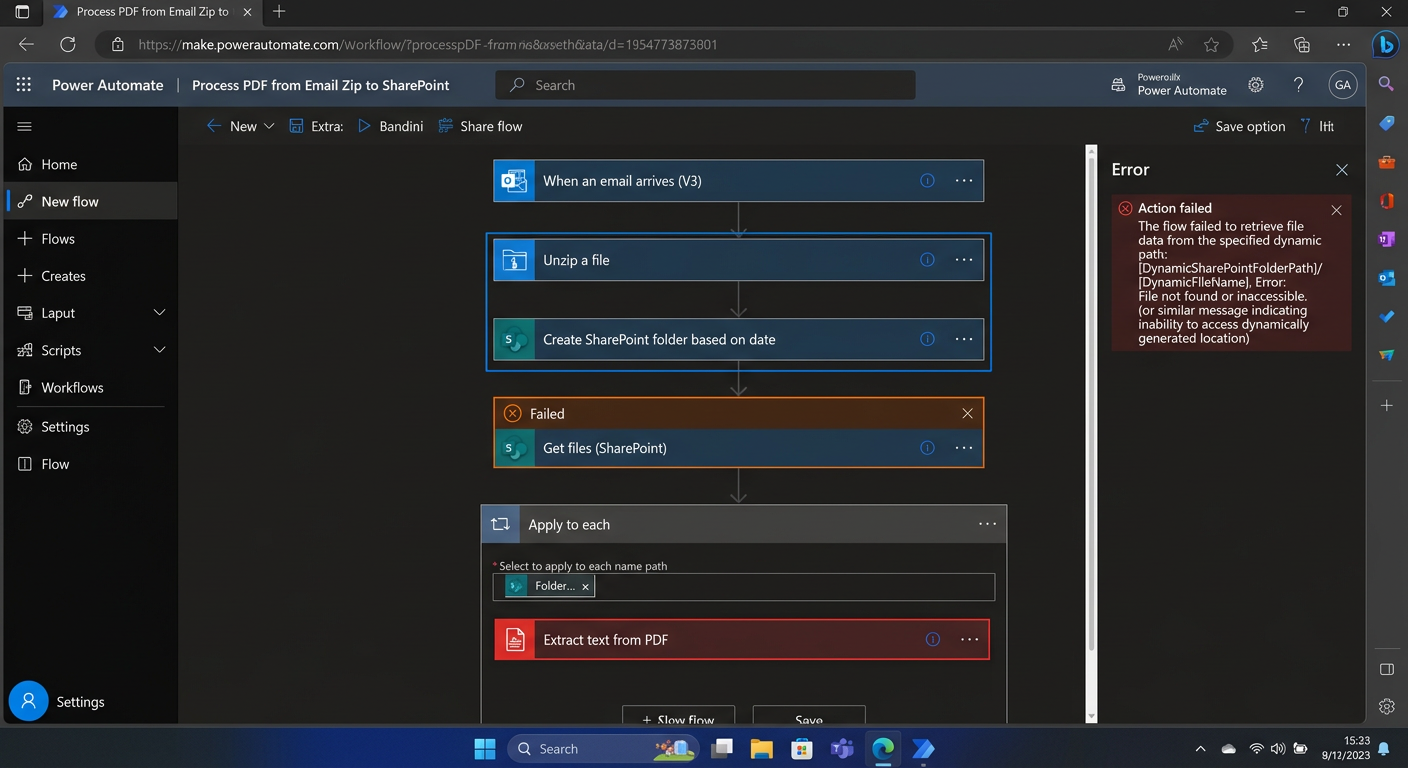
The user is experiencing issues extracting text from multiple PDF files stored in a newly created SharePoint folder using a Power Automate flow.
- Product
- Microsoft Power Automate, SharePoint
- Device & OS
- not provided
- Scenario
- Extracting text from PDFs that were derived from an emailed ZIP file and saved into a dynamically created SharePoint folder.
- Observed behavior
- The flow successfully extracts the PDFs from the ZIP and creates the destination folder, but it fails to process the PDFs and extract the text once they are stored in the SharePoint folder.
Verify that your Power Automate account has the correct permissions to access the SharePoint site and ensure that you have an active AI Builder license if you are using OCR for text extraction.
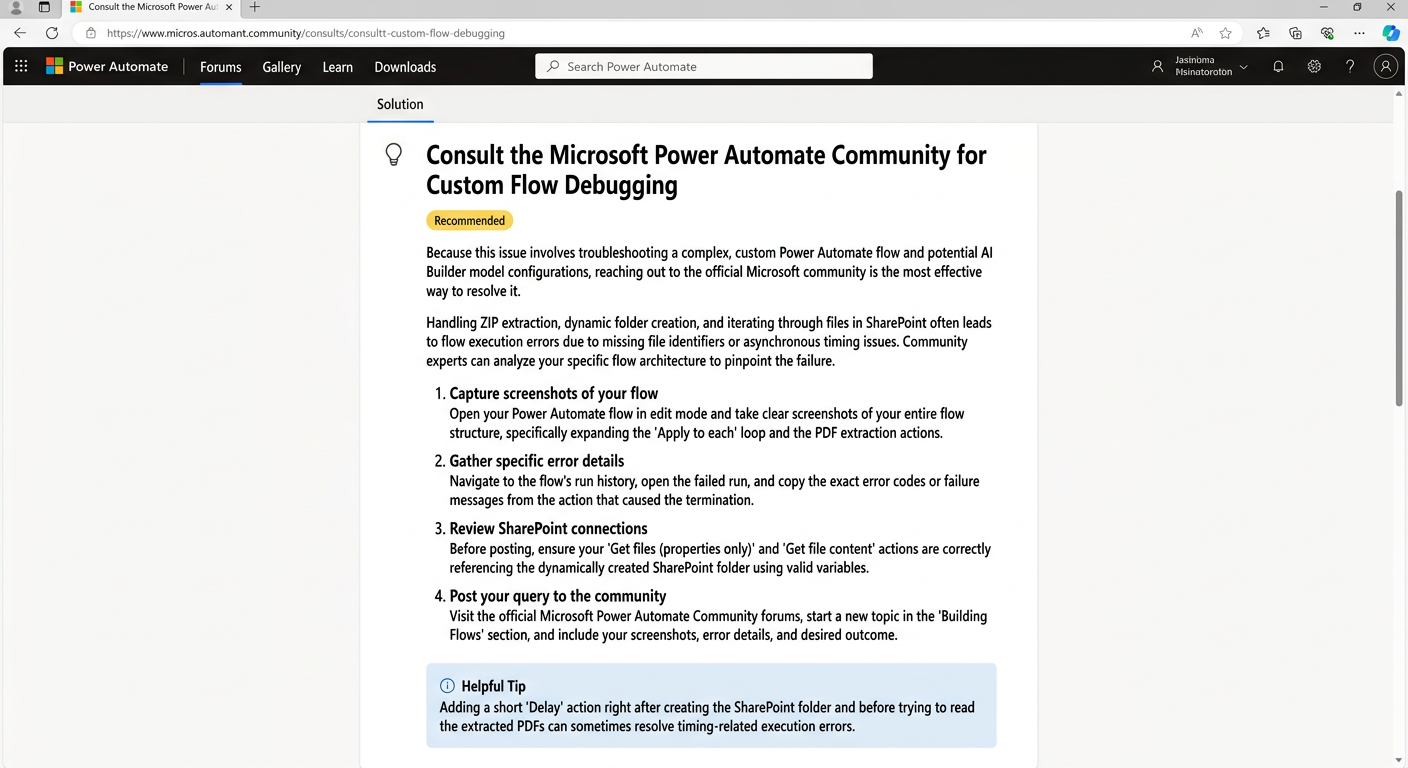
Consult the Microsoft Power Automate Community for Custom Flow Debugging
Because this issue involves troubleshooting a complex, custom Power Automate flow and potential AI Builder model configurations, reaching out to the official Microsoft community is the most effective way to resolve it.
Handling ZIP extraction, dynamic folder creation, and iterating through files in SharePoint often leads to flow execution errors due to missing file identifiers or asynchronous timing issues. Community experts can analyze your specific flow architecture to pinpoint the failure.
Open your Power Automate flow in edit mode and take clear screenshots of your entire flow structure, specifically expanding the 'Apply to each' loop and the PDF extraction actions.
Navigate to the flow's run history, open the failed run, and copy the exact error codes or failure messages from the action that caused the termination.
Before posting, ensure your 'Get files (properties only)' and 'Get file content' actions are correctly referencing the dynamically created SharePoint folder using valid variables.
Visit the official Microsoft Power Automate Community forums, start a new topic in the 'Building Flows' section, and include your screenshots, error details, and desired outcome.
Manage and Extract PDF Text Easily with WPS Office
While Power Automate is excellent for complex enterprise automation, occasionally you just need a straightforward way to extract text from PDFs or manage your documents. WPS Office is a lightweight, easy-to-use alternative to Microsoft Office that includes a powerful, built-in PDF toolkit. It allows you to seamlessly read, edit, and convert PDFs without complex flow configurations.
- 1. Open your PDF in WPS Office: Launch the WPS Office application and open the PDF file you synced from your SharePoint folder.
- 2. Access the PDF Tools: Navigate to the 'Tools' tab on the top ribbon to view all available PDF features.
- 3. Extract or Convert Text: Click on 'PDF to Word' or the text extraction tool to quickly convert the PDF content into an editable text format.
Frequently Asked Questions
Why does my Power Automate flow fail to read PDFs from a newly created SharePoint folder?
This typically happens due to asynchronous timing issues where the flow tries to read the files before SharePoint has finished indexing them. It can also occur if incorrect dynamic content (like the wrong File Identifier) is mapped in the 'Get file content' action. Adding a 'Delay' action can often solve timing issues.
Do I need AI Builder to extract text from a PDF in Power Automate?
If the PDF contains scanned images instead of native text, you will need AI Builder's OCR capabilities to extract it. If it is a native text PDF, you might be able to use third-party premium connectors like Encodian or Adobe PDF Services without relying on AI Builder.
How can I extract text from PDFs manually without using Power Automate?
You can use a comprehensive office suite like WPS Office to handle PDFs manually. By opening the document in WPS PDF, you can directly select and copy text, or use the built-in 'PDF to Word' converter to extract all the text accurately into an editable document.


