

Best Computer Specifications for Processing Large Scanned PDFs

Question details
The user needs hardware recommendations to improve processing and OCR speed when handling massive scanned PDF documents with hundreds or thousands of pages.
- Product
- PDF Software
- Device & OS
- not provided
- Scenario
- Running Optical Character Recognition (OCR) on large, multi-page scanned PDF files.
- Observed behavior
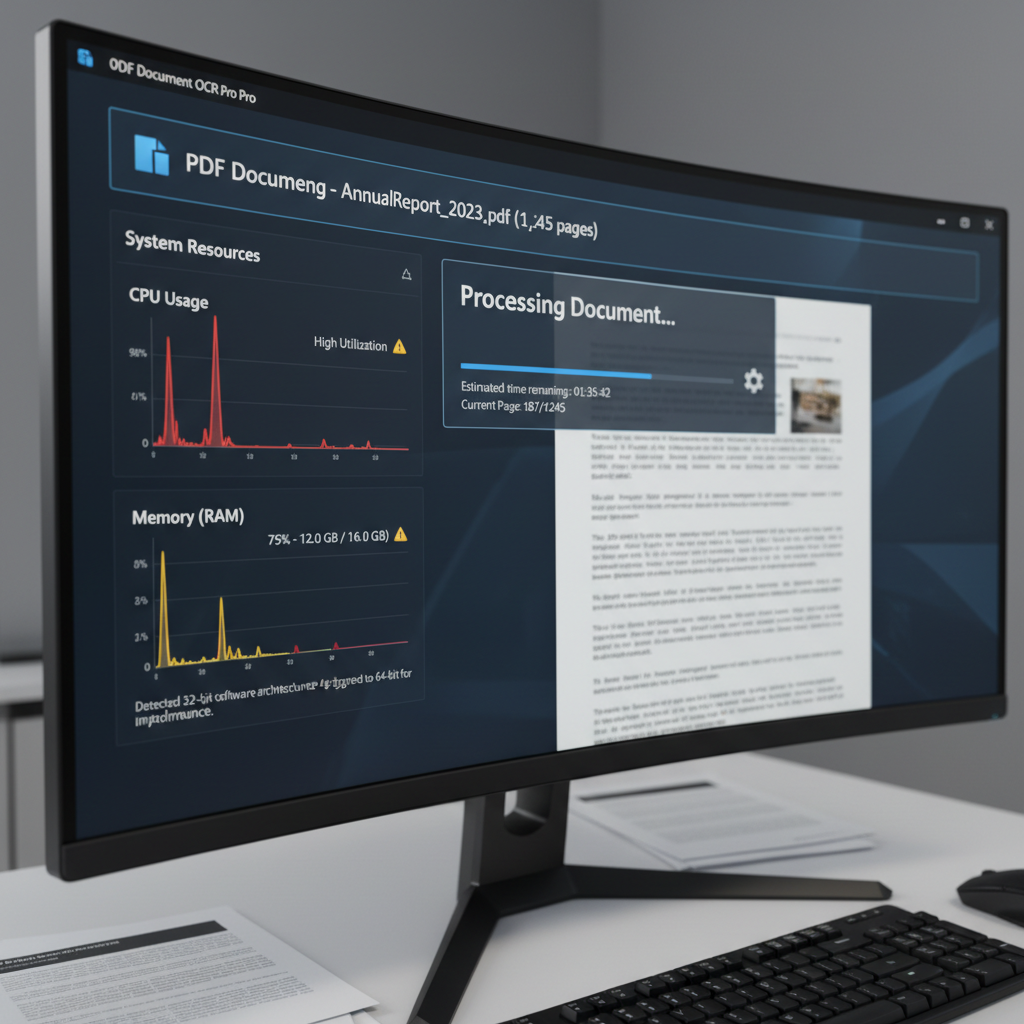
- OCR processing is unacceptably slow due to hardware bottlenecks and 32-bit software architecture limitations.
Before investing in expensive hardware upgrades, verify whether your current PDF software is a 32-bit or 64-bit application, as 32-bit architecture will restrict hardware utilization regardless of how powerful your computer is.
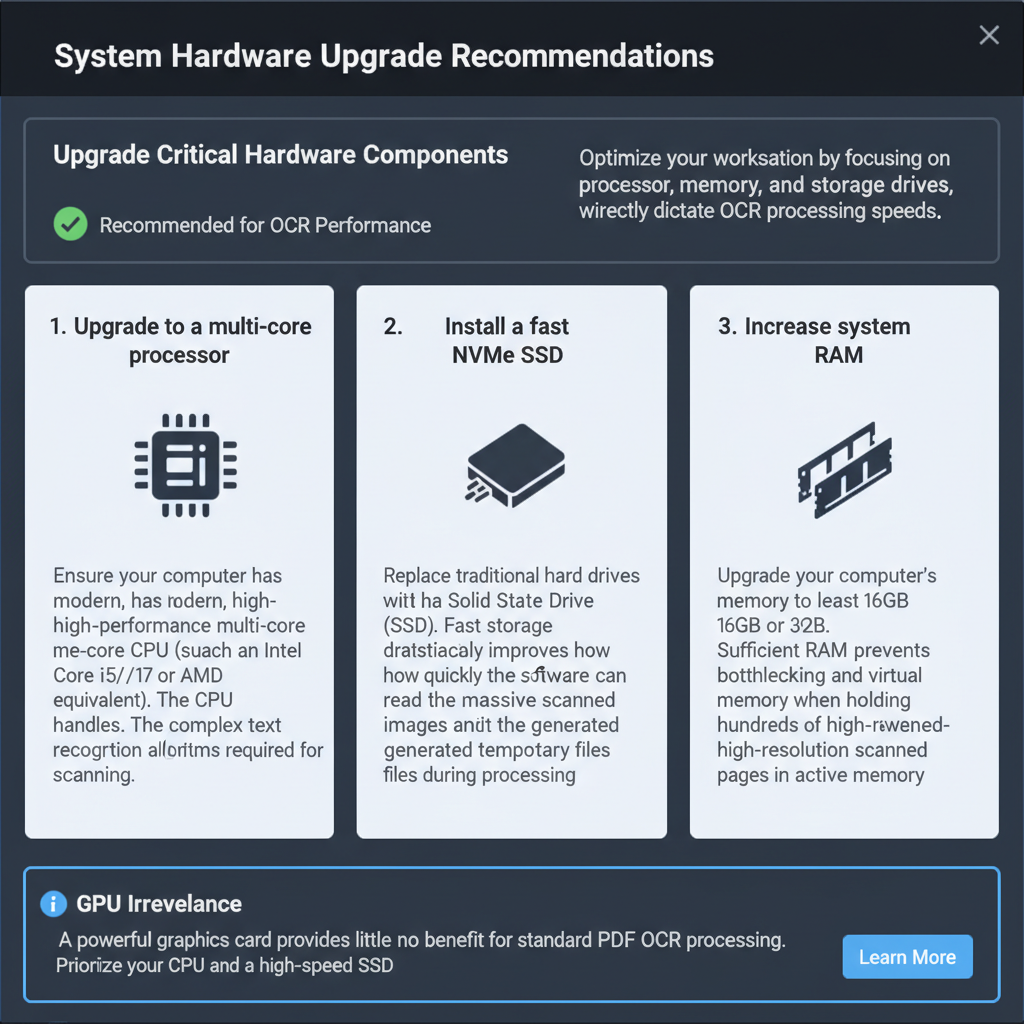
Upgrade Critical Hardware Components
Optimize your workstation by focusing on the processor, memory, and storage drives, which directly dictate OCR processing speeds.
OCR processing for dense documents is highly dependent on the central processor and storage read/write speeds. Unlike video rendering, OCR algorithms in standard PDF software do not utilize the graphics card (GPU).
Ensure your computer has a modern, high-performance multi-core CPU (such as an Intel Core i5/i7 or AMD Ryzen equivalent). The CPU handles the complex text recognition algorithms required for scanning.
Replace traditional hard drives with a Solid State Drive (SSD). Fast storage drastically improves how quickly the software can read the massive scanned images and write the generated temporary files during processing.
Upgrade your computer's memory to at least 16GB or 32GB. Sufficient RAM prevents system bottlenecking and virtual memory swapping when holding hundreds of high-resolution scanned pages in active memory.
Bypass Software Limitations by Batch Processing
Prevent crashes and memory overload in 32-bit PDF applications by splitting large workloads into manageable chunks.
Process Large Scanned PDFs Fast with WPS Office
If legacy 32-bit PDF software is slowing down your workflow, WPS Office provides a highly optimized, lightweight PDF editor equipped with advanced OCR capabilities that efficiently utilizes modern system resources.
- 1. Launch WPS PDF: Download and open WPS Office, then select the 'PDF' tab on the home screen to launch the dedicated PDF editor.
- 2. Open your scanned document: Click 'Open' and locate your large scanned PDF file. WPS PDF will load the document quickly using optimized rendering.
- 3. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button to open the text recognition panel.
- 4. Configure extraction settings: Choose whether you want to convert the scan into a searchable PDF or extract it into a completely editable document. You can also specify a page range to process in smaller batches if preferred.
- 5. Extract the text: Click 'Extract' or 'Recognize' to let the WPS OCR engine process the document. Save your newly searchable file once complete.

Frequently Asked Questions
Why does a powerful graphics card (GPU) not speed up PDF OCR?
Most standard PDF processing applications, including Acrobat, rely strictly on the CPU for character recognition algorithms. Because they are not programmed to utilize hardware acceleration, the GPU sits idle during OCR tasks.
Why does my PDF software struggle with very large scanned documents despite having good hardware?
Many older or standard PDF applications operate on a 32-bit architecture. This limits the software to utilizing a maximum of 4GB of RAM, creating artificial bottlenecks even if your computer has 16GB or 32GB installed.
Is it better to upgrade my RAM or my SSD for processing massive PDFs?
Both are critical, but upgrading from a mechanical Hard Drive (HDD) to an NVMe Solid State Drive (SSD) offers the most dramatic performance boost. OCR processing requires rapidly writing and reading gigabytes of temporary data, which an SSD handles exponentially faster.
How can I process thousands of PDF pages without my software crashing?
The most reliable method is to use the 'Split PDF' function in your editor to divide the massive file into segments of 100 pages. Run the OCR process on each smaller file independently, then merge them back together when finished.


