

Can Acrobat JavaScript Automate OCR on Scanned PDFs?

Question details
The user wants to know if they can use JavaScript within Adobe Acrobat to automatically perform Optical Character Recognition (OCR) on scanned PDF documents.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Automating text recognition workflows for scanned document images converted to PDF.
- Observed behavior
- Acrobat's JavaScript API does not fully expose OCR features, preventing complete workflow automation via scripts for formats like PNG or JPEG.
Verify your scanned document file formats, as Adobe Acrobat handles OCR triggers differently depending on whether the source image is a TIFF, PNG, or JPEG.
Use TIFF Format for Automatic OCR Conversion
Scanning documents as TIFF files can automatically trigger Acrobat's PDF conversion and OCR processes without requiring custom JavaScript.
Because JavaScript cannot guarantee access to Acrobat's OCR engine, utilizing built-in format triggers is the best workaround for reducing manual steps.
Configure your physical scanner to save the output document directly as a TIFF file rather than a PNG or JPEG.
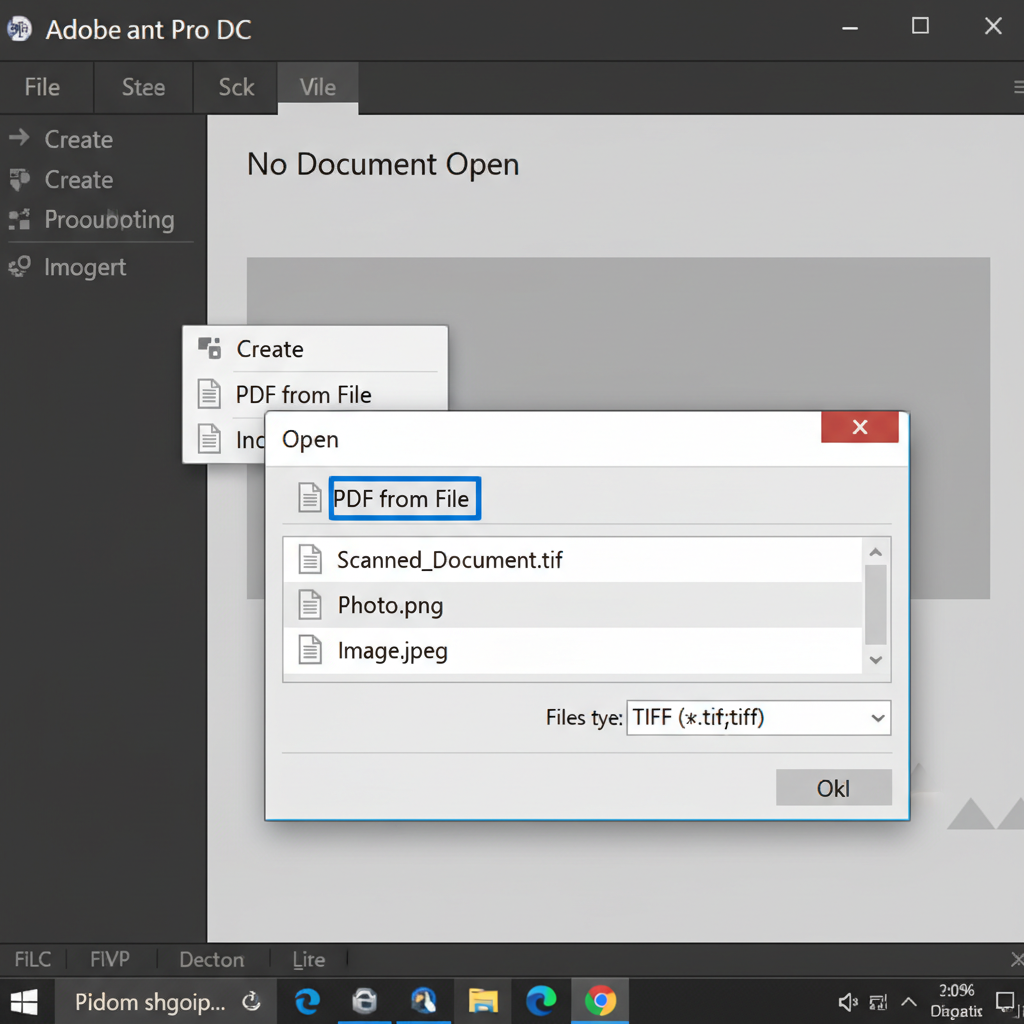
Launch Adobe Acrobat, go to 'File', select 'Create', and choose 'PDF from File' to open the saved TIFF document.
Wait for Acrobat to automatically convert the TIFF file into a PDF. In many setups, this action will implicitly initiate the built-in OCR process.
Perform Manual OCR on PNG or JPEG Scans
Since JavaScript cannot fully automate OCR for PNG and JPEG formats, you must trigger the text recognition manually using Acrobat's built-in tools.
Easily Extract Text from Scanned PDFs with WPS Office
Instead of relying on complex JavaScript workarounds or inconsistent file format triggers, use WPS Office to quickly perform Optical Character Recognition (OCR) on any scanned PDF, image, or document.
- 1. Open your file in WPS Office: Launch WPS Office and open your scanned PDF or image file.
- 2. Access the OCR tool: Navigate to the 'Tools' tab on the top ribbon and select 'OCR' to open the text extraction panel.
- 3. Extract and save text: Select the specific area or pages you want to recognize, choose your desired output format (such as a Word document or plain text), and click 'Extract'.

Frequently Asked Questions
Why doesn't Adobe Acrobat JavaScript fully support OCR automation?
Acrobat's JavaScript API is primarily designed for form handling, calculations, and basic document manipulation. Security and architecture constraints prevent scripts from silently running complex, resource-heavy application features like OCR without direct user interaction.
Can I batch process OCR on multiple PDFs using JavaScript?
Because JavaScript cannot reliably trigger the OCR workflow in Acrobat, automating batch OCR is better handled using Acrobat Pro's 'Action Wizard' tool, which allows you to sequence built-in commands natively rather than writing custom scripts.
Does the file format affect how Acrobat applies OCR?
Yes. Opening a scanned TIFF file in Acrobat often triggers an automatic PDF conversion and OCR process natively. Conversely, standard PNG or JPEG files converted to PDF usually require you to initiate the text recognition workflow manually.


