

Can Adobe ExportPDF Extract Russian or Belarusian Text?
Question details
The user needs to convert scanned PDF documents containing Russian or Belarusian text into an editable Word format using Optical Character Recognition (OCR).
- Product
- Adobe ExportPDF
- Device & OS
- not provided
- Scenario
- Attempting to use Adobe ExportPDF to perform OCR and export scanned documents written in Russian or Belarusian.
- Observed behavior
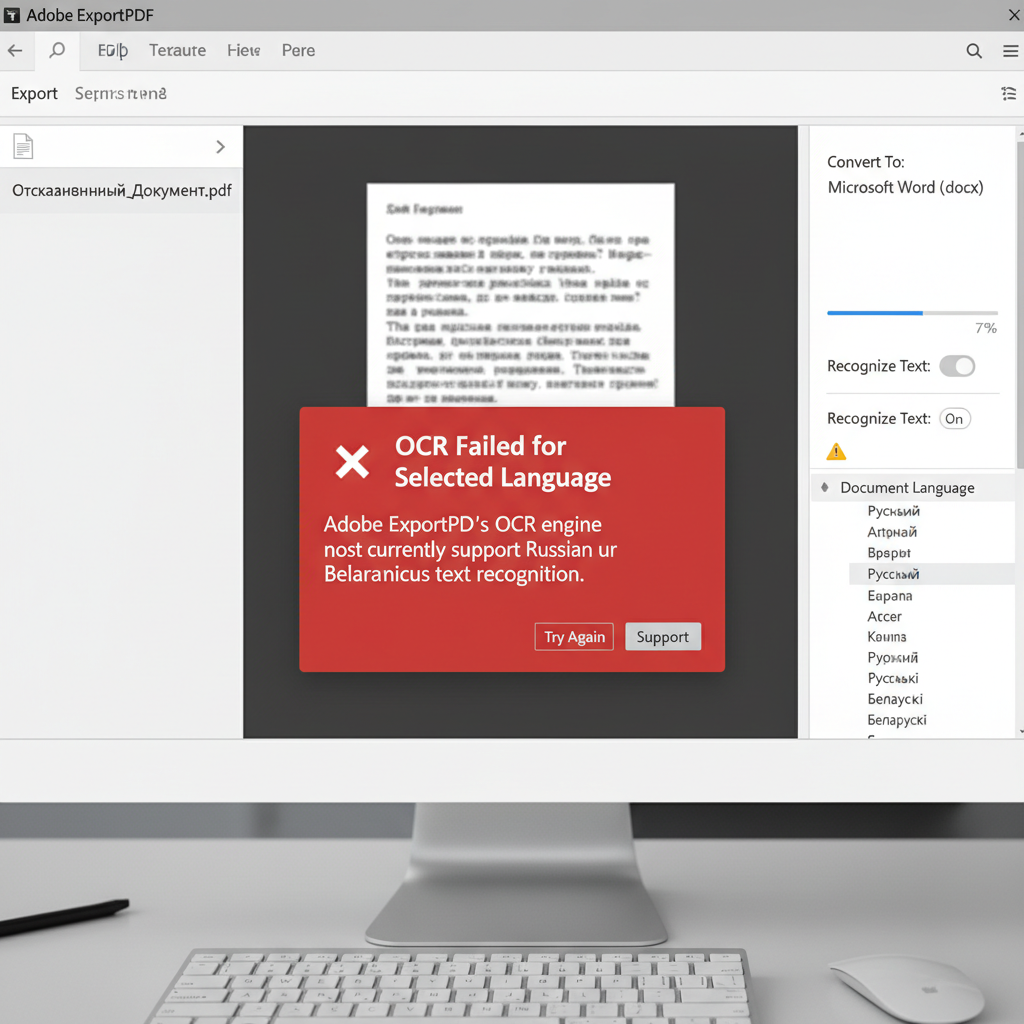
- Adobe ExportPDF fails to recognize and extract the text because its OCR engine currently does not support the Russian or Belarusian languages.
Verify whether your PDF document contains scanned images of text or actual digital text. If the text can be highlighted with your cursor, it is already selectable and standard PDF-to-Word conversion tools will work without requiring OCR.
Use Adobe Acrobat Pro for Russian OCR Recognition
Since Adobe ExportPDF lacks OCR support for Russian and Belarusian, you must use the full desktop version of Adobe Acrobat to perform text recognition for these languages.
Adobe Acrobat includes a more comprehensive OCR engine that supports a wider variety of languages, including Russian. By processing the document through Acrobat, you can successfully export the scanned file into an editable Microsoft Word document.
Launch Adobe Acrobat on your computer and open the scanned PDF file that contains the Russian or Belarusian text.
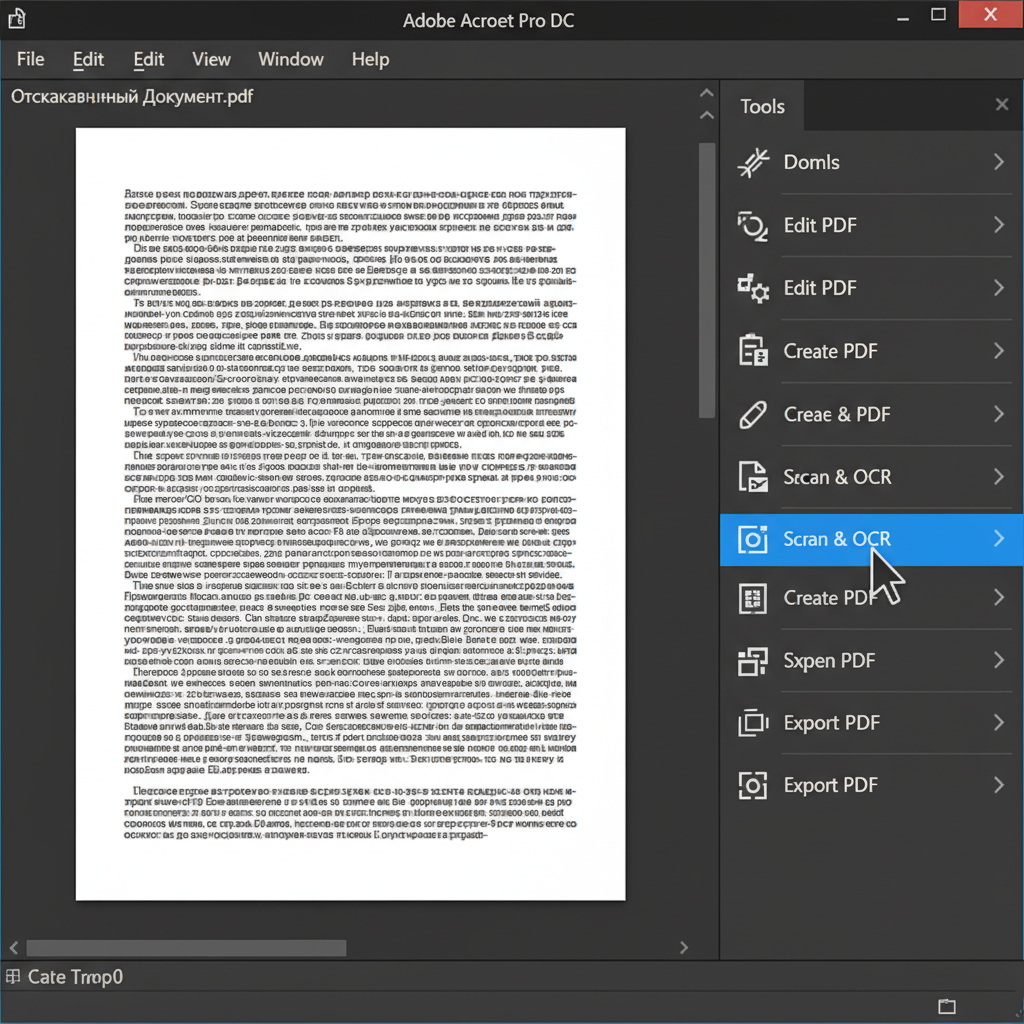
Navigate to the right-hand tool pane and click on 'Scan & OCR'. In the toolbar that appears, select 'Recognize Text' and choose 'In This File'.
Click on the 'Settings' gear icon in the Recognize Text menu. Under the Document Language dropdown, select 'Russian', and then click 'Recognize Text' to begin the process.
Once the OCR process is complete, go to the top menu and click 'File' > 'Export To' > 'Microsoft Word' > 'Word Document'. Save the file to your desired location.
Use WPS Office to OCR and Convert Scanned PDFs
WPS Office offers a comprehensive and lightweight PDF toolkit equipped with advanced OCR capabilities. You can quickly extract text from scanned documents and save them as fully formatted Word files without needing heavy standalone PDF software.
- 1. Launch WPS PDF: Open WPS Office on your computer and click the 'PDF' tab on the home screen to launch the PDF reader.
- 2. Open your scanned document: Click 'Open' and select the scanned PDF file containing the text you want to extract.
- 3. Access the OCR feature: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button to open the text recognition panel.
- 4. Extract and save to Word: Follow the on-screen prompts to extract the text. Once recognized, click 'Save as Document' to export the result as an editable Word file.

Frequently Asked Questions
Why doesn't Adobe ExportPDF recognize my Russian document?
Adobe ExportPDF uses a limited OCR engine that only supports a specific list of common languages. Currently, Russian and Belarusian are not included in the ExportPDF supported language list.
Do I need OCR to convert a Russian PDF to Word?
You only need OCR (Optical Character Recognition) if your PDF was created from a scanner or is an image. If the PDF was originally saved from a word processor and the text is highlightable, standard conversion tools can export the Russian text directly without OCR.
What happens if I try to OCR a Russian PDF with the wrong language setting?
If your OCR engine is set to English while processing a Russian document, the software will attempt to match the Cyrillic characters to English letters, resulting in a document filled with gibberish and incorrect symbols.


