

Can You Train Adobe Acrobat OCR for Special Fonts? (Answered)

Question details
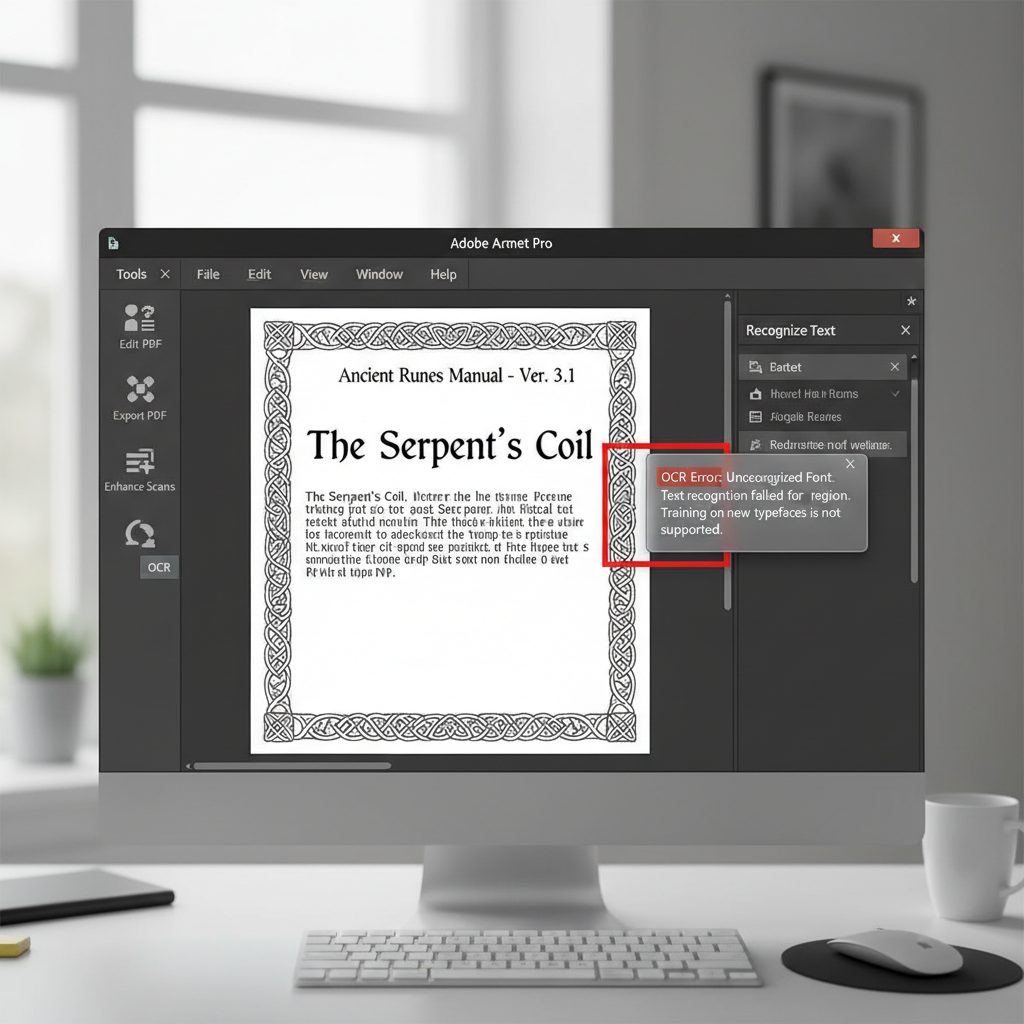
The user needs to know if Adobe Acrobat's built-in OCR engine can be trained to correctly recognize custom or specialized fonts that it repeatedly misreads.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Attempting to extract text or make a scanned PDF document searchable when the document utilizes a highly specialized, non-standard font.
- Observed behavior
- Adobe Acrobat repeatedly misreads the custom lettering because it currently lacks a built-in feature to train its OCR engine on new or unrecognized typefaces.
Before exploring alternative software, ensure your PDF scan is of the highest possible resolution (at least 300 DPI) and has strong contrast, as poor image quality is a primary cause of OCR errors even with standard fonts.
Understand Acrobat's OCR Limitations and Improve Scan Quality
Adobe Acrobat does not support manual OCR pattern training for custom fonts. You must rely on improving the source document quality or manually correcting errors.
Because Acrobat relies on a pre-programmed dictionary of standard fonts, it cannot 'learn' new character shapes natively. If you must use Acrobat, your best approach is optimizing the document before recognition.
Re-scan your physical document at a higher resolution (e.g., 600 DPI) to give the Acrobat OCR engine the clearest possible shapes to analyze.
Enhance the brightness and contrast of the scanned image before running it through Acrobat OCR to make the specialized font stand out from the background.
After running standard OCR in Acrobat, manually review the document. Use the 'Edit PDF' tool to find misread characters and manually type the correct letters.
Use Advanced Third-Party OCR Software with Training Capabilities
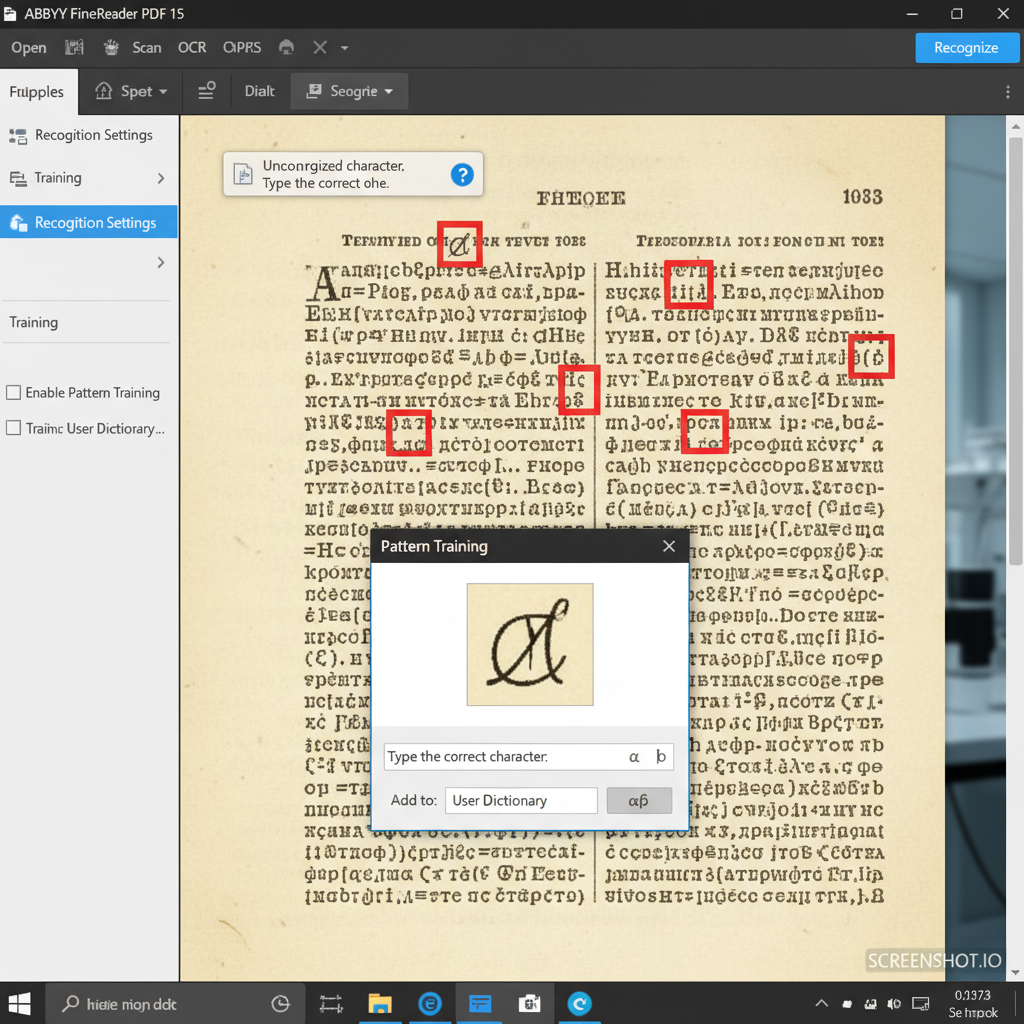
Since Acrobat cannot be trained, the best solution for extensive specialized fonts is utilizing dedicated OCR software like ABBYY FineReader that includes explicit pattern training features.
Use WPS Office for Highly Accurate PDF OCR Text Extraction
While manual font training requires specialized pattern software, WPS PDF offers a highly accurate, built-in OCR engine that natively recognizes a vast array of fonts and complex layouts. You can easily extract text from scanned documents or convert them directly to editable Word files with minimal hassle.
- 1. Open the PDF in WPS Office: Launch WPS Office and open your scanned PDF document.
- 2. Access the OCR Tool: Navigate to the 'Tools' tab and select the 'OCR' button to initiate text recognition.
- 3. Choose Extraction Mode: Select whether you want to extract the text directly to your clipboard or convert the scanned page into a fully editable Word document.
- 4. Edit and Save: Review the extracted text, make any necessary adjustments to stylized lettering, and save your newly editable file.

Frequently Asked Questions
Why does Adobe Acrobat OCR struggle with special fonts?
Acrobat's OCR engine uses a pre-built dictionary and pattern recognition system optimized for standard, widely-used fonts. When it encounters highly stylized, handwritten, or custom typefaces, it lacks the reference data needed to accurately match the character shapes.
Can I add new fonts to my computer to improve Acrobat's OCR?
Installing a custom font on your system allows you to type or edit text in that font within Acrobat, but it does not update or train Acrobat's internal OCR engine to recognize those specific shapes during the scanning and text-recognition process.
What is OCR pattern training?
Pattern training is an advanced feature found in specialized OCR software (like ABBYY FineReader) that allows users to manually link a specific, unrecognized image shape to a text character. This creates a custom dictionary that the software uses to correctly identify the font in future document scans.
Does WPS Office support PDF OCR text extraction?
Yes, WPS Office includes a robust PDF editor equipped with high-accuracy OCR capabilities. It allows you to easily convert scanned images and static PDFs into fully editable Word, Excel, or plain text documents.


