

Fix Acrobat Crashes During OCR on a Specific PDF Page

Question details
The user needs to resolve an issue where the PDF software consistently crashes when performing Optical Character Recognition (OCR) on a specific page of a document.
- Product
- PDF / Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Running OCR to convert scanned PDF pages into editable or searchable text.
- Observed behavior
- The application crashes or freezes at the exact same page every time OCR is initiated, indicating page-level corruption or unsupported objects.
Before modifying, deleting, or extracting any pages, ensure you have created a backup copy of your original PDF document to prevent accidental data loss during troubleshooting.
Isolate and Rebuild the Corrupted Page
Extract the problematic page to test it individually, then recreate it using a clean image format to eliminate file corruption.
Consistent crashes on a single page usually point to hidden corruption, damaged image data, or unusual encoding. By recreating the page as a clean image, you can strip away the errors causing the OCR engine to fail.
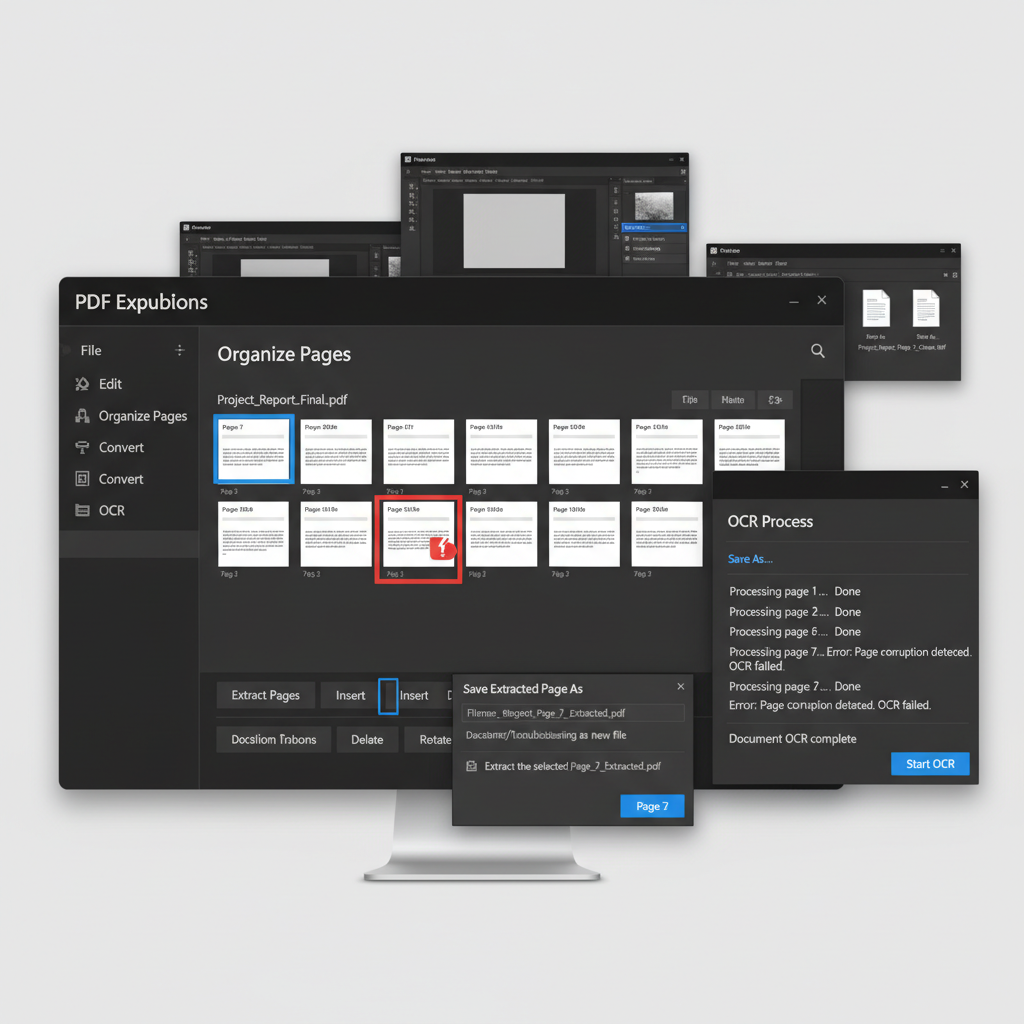
Use your PDF editor's organize pages tool to extract the specific page causing the crash and save it as a standalone file.
Run the OCR process on this newly extracted single-page PDF to verify if it is indeed the source of the software crash.
Open the source page in an image editing software like Photoshop, and save it as a high-quality TIFF or PNG image file.
Convert the clean TIFF image back into a PDF file, insert it into your original document to replace the damaged page, and run the OCR process again.
Process the PDF Document in Smaller Batches
Split the document into smaller sections to bypass the problematic page and successfully run OCR on the healthy parts of the file.
Use WPS PDF to Perform OCR Without Crashing
If your current software continually crashes due to complex or corrupted PDF pages, try the highly stable OCR engine in WPS Office to accurately extract and convert text without freezing.
- 1. Open your PDF: Launch WPS Office and open the PDF document you want to recognize.
- 2. Select the OCR tool: Navigate to the Tools tab on the top ribbon and click on the 'OCR' button.
- 3. Choose extraction mode: Select whether you want to extract the text to a standard document format or convert the file into a searchable PDF.
- 4. Process the document: Click 'Start' to allow WPS PDF to analyze the pages and output the recognized text smoothly.

Frequently Asked Questions
Why does my PDF software crash on only one specific page during OCR?
A specific page may contain corrupted image data, unusual font encoding, or unsupported PDF objects. When the OCR engine attempts to process this malformed data, it encounters an error it cannot bypass, causing the software to crash.
What is the best image format for rebuilding a corrupted PDF page?
Saving the problematic page as a high-resolution TIFF file is highly recommended. TIFF is an uncompressed or losslessly compressed format that maintains text clarity for OCR while stripping away any hidden code errors that existed in the original PDF object.
Can I skip a corrupted page during the OCR process?
Yes, most professional PDF editors allow you to specify a page range for OCR. Alternatively, you can temporarily extract or delete the corrupted page, run OCR on the remaining document, and then merge the missing page back in later.


