

Fix Acrobat PDF Search Finding Incorrect or Missing Text
Question details
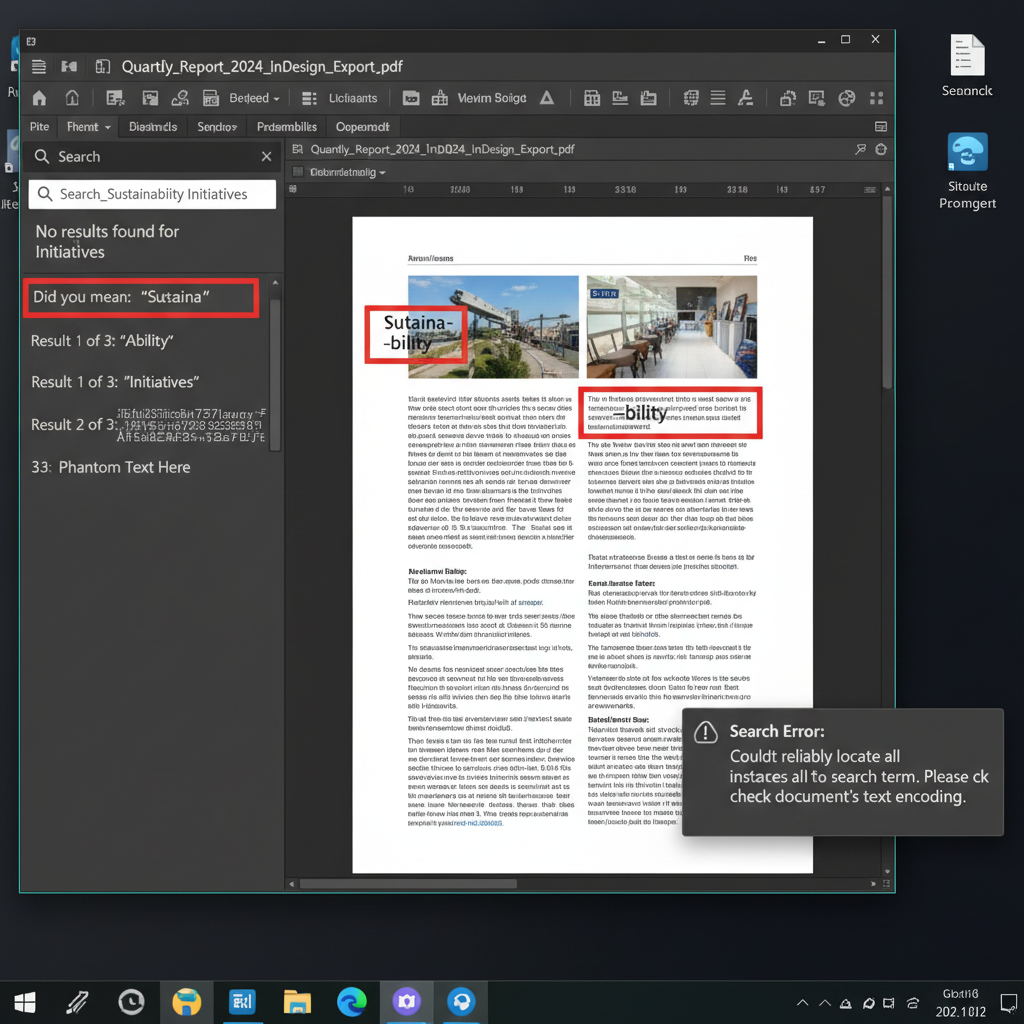
The user is experiencing issues where searching for text within a PDF yields incorrect results, split words, or phantom text.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Searching for specific text in a PDF document exported from Adobe InDesign.
- Observed behavior
- The PDF search function fails to locate correct text, returns missing text, or identifies split and phantom words.
Verify whether the text search issue occurs in all your PDF files or just a specific document, and ensure your PDF reader is updated to the latest version.
Verify File Integrity and Update the PDF Reader
Determine if the search issue is file-specific and ensure your software contains the latest bug fixes.
Search functionality relies heavily on a clean, readable text layer. If only one file is affected, the document's text layer may be corrupted or improperly formatted during export.
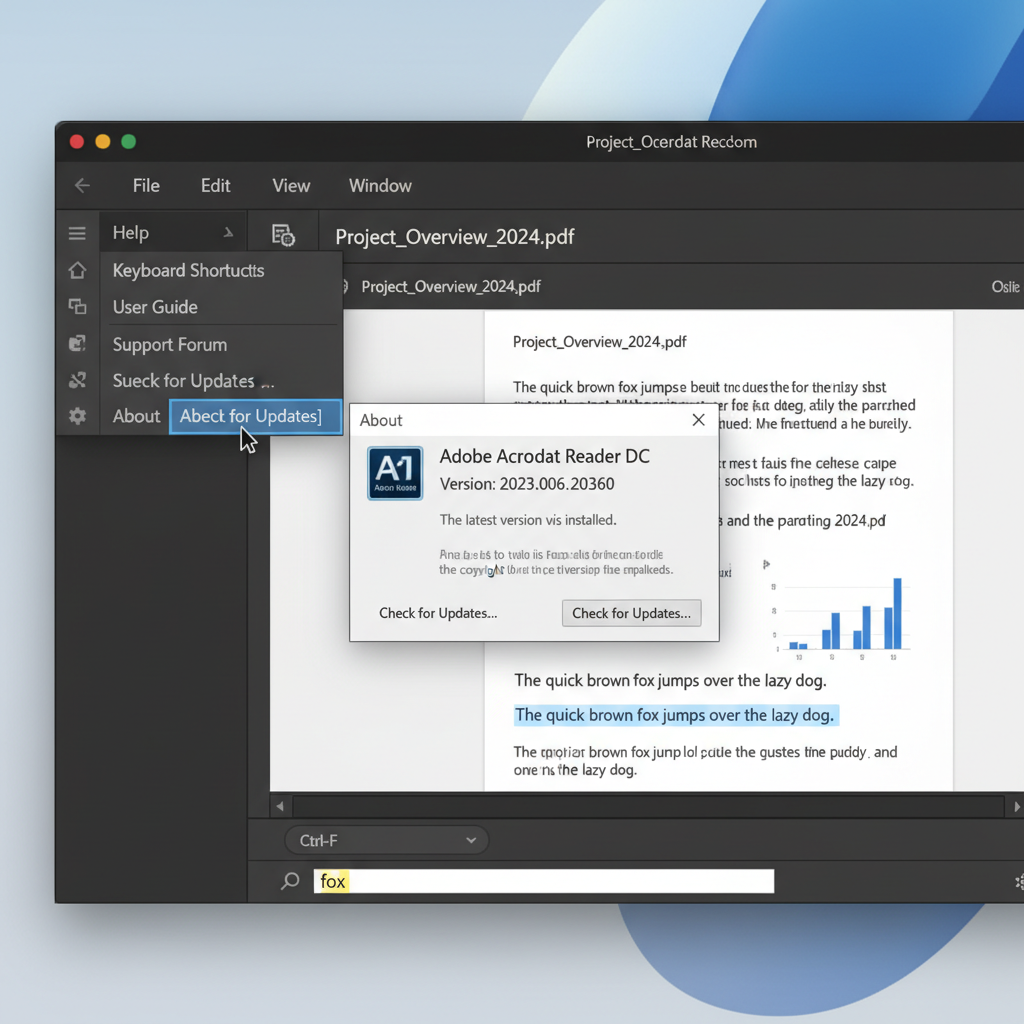
Navigate to the Help menu in your PDF reader and select 'About' to check if you are running the latest version. Update if necessary.
Open a completely different PDF file and perform a text search using Ctrl+F (or Cmd+F) to see if the issue persists across all documents.
Use your cursor to highlight a few sentences. Paste them into a standard text editor. If the text appears as gibberish or contains strange spaces, the document's text layer is corrupted.
Recreate the PDF with Adjusted Export Settings
Exporting the PDF again with optimized settings can fix underlying text layer anomalies generated by InDesign.
Easily Search and OCR PDFs with WPS Office
If your PDF text is unsearchable due to formatting issues or corrupted text layers, WPS Office offers an advanced PDF reader with a powerful built-in OCR (Optical Character Recognition) tool to recognize and search text accurately.
- 1. Open the document in WPS PDF: Launch WPS Office and open your problematic PDF file.
- 2. Initiate a text search: Press Ctrl + F to bring up the search bar and type your keyword to test the existing text layer.
- 3. Use the OCR feature: If the text is unsearchable or returning phantom words, go to the 'Tools' tab and click on the 'OCR' button.
- 4. Convert and search: Extract the text or convert the document to a fully searchable PDF format, then retry your search.

Frequently Asked Questions
Why does my PDF search find phantom text or split words?
This typically occurs when a PDF is exported with overlapping text layers, misaligned fonts, or complex vector objects that interfere with the text metadata. Re-exporting the file or running OCR can help resolve this.
How can I tell if my PDF has a searchable text layer?
Try selecting the text with your mouse pointer. If you can highlight individual words and copy them into a basic text editor correctly, the text layer is intact. If you highlight a large block like an image, the file is flattened.
Can OCR fix incorrect PDF search results?
Yes. If the original text layer is corrupted, missing, or improperly exported from a design program, running Optical Character Recognition (OCR) scans the visual text and generates a fresh, accurate text layer for searching.


