

How to Fix Acrobat Search Finds No Text in a PDF
Question details
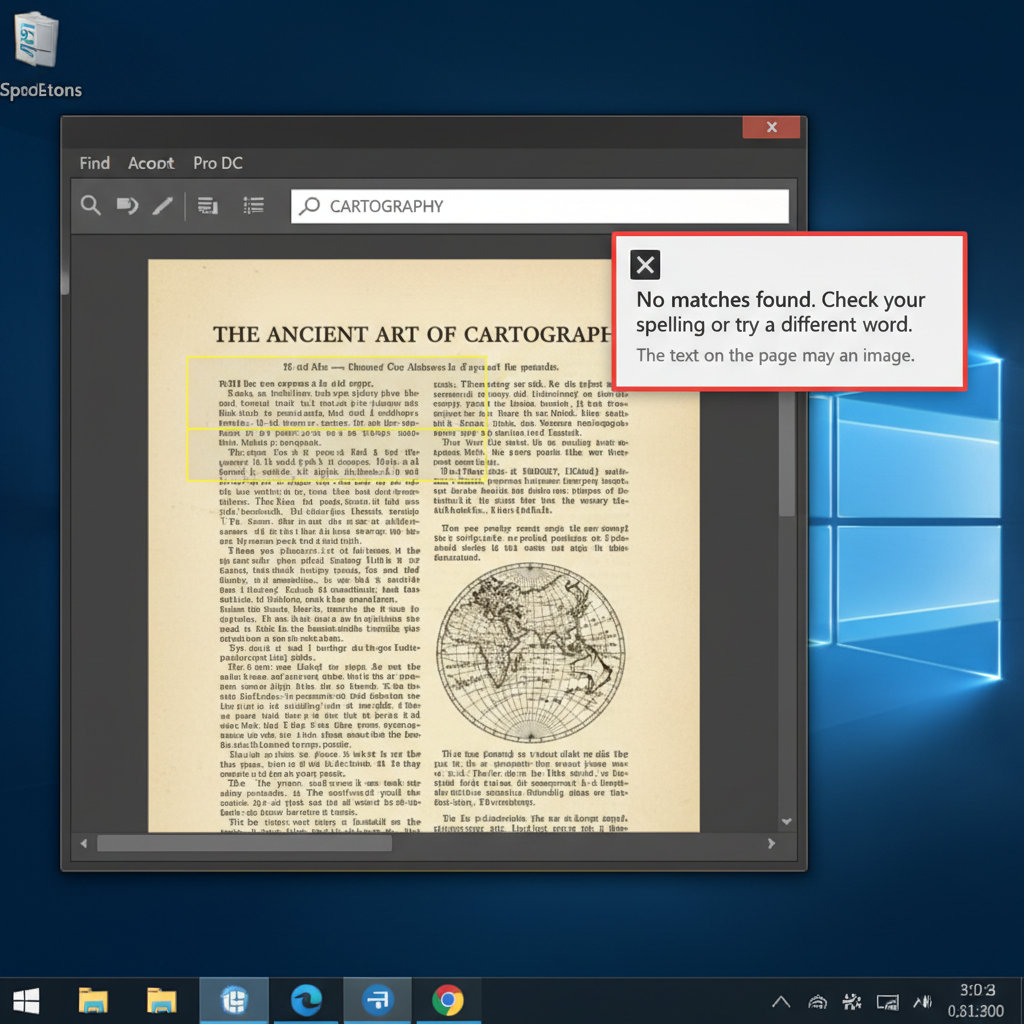
The user is unable to find visible text using the search function in a PDF document.
- Product
- Adobe Acrobat
- Device & OS
- not provided
- Scenario
- Searching for specific words or phrases within a PDF document to quickly locate information.
- Observed behavior
- Acrobat returns a 'no matches found' message despite the text appearing clearly visible on the page, often because the file is a scanned image or contains corrupted text encoding.
Before proceeding, attempt to highlight the text with your cursor. If the entire page is selected at once, your document is a scanned image rather than a text-based file.
Convert Scanned Images to Selectable Text using OCR
Use this method if the PDF is a scanned image and the text cannot be highlighted or copied.
Search functions rely on digital text layers to find matches. If your PDF was created via a scanner, it consists entirely of images. You must apply Optical Character Recognition (OCR) to extract and convert those images into readable, searchable text.
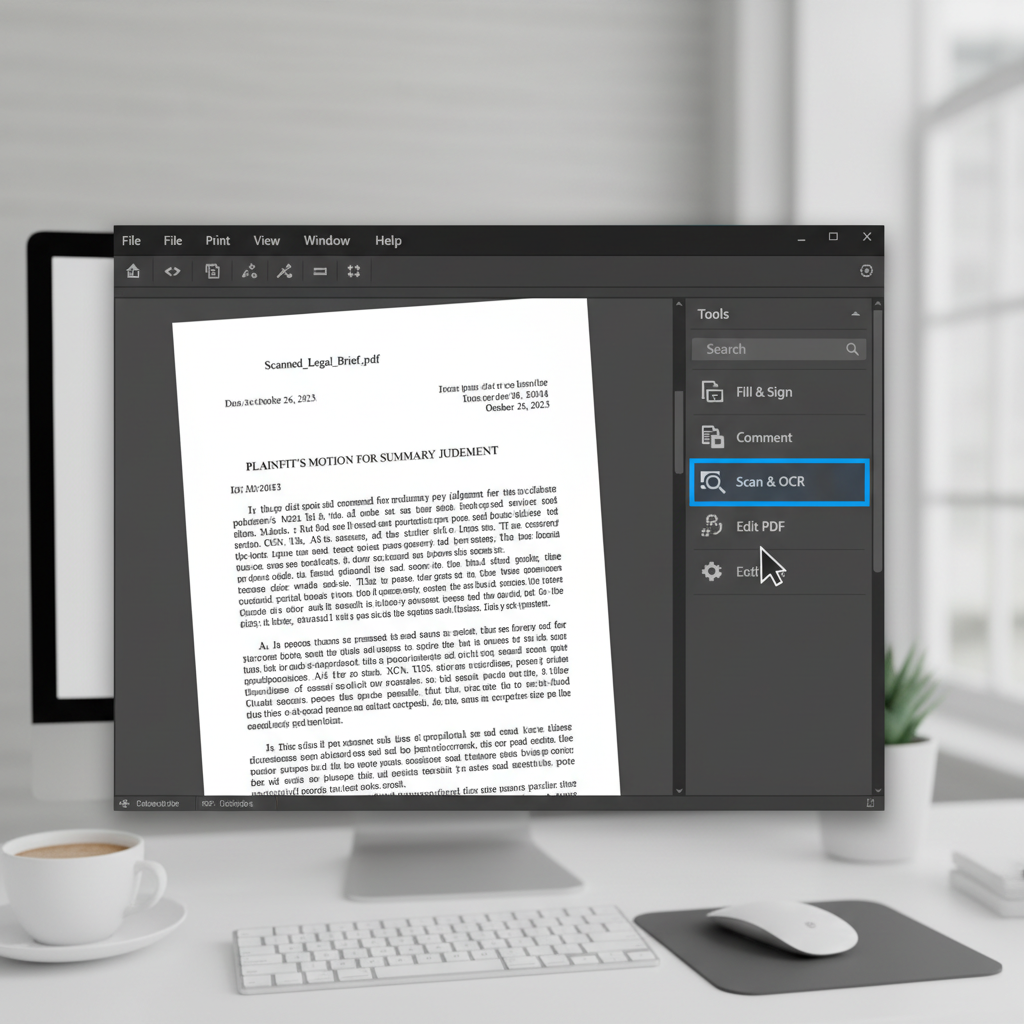
Open your document in Acrobat. Navigate to the right-hand pane or the 'Tools' menu and select 'Scan & OCR' (or 'Enhance Scans' in older versions).
Click on 'Recognize Text' in the top toolbar and select 'In This File'. Choose your document language and click the 'Recognize Text' button.
Once the OCR process completes, save the PDF to preserve the new text layer. Press Ctrl+F (or Cmd+F on Mac) to search for your text again.
Verify Text Encoding by Copying and Pasting
Use this method to determine if the PDF contains unusable or corrupted text encoding that breaks the search function.
Use WPS Office to Search and Perform OCR on PDFs
WPS Office includes a powerful, built-in PDF editor equipped with highly accurate OCR technology. Easily convert scanned documents into searchable, editable text without needing heavy or expensive software.
- 1. Open your PDF: Launch WPS Office and open your scanned or unsearchable PDF document.
- 2. Activate the OCR Tool: Navigate to the 'Tools' tab on the top ribbon and click on the 'OCR' button.
- 3. Convert the Document: Choose the option to extract the text or convert the file to a Searchable PDF, then let the system process the pages.
- 4. Search Your Text: Once converted, press Ctrl+F to bring up the search bar and easily locate your desired text.
Frequently Asked Questions
Why does my PDF look like text but I can't highlight it?
This usually means the PDF was created by a physical scanner, which essentially takes a photograph of the printed page. To the computer, it is a single flat image. You must run OCR (Optical Character Recognition) to translate that image into digital text.
Can document permissions prevent me from searching a PDF?
While the search function itself is rarely disabled, restricted security permissions might prevent text extraction or block the OCR process from running. You can check this by viewing the document's Security Properties; you may need the author's password to unlock these features.
Why do square boxes appear when I paste copied PDF text?
This indicates that the custom fonts used by the original author were not properly embedded into the PDF, or the text encoding is corrupted. The visual shapes of the letters are present, but the underlying data mapping those shapes to standard computer characters is missing.


